Urgent.News

What's breaking now, across thousands of outlets.

AI

I changed one llama.cpp flag, and my 8GB laptop GPU now runs a 35B model faster than I can read

8GB of VRAM isn't the bottleneck, your settings probably are
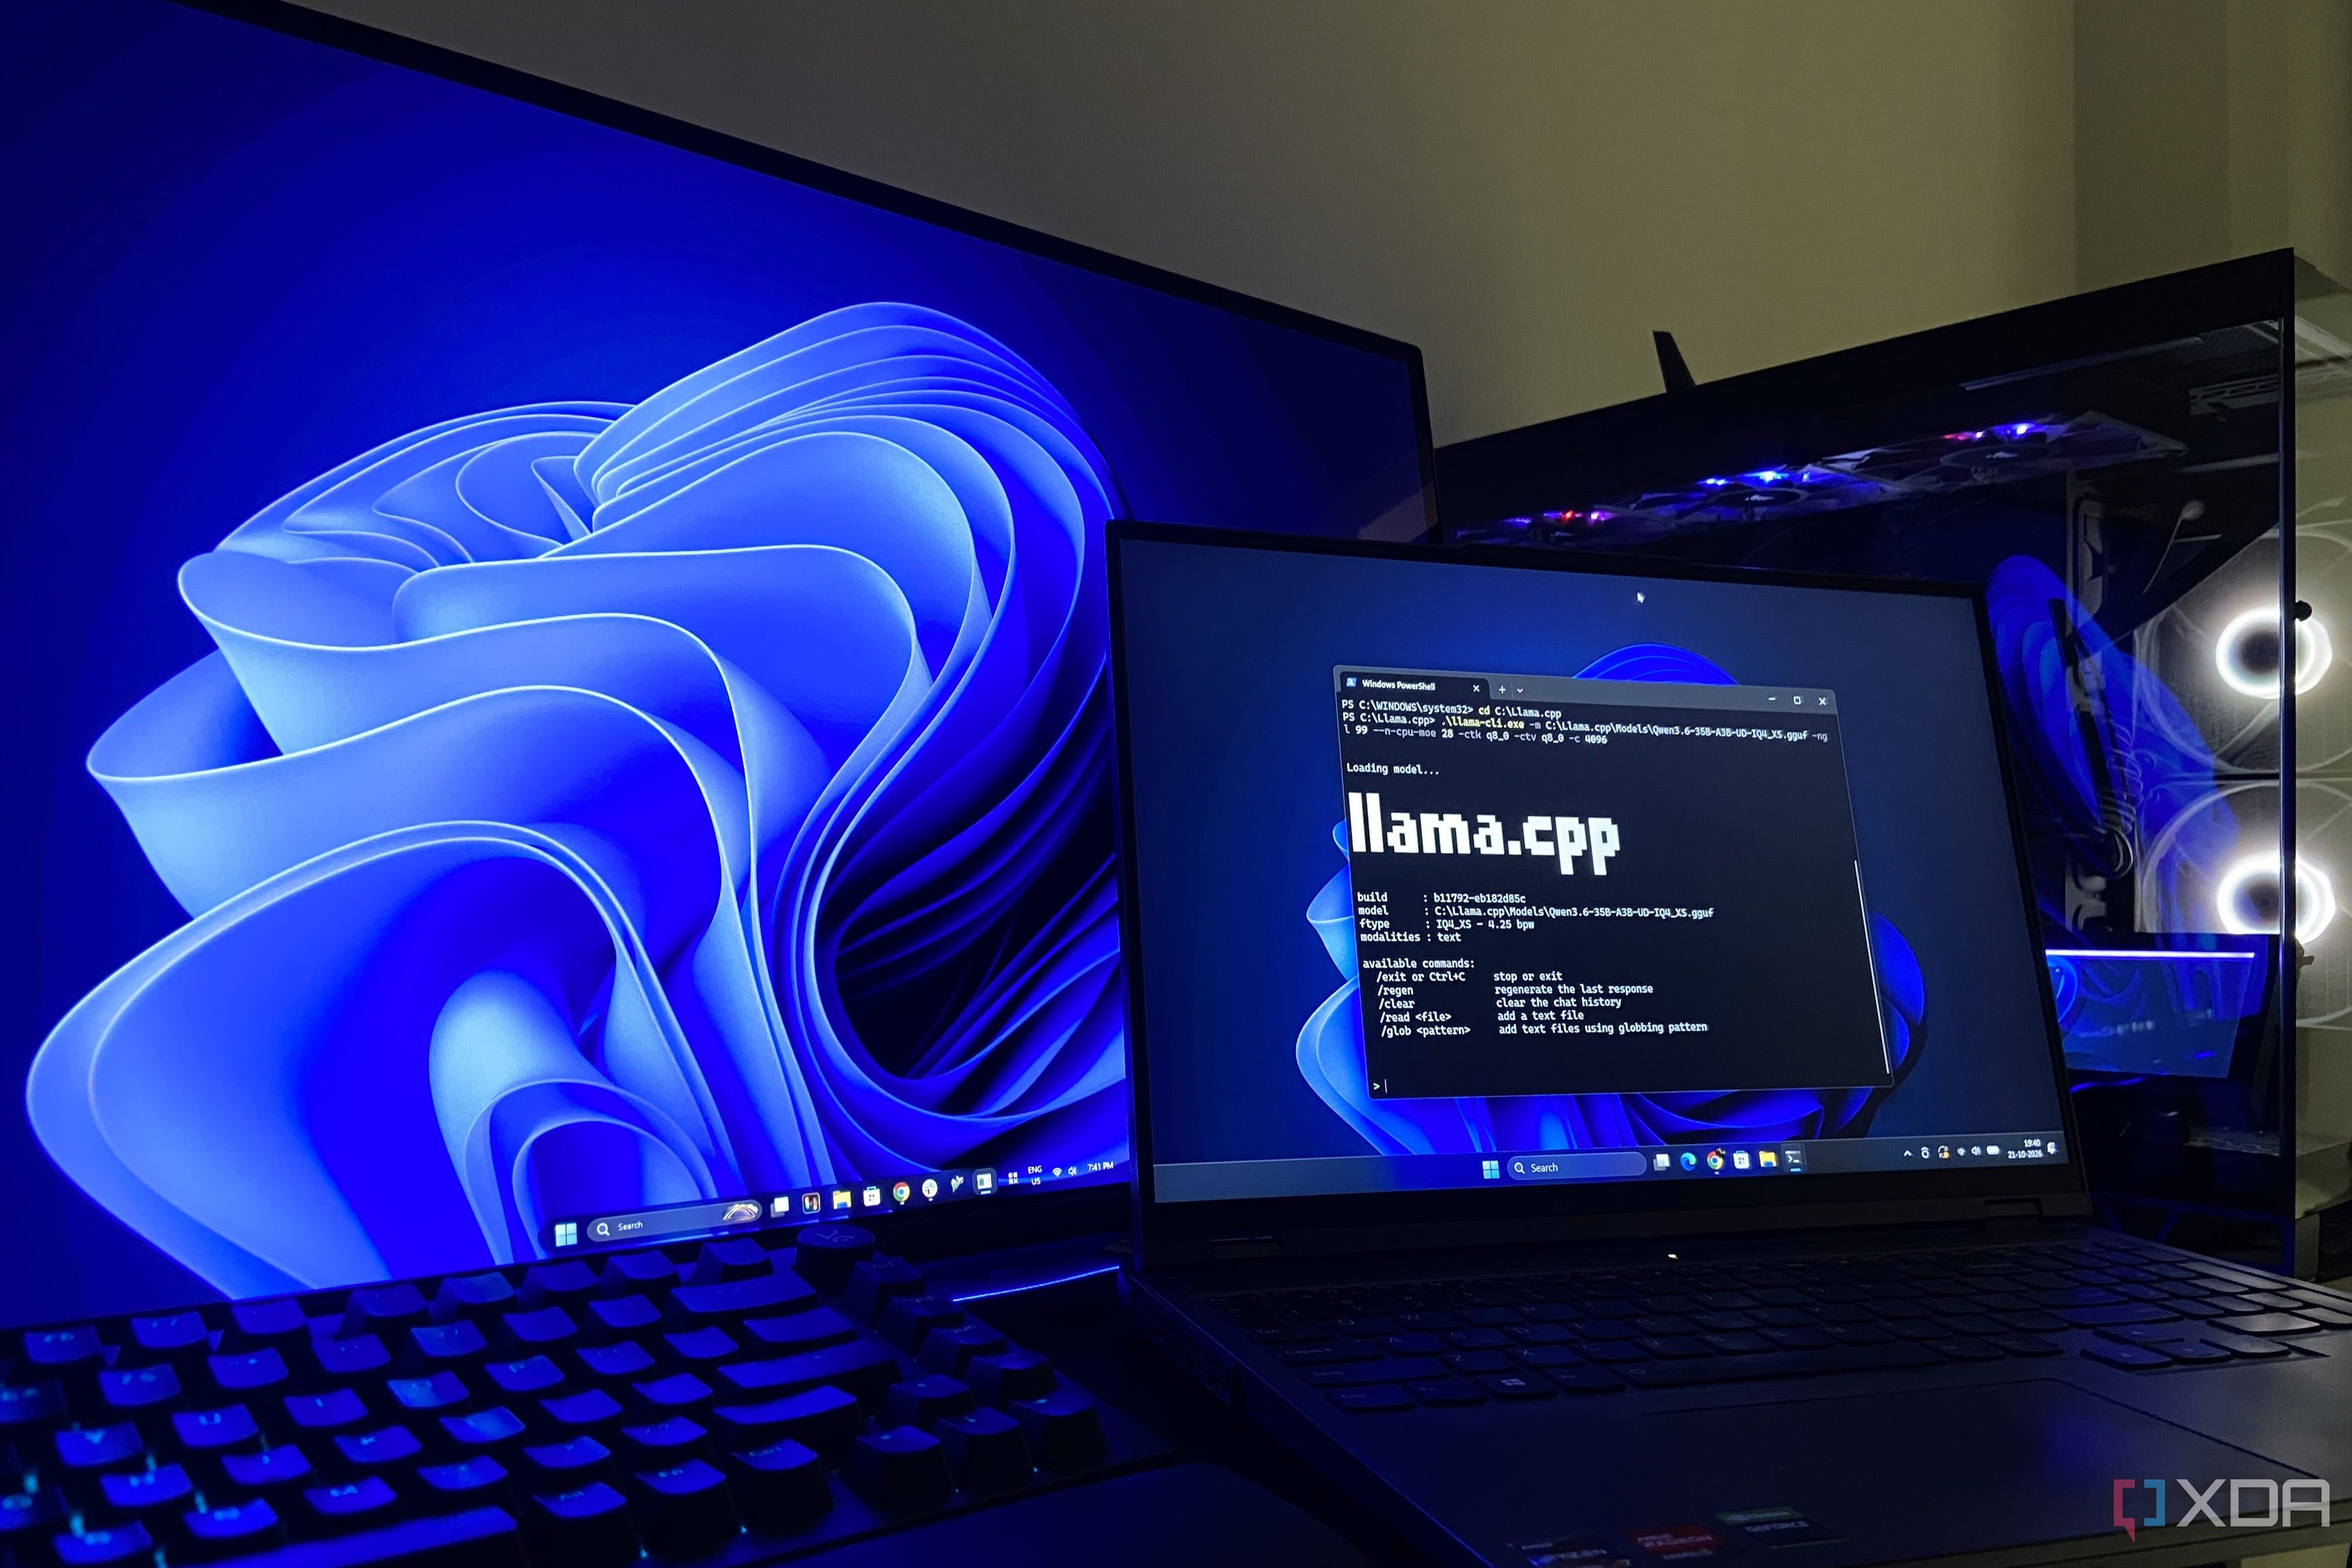
I changed one llama.cpp flag, and my 8GB laptop GPU now runs a 35B model faster than I can read

The VRAM capacity of a GPU often dictates the size of local AI models that can be self-hosted. However, there are ways to optimize smaller systems with limited VRAM to run large models. One such method involves using the llama.cpp runtime and a flag called --n-cpu-moe N. This flag helps optimize a system with lower VRAM by moving dormant expert layers to system RAM while keeping the active parts of the network on the GPU.

By testing this approach on an 8GB RTX 3070 Mobile GPU, it was discovered that it could run a 35B model, Qwen3.6-35B-A3B, at a speed of 33 tokens per second, which is significantly faster than the user's previous expectations. This optimization enables users to access and work with larger AI models on the go, even in places with no network connectivity.

Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.
Read the original at xda-developers.com →

More in AI

SlowMate AI: Do Less. Move Forward.

This is a submission for the Hacktoberfest Open-Source AI Challenge Week 3: Slow and Steady. What I Built Meet SlowMate AI , a local-first productivity assistant designed for people who feel…

  • SlowMate AI simplifies productivity by generating action plans from user input
  • Uses locally hosted Qwen2.5 3B model for privacy and control
  • Deployed on GitHub Pages with HTML/CSS/JS frontend

The Context Window Is Full Before the First Prompt — When Project Rules in Claude Code Become a Fixed Cost of Every Session

A subagent in Claude Code is supposed to answer a one-line question about the tool's documentation. It aborts before taking its first step: Prompt is too long , 347,814 tokens against a limit of…

  • Project rules in Claude Code consume 454,900 tokens before first prompt
  • Exceeds 200,000-token limit, consuming half of 1M-token context window
  • Fixed cost applies to every session, regardless of task complexity

More from Thursday 22 October →