I gave four local models the same messy spreadsheet, and not one found the cheapest graphics card on it
Local models can sometimes perform data analysis like storytelling
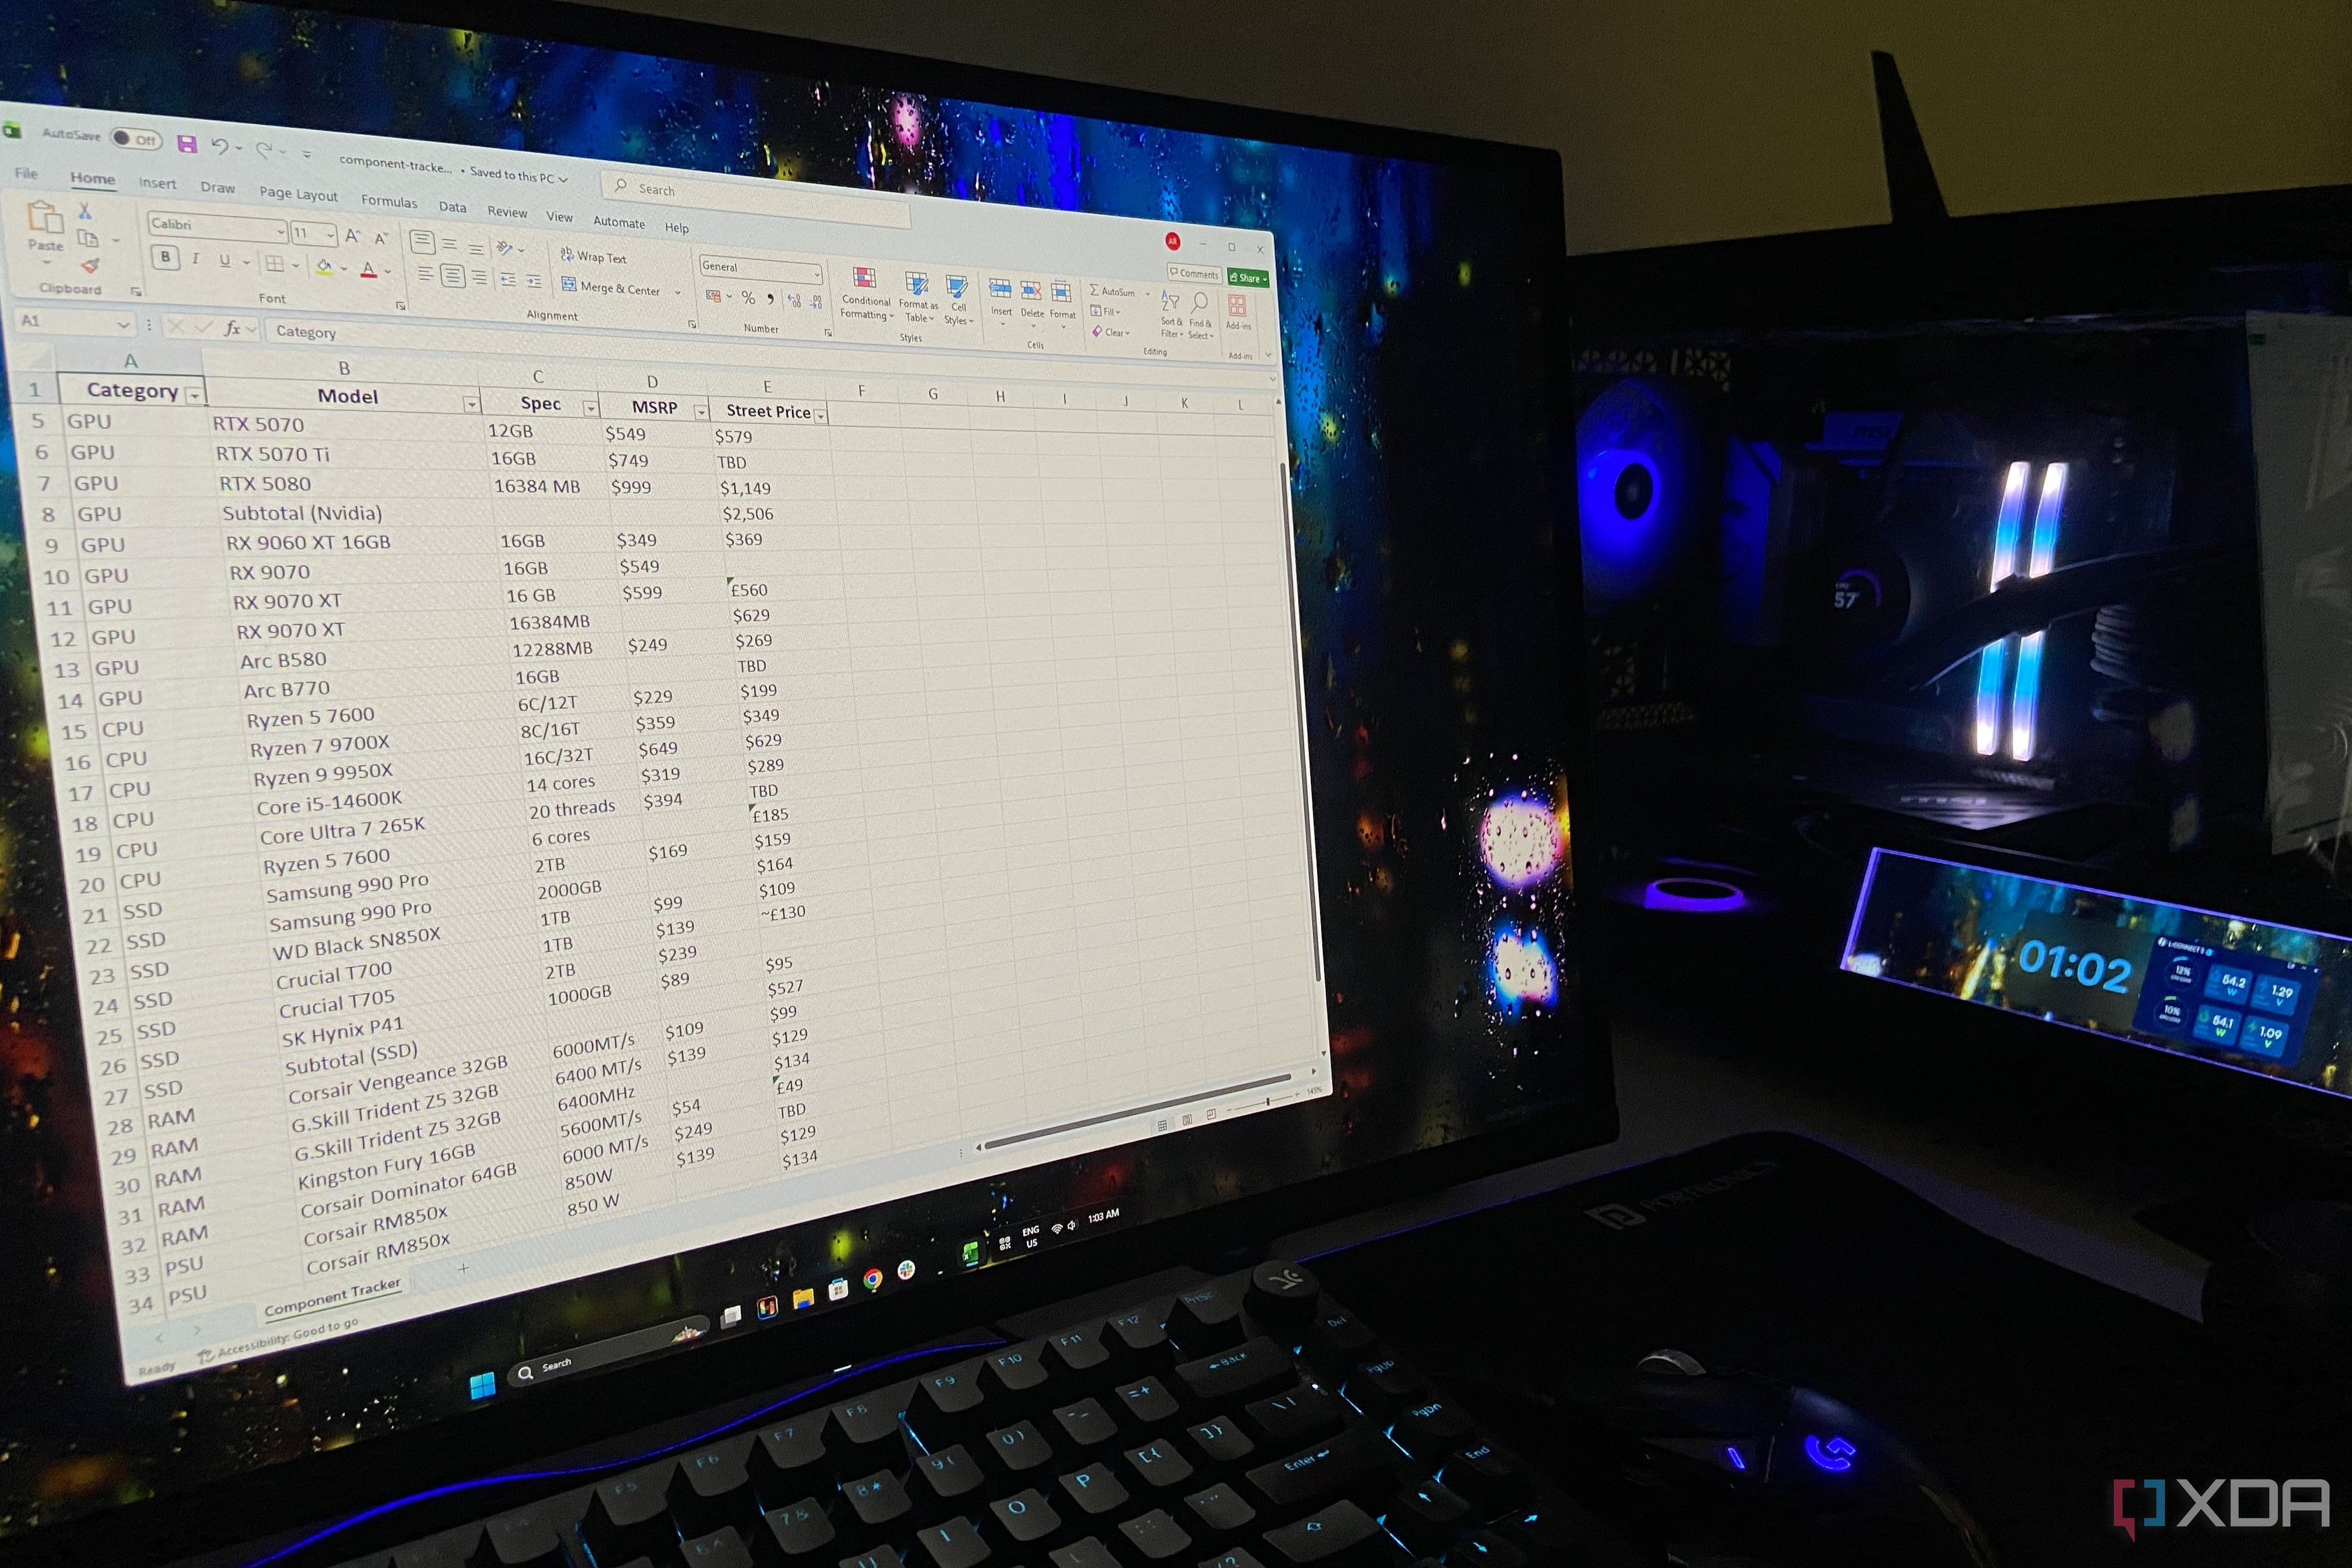
I gave four local language models the same disorganized spreadsheet full of confusing data and asked them to find the cheapest graphics card. None of the models were able to locate the correct answer. Two of the models asked questions that couldn't be reasonably inferred from the data, such as the average GPU price in Q2 2022 and the release date of the RTX 5070 Ti.
The 4B model had the most success, correctly identifying the cheapest SSD as the SK Hynix P41 in every trial. However, it struggled with the GPU average calculation, sometimes providing incorrect prices. The 3B model, while consistent in finding the correct seven cards for the average GPU question, produced inconsistent results in its answer for the GPU average, with values ranging from $466.14 to $480.43.
The 8B model performed better than the smaller models, correctly identifying the SK Hynix P41 as the cheapest 1TB SSD. However, it still failed to identify the RTX 5060 Ti, RTX 5080, and RTX 9070 XT as the cheapest GPUs, resulting in an average price of $384. The test demonstrated that while local models can process small datasets, they struggle with messy data and certain types of complex questions.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.