Supermicro wants AI factories judged by how fast they go live, not by GPU count
AI factory deployment has long been a race to secure graphics processing units, but the builders of those systems are finding that compute is only half the problem. Data pipelines, storage costs and the clock on getting a cluster running now weigh as heavily as raw horsepower. The companies supplying that infrastructure are rethinking where […] The post Supermicro wants AI factories judged by how…
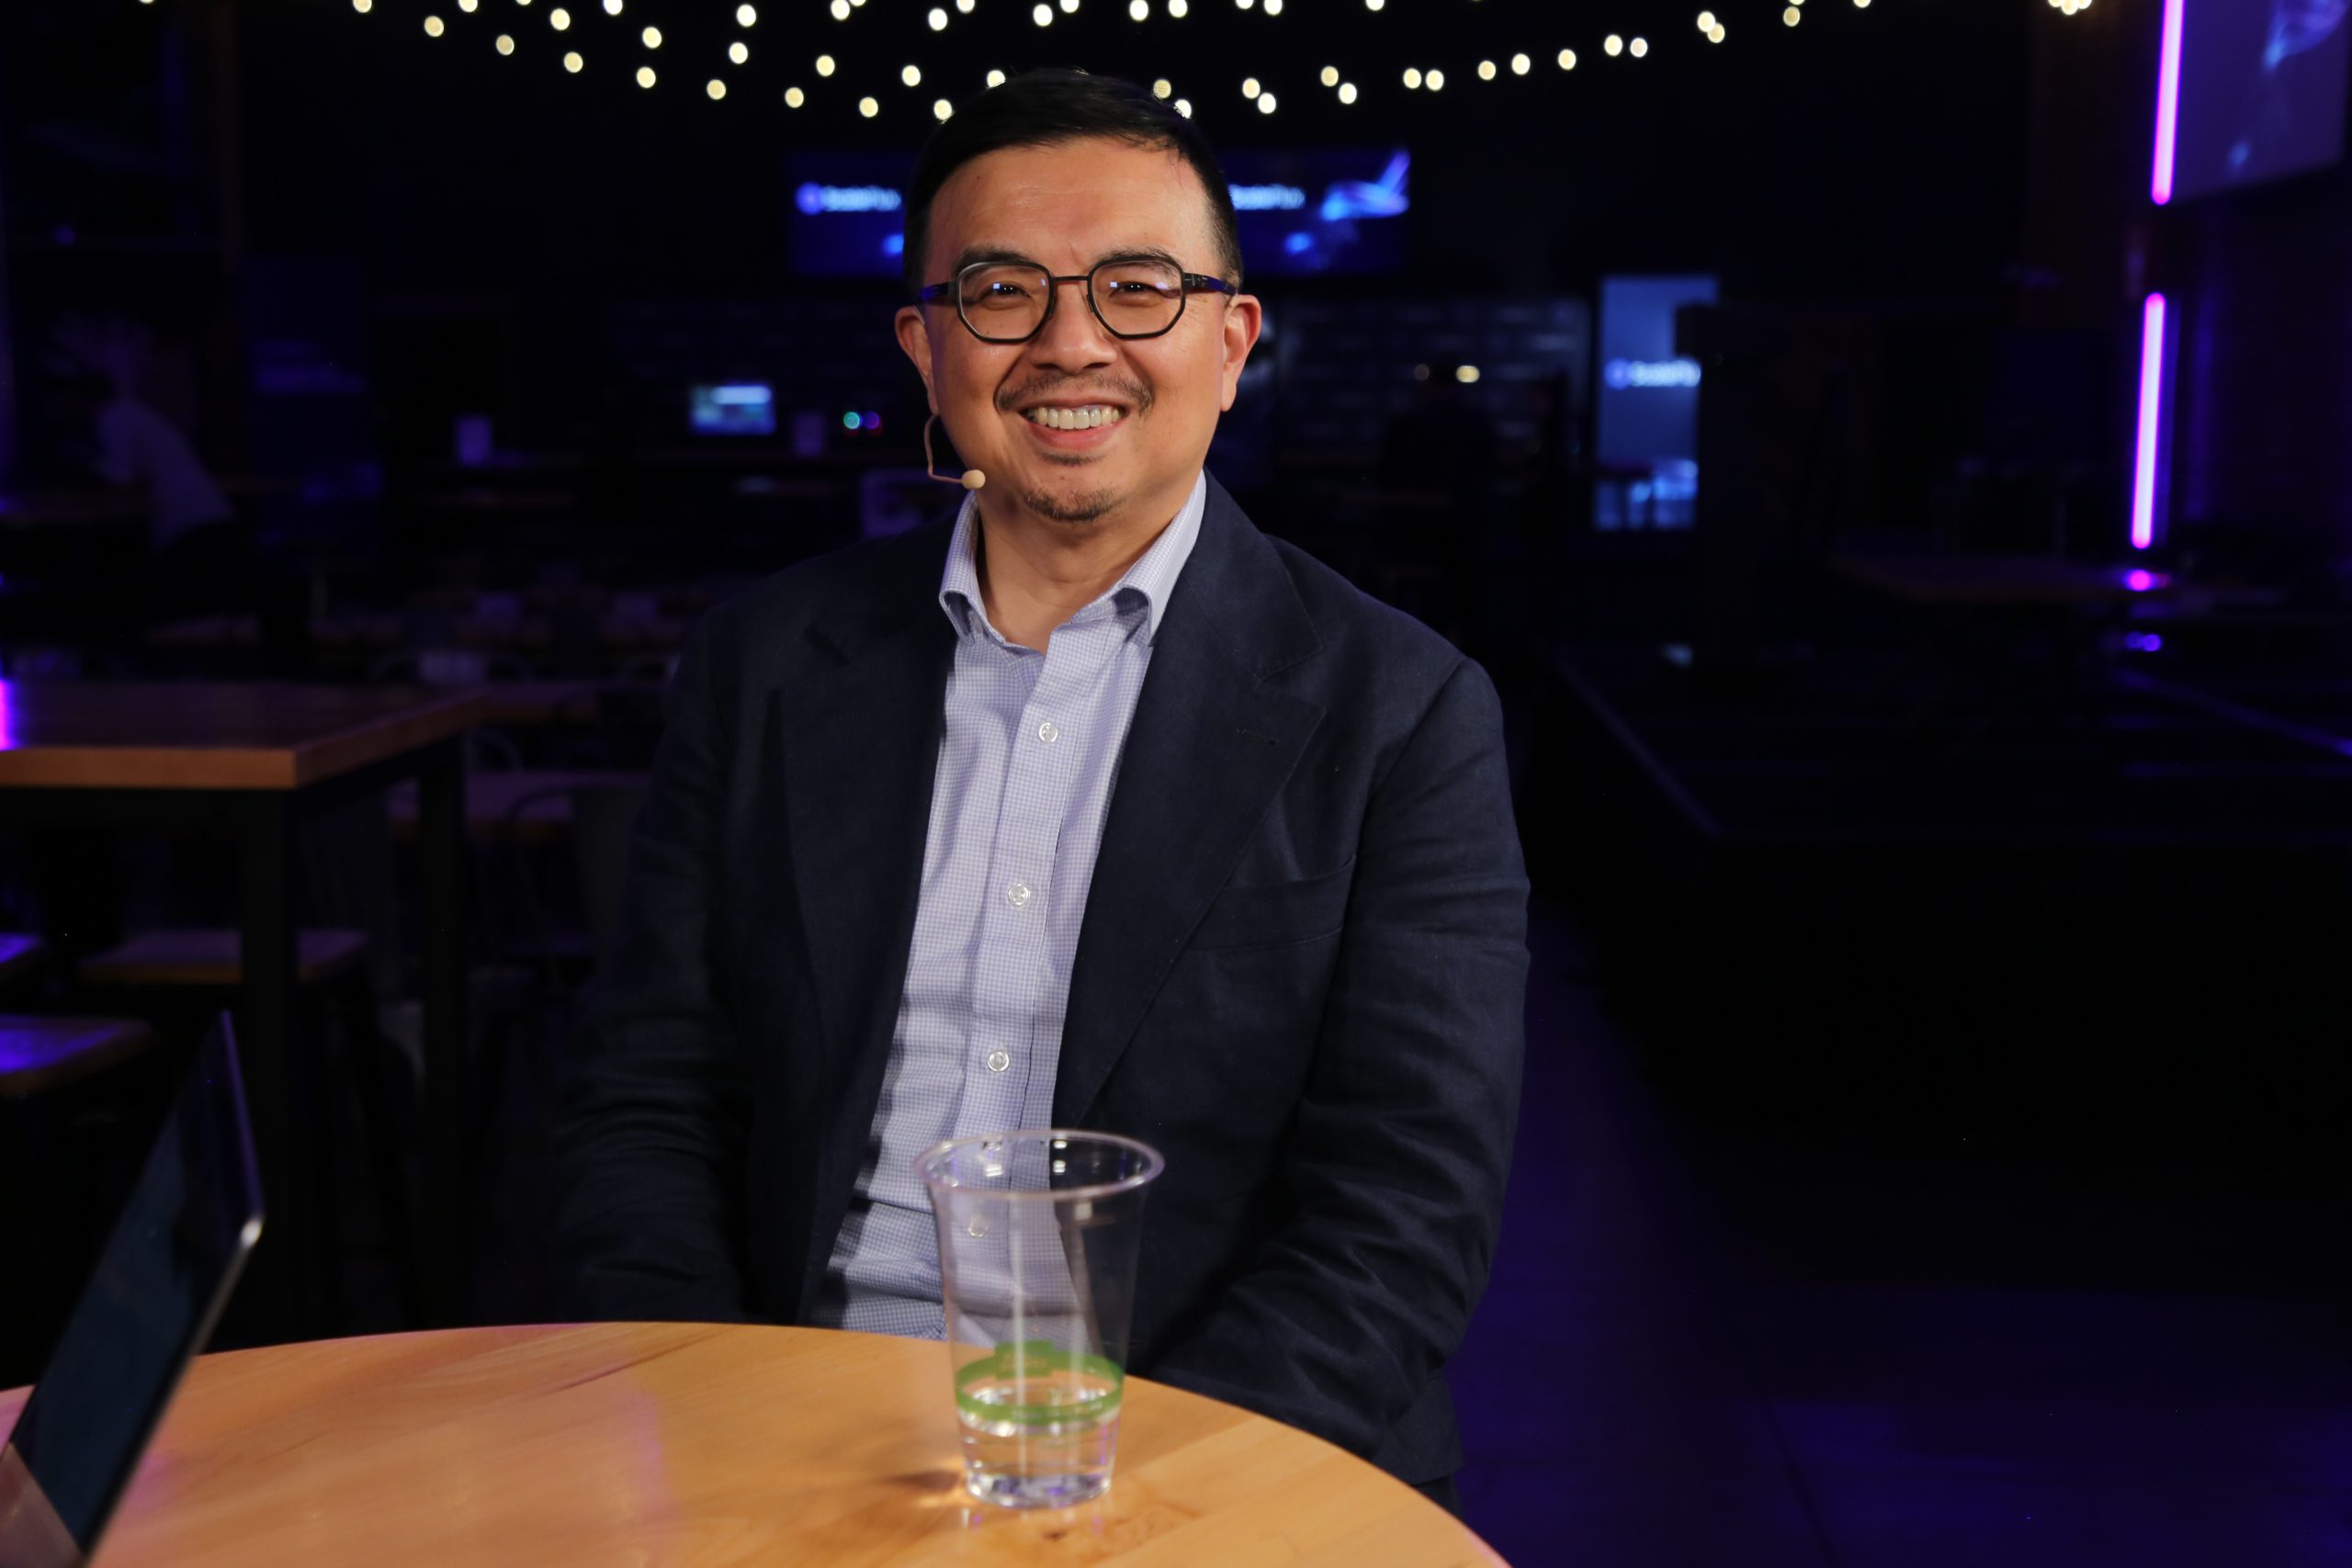
In the evolving world of AI factories, the focus is shifting away from simply securing the largest possible GPU clusters, and towards a more comprehensive approach. Ben Lee, director of solution management at Supermicro Computer Inc., explained that data pipelines, storage costs, and the time it takes to bring a cluster online are now as crucial as raw computational power.
Lee highlighted that customers are increasingly concerned with how to feed their GPU clusters with data, rather than simply how many GPUs they can deploy. This shift in priorities came after soaring prices for solid-state drives and memory made storage a significant consideration, even when the GPU budget was already secured.
To address these challenges, Supermicro is now partnering with companies like Vast Data Inc. to plan storage alongside compute. This integrated approach treats the AI factory as a single, unified system, with a dedicated team accountable for its deployment and management. This collaboration extends to Supermicro's work with Broadcom Inc., encompassing servers, storage, and specialized data center solutions that can scale from 5 megawatts to 1 gigawatt.
Lee emphasized the importance of thorough validation, pointing out that even minor issues can cause significant problems at the cluster level. He stressed the need for comprehensive testing, from individual components to entire systems and racks. This meticulous approach is now seen as a key factor in determining the pace of AI factory deployments.
As an example of their approach, Supermicro successfully deployed xAI's liquid-cooled Colossus-1 cluster in just 120 days, working with a "tiger team" that coordinated supply chain, rack, and field engineering efforts. Lee stressed that the real measure of success is not just the time it takes to deploy, but the time it takes for the entire system to become operational. This rapid deployment is crucial for customers who are investing significant resources and want to see their entire AI factory online quickly.
Written by urgent.news from SiliconANGLE's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.