I recycled my old GTX 1080 to run local LLMs, and it still keeps up with Qwen and Gemma
My discontinued Nvidia card still has a lot of life left in it
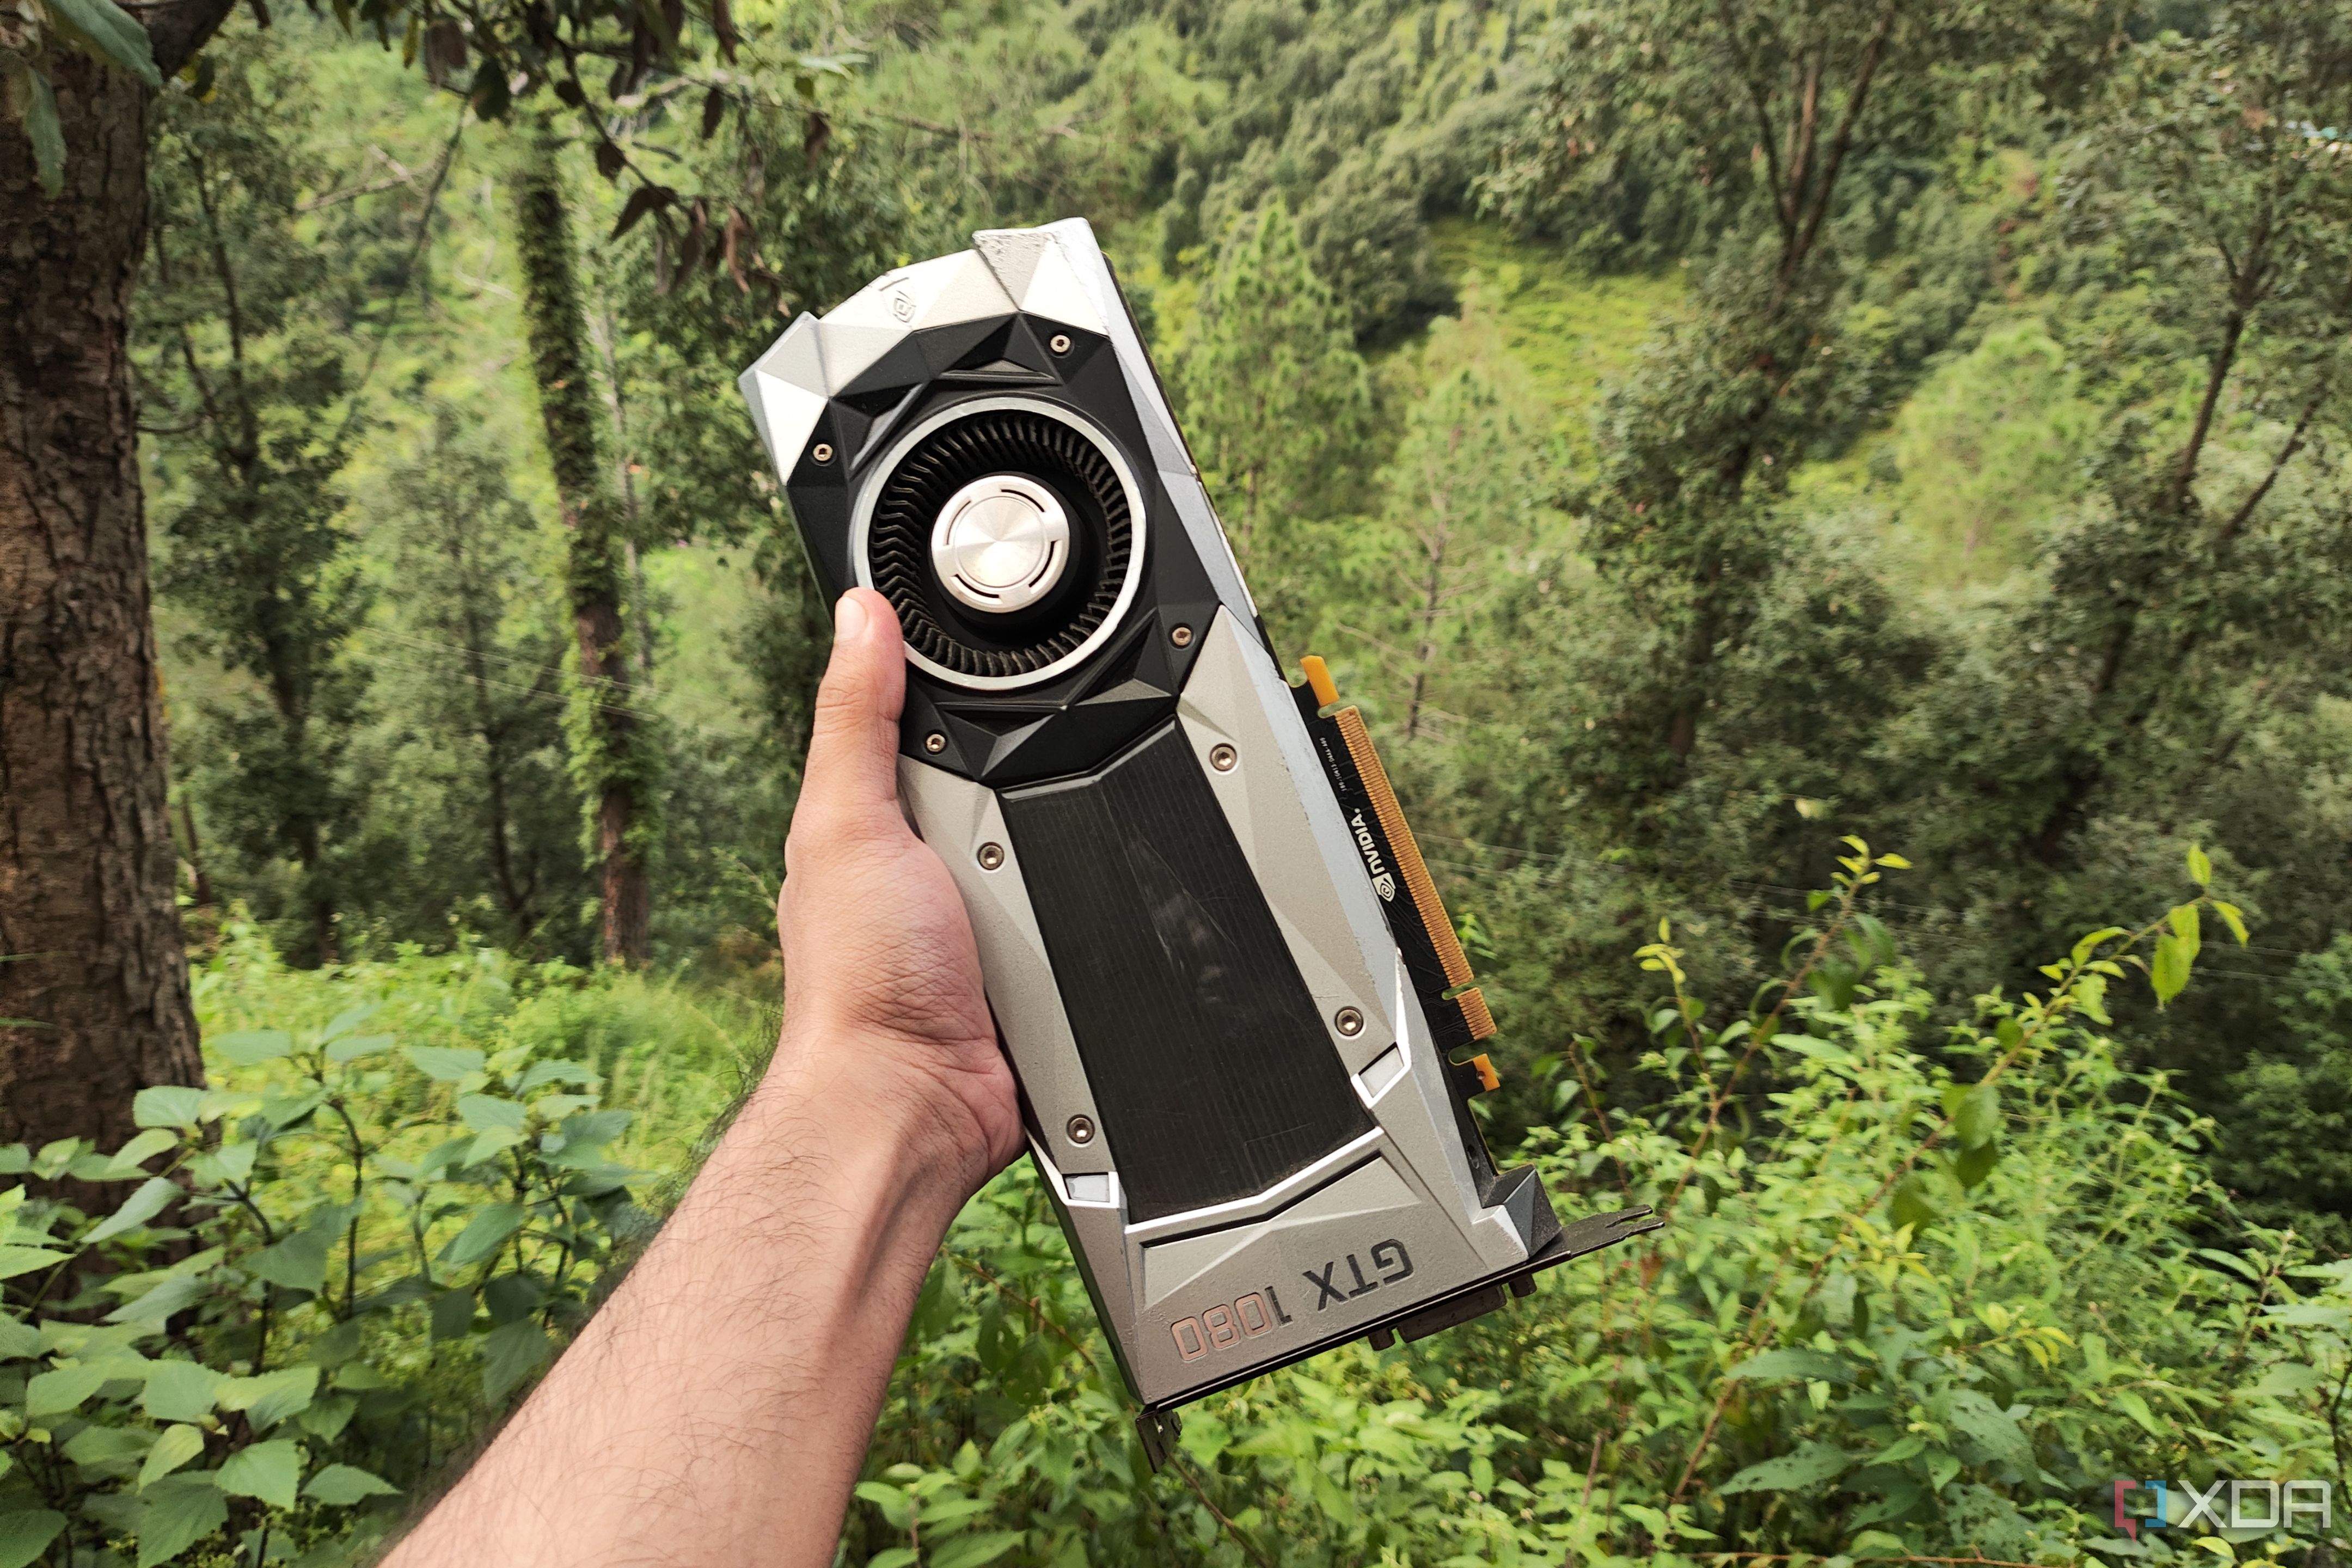
The author decided to give a second life to their old GTX 1080 graphics card by repurposing it for local large language models (LLMs) tasks. Despite the GTX 1080 being 10 years old and outdated, it still managed to keep up with more modern models like Qwen and Gemma. The author had initially considered upgrading their hardware but eventually turned to repurposing their old system for tinkering projects.
The main challenge was ensuring compatibility with the Proxmox virtualization platform, which required specific Nvidia drivers. After successfully installing the drivers and configuring the LXC environment, the author was able to run llama.cpp, a lightweight inference engine, on their GTX 1080. The key advantage of using Mixture-of-Experts (MoE) models is that they allow for efficient use of both GPU and CPU resources.
In this case, the GTX 1080 with 8GB VRAM could handle a 35B parameter model like Qwen3.6-35B-A3B by offloading most of the computation to the CPU and system RAM, thus avoiding VRAM constraints.
Rewritten by urgent.news; may contain errors — check the original.
Source: xda-developers.com