I gave my 9-year-old laptop server a local LLM job every night, and it reads my homelab logs so I don’t have to
My morning log check now takes seconds.
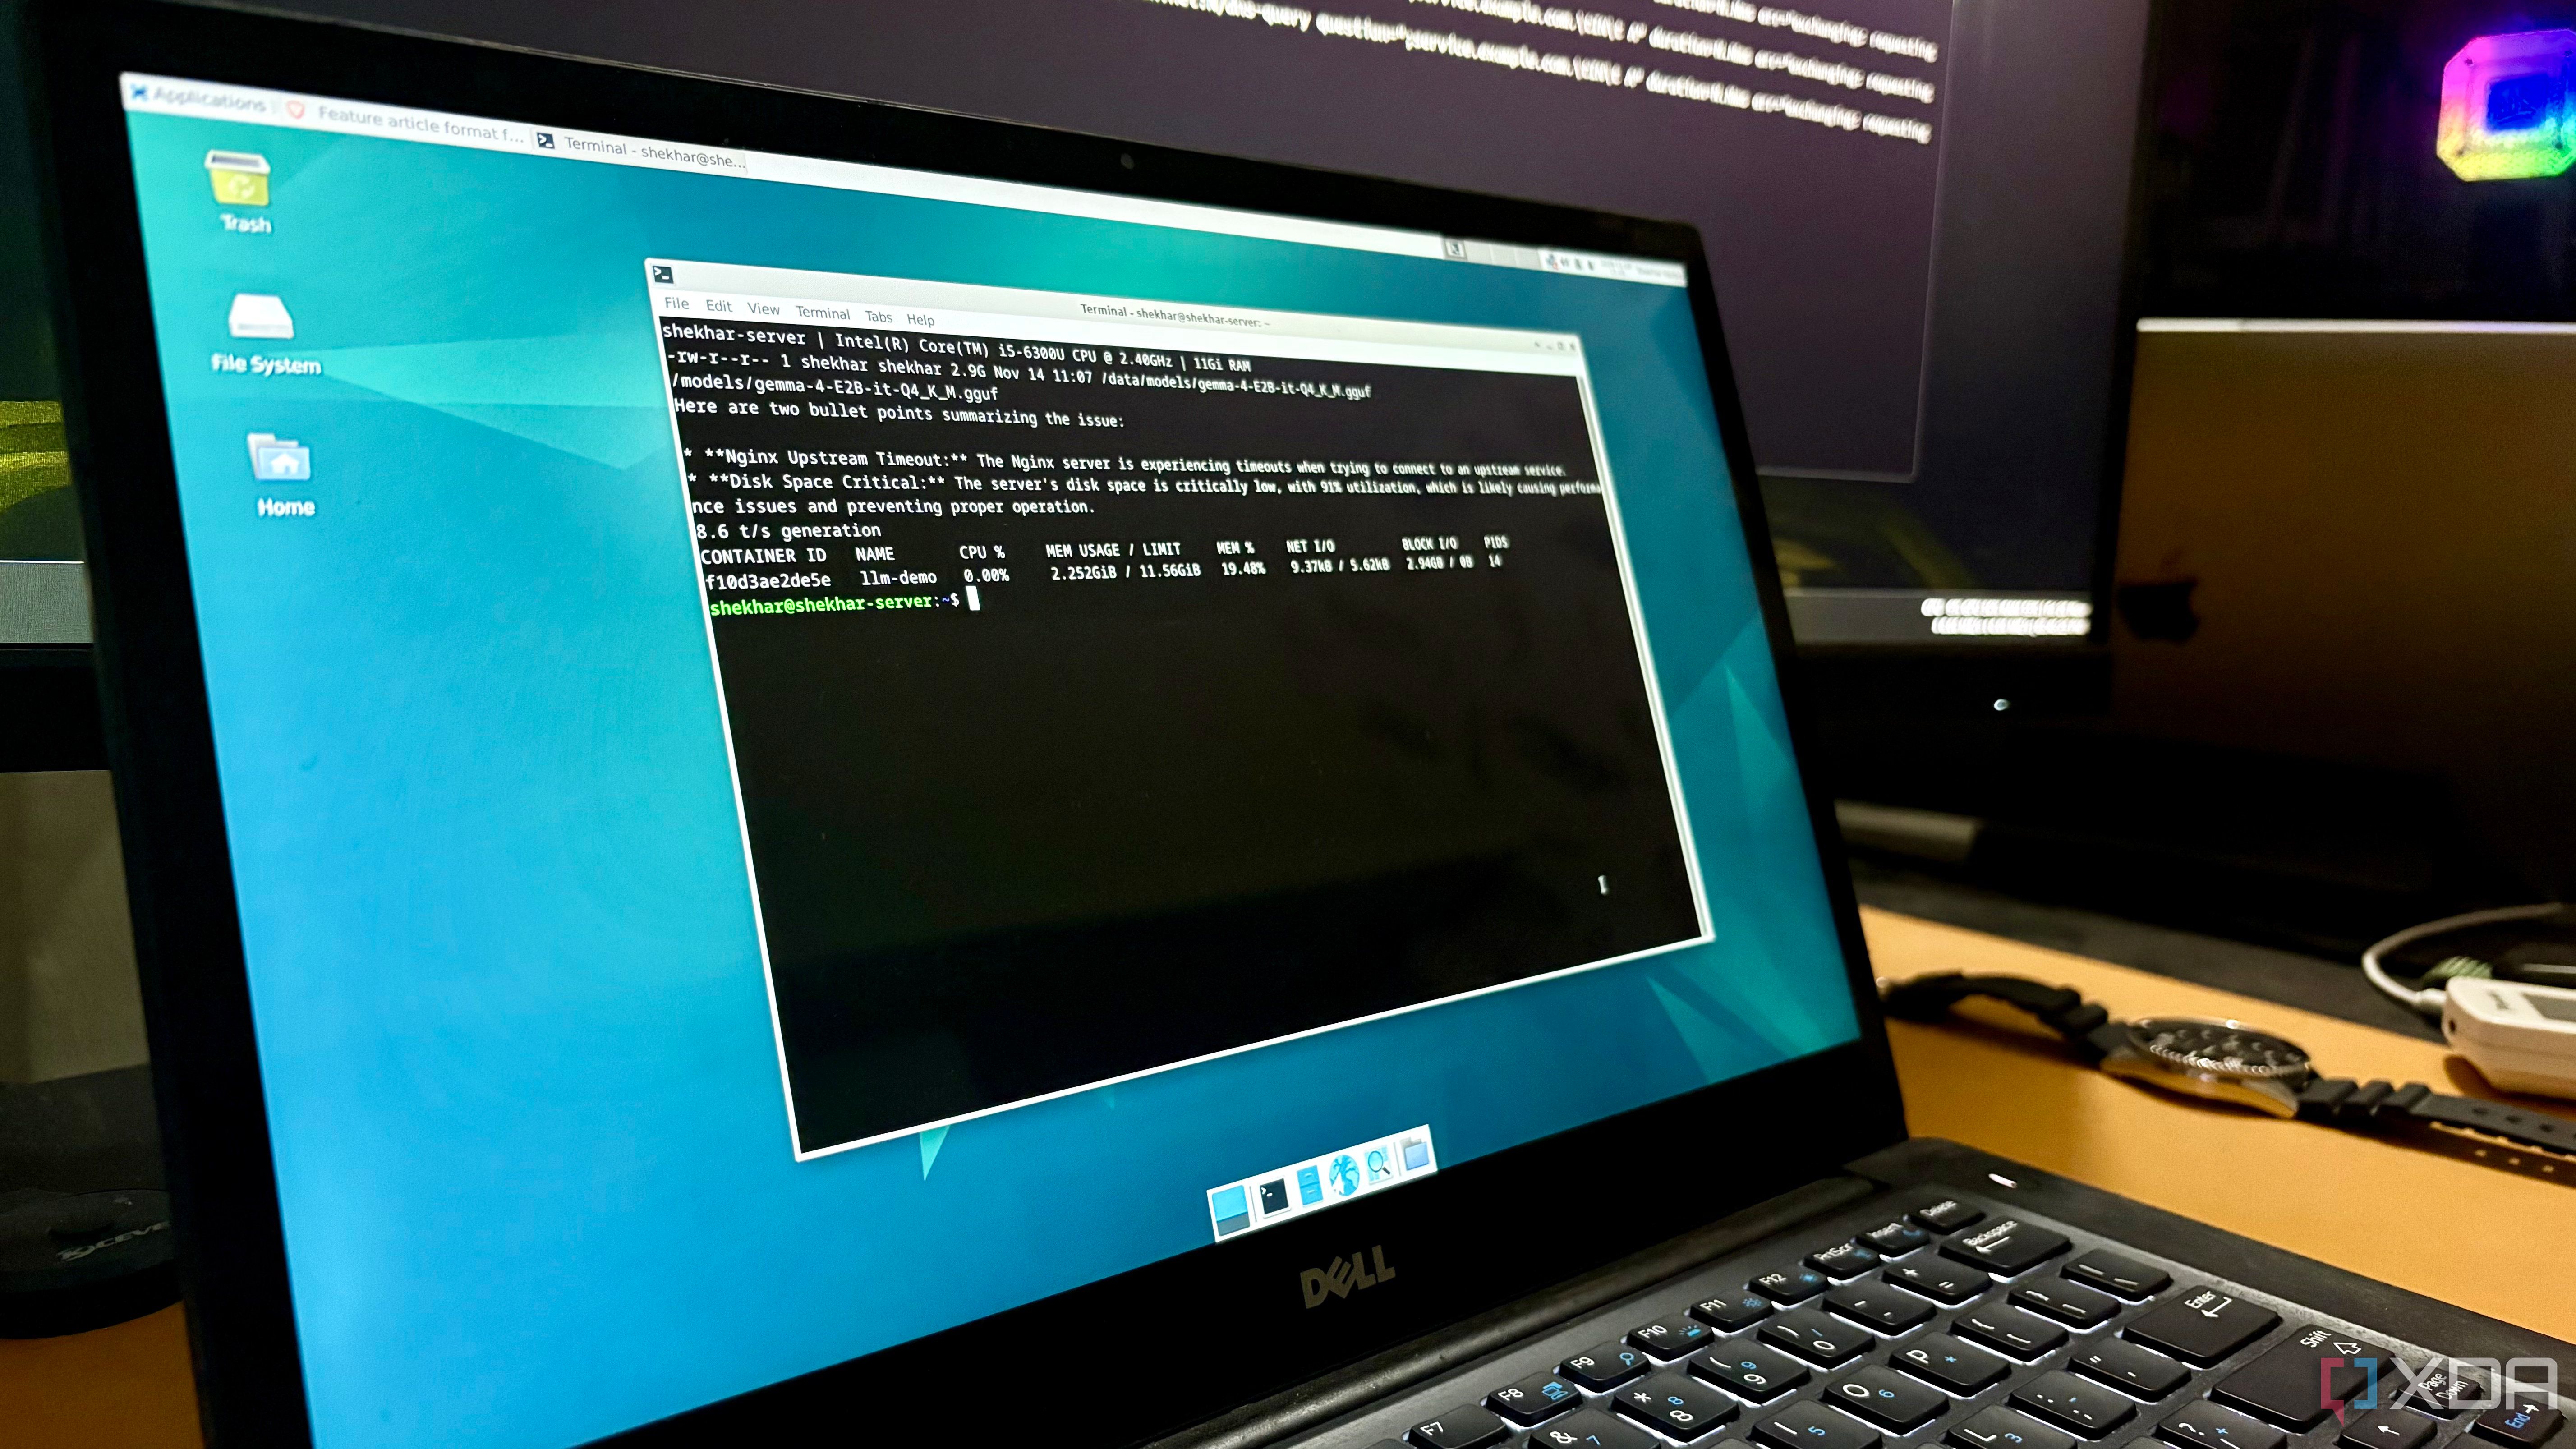
A journalist repurposed a 9-year-old Dell Latitude laptop, originally destined for recycling, into a home server running over 30 containers. Despite the laptop's mediocre CPU and minimal memory, the writer successfully hosted a local large language model (LLM) using Gemma 4 E2B Q4_K_M on llama.cpp. The LLM was configured to run nightly at 6 AM, generating a concise report of issues from the servers' logs.
Due to memory constraints, the model only operated for two minutes before being removed from the container. The writer initially encountered difficulties with the interactive prompt but switched to llama-server, which proved more effective. The LLM successfully flagged errors and issues, such as an unhealthy AdGuard Home container, providing the writer with valuable insights into their homelab's performance.
Despite some inaccuracies, the model offered a helpful summary of errors, enabling the writer to address problems efficiently.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.
This story
This is one outlet's version. Read the fullest account.