I gave my local LLM one job that runs every morning, and it's done more for me than a year of chatting with it
Finally putting local LLMs to good use.
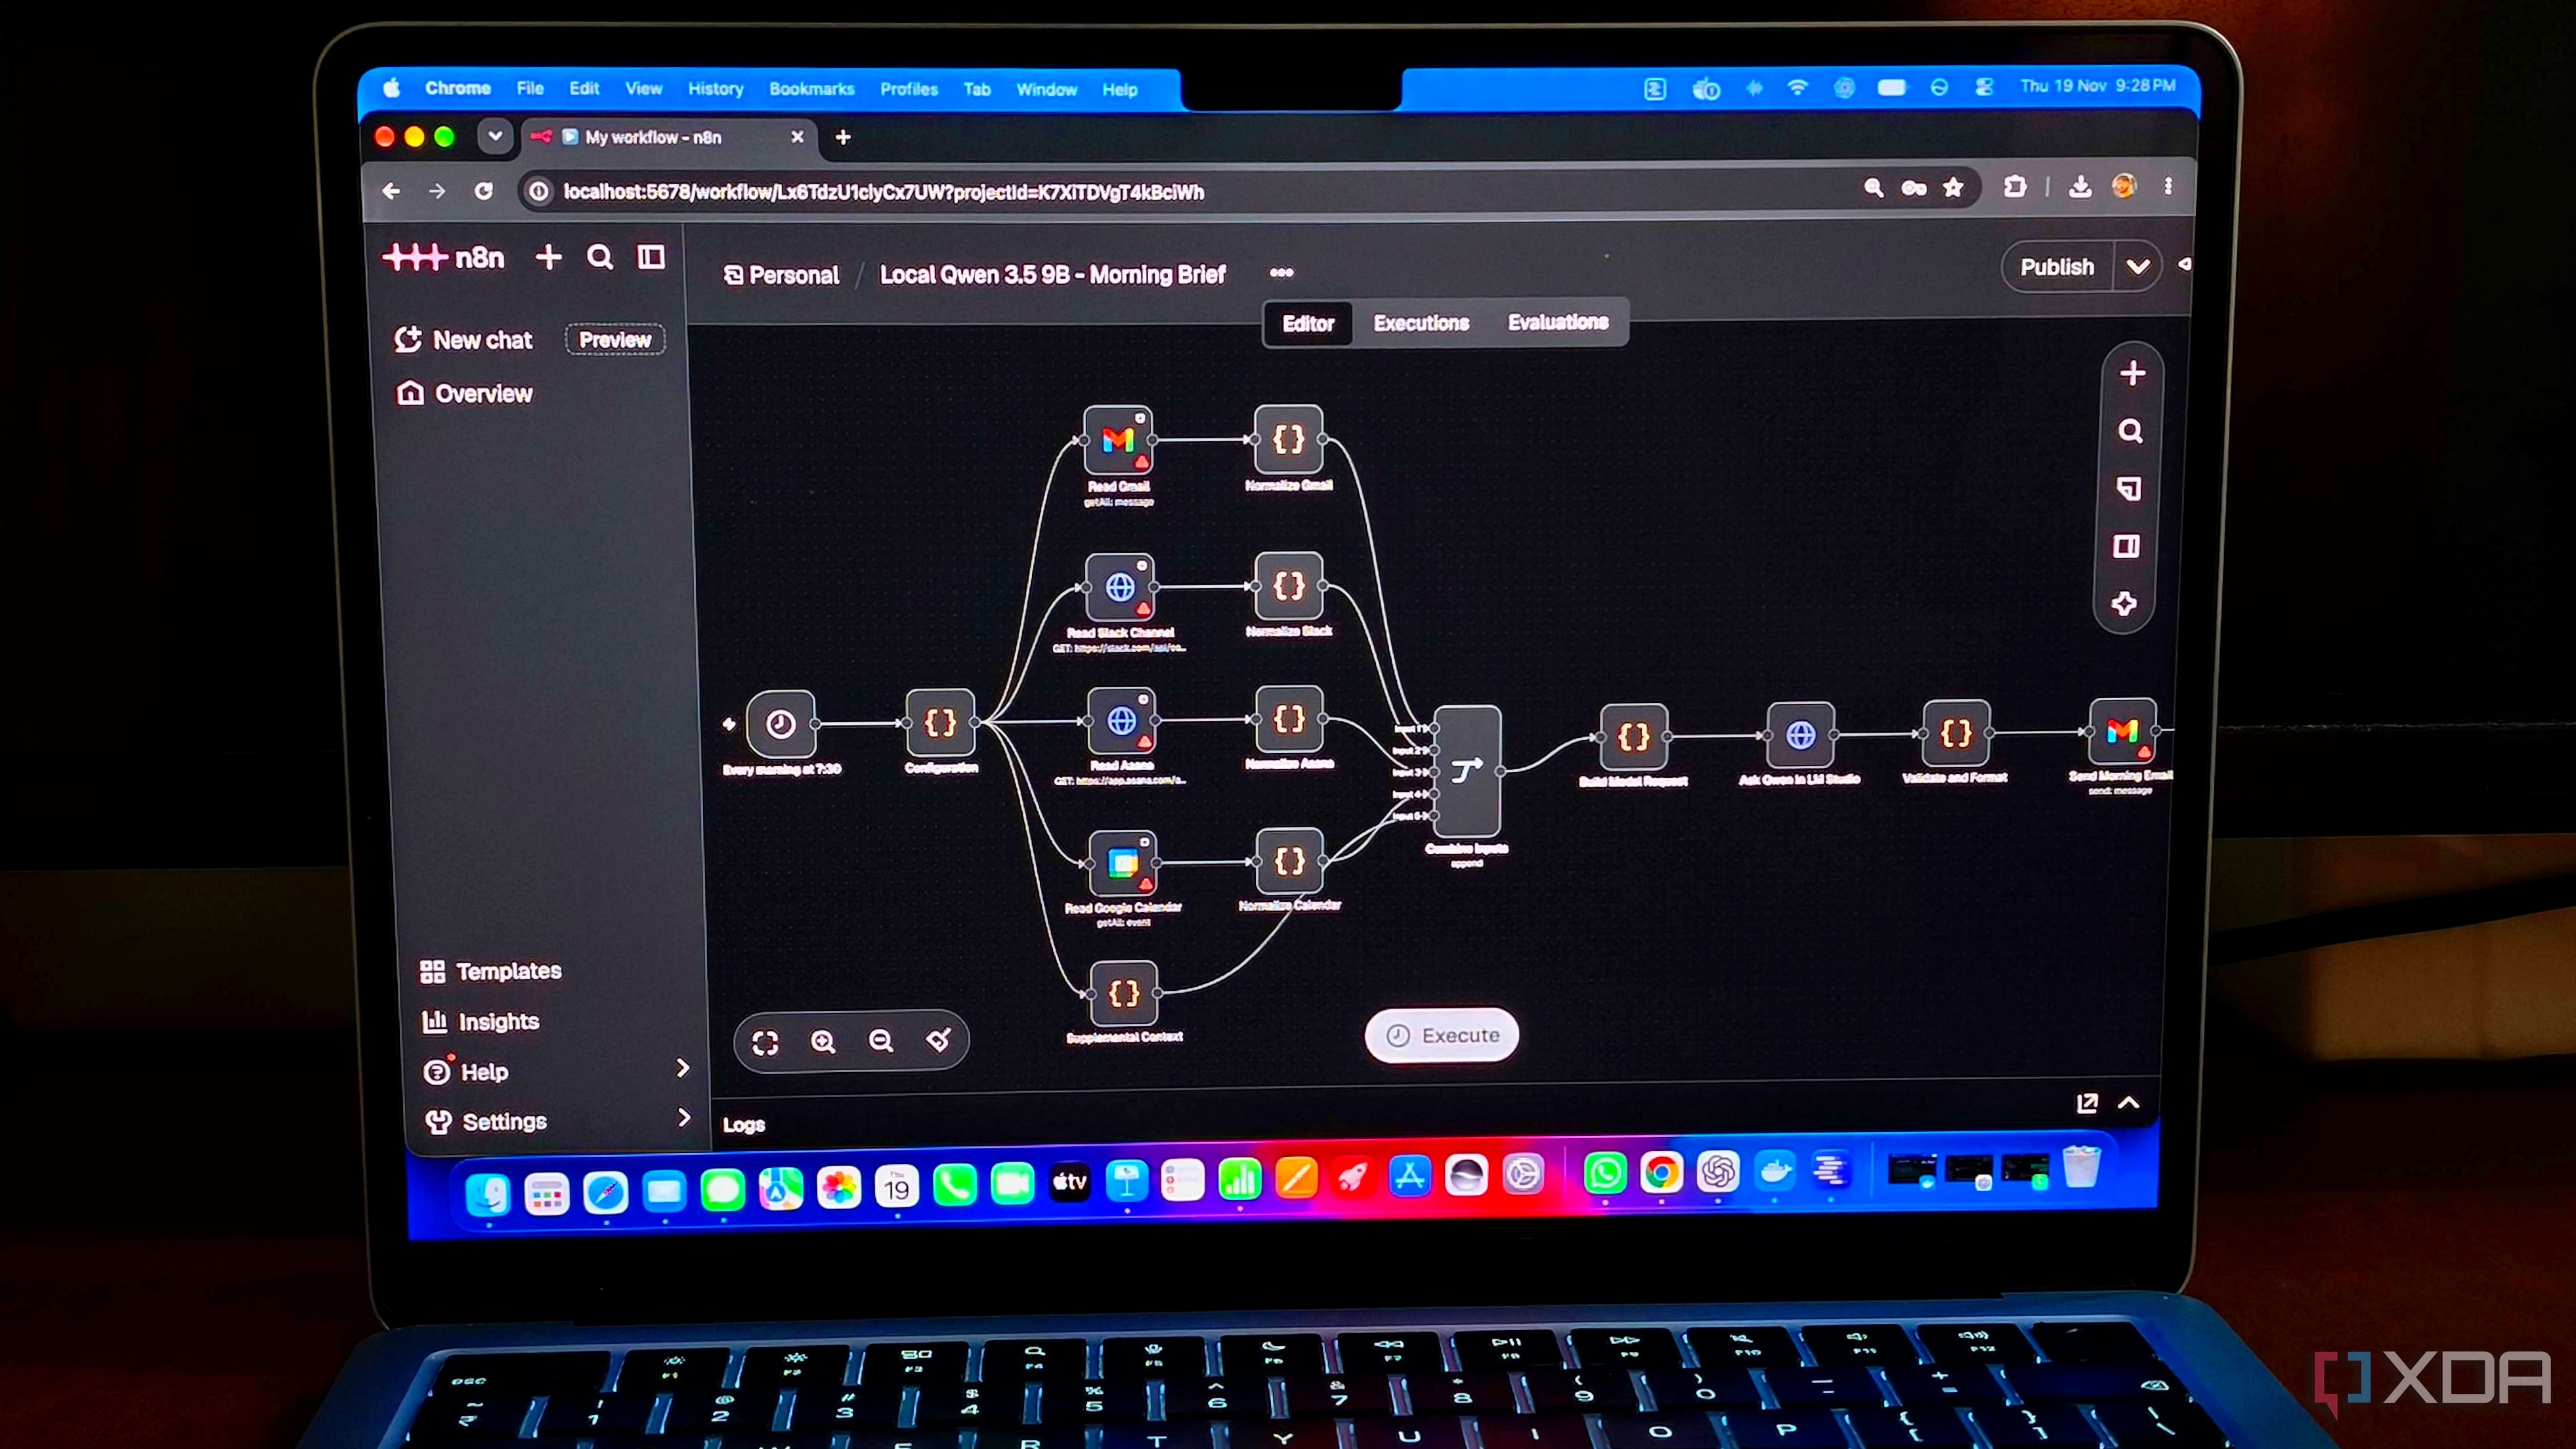
A journalist tested local language models (LLMs) to discover that most were poor chatbots, slow, inaccurate, and required multiple prompts to accomplish tasks that ChatGPT handled effortlessly. The journalist believed automations were a better use for smaller models and created a daily briefing for their morning routine. This briefing gathered information from various work apps, including emails, Slack messages, tasks in Asana, calendar events, notes, and dashboard data.
The journalist used n8n for automations and Qwen 3.5 9B, running locally on a MacBook Air with 16GB of memory. The workflow fed the information to the LLM, which returned a structured briefing with priorities, pending tasks, pending requests, and meetings requiring preparation. The briefing provided context for each item and linked back to original sources, allowing the journalist to quickly access specific emails or tasks.
The LLM identified commitments, approaching deadlines, unresolved requests, and items requiring attention. It also consolidated relevant updates from multiple conversations and distinguished between work needing completion and tasks waiting for someone else's response. The journalist believes local inference provides more control over how information is processed and eliminates cloud AI provider dependency and per-request API charges.
They are now considering other tasks where a local LLM could provide valuable background work, such as monitoring GitHub releases, developer blogs, RSS feeds, sales data, meeting transcripts, and more.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.