Lawyer builds private AI server with eight used Nvidia V100 GPUs
A lawyer runs DeepSeek V4.1 Flash on eight used 2018-era Nvidia V100 GPUs at up to 215 tokens/s, keeping case files in the office.
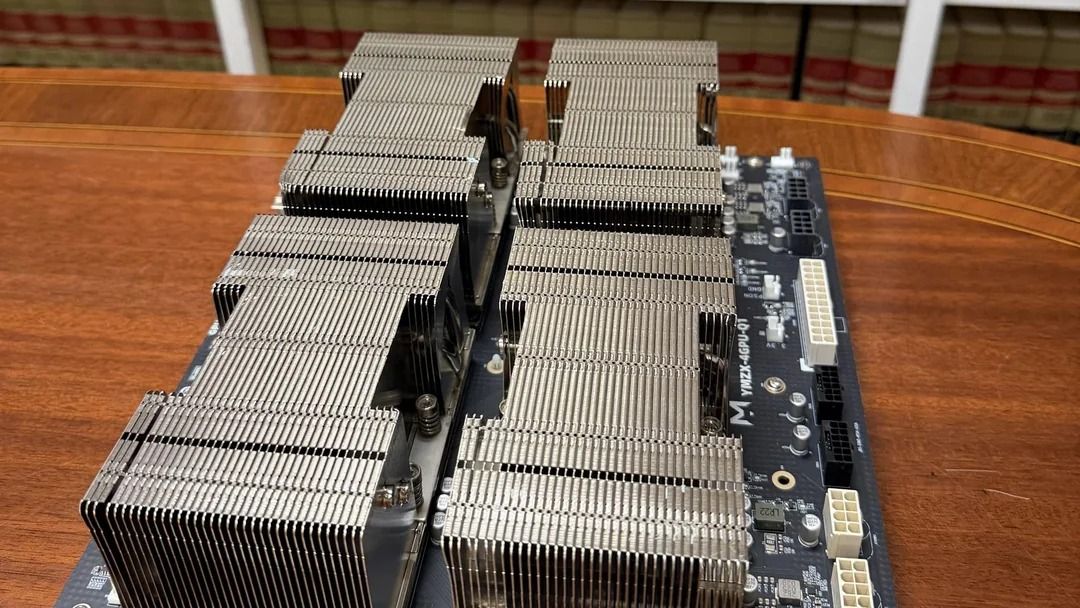
A lawyer in the Reddit community shared their experience building a private AI server utilizing eight used Nvidia Tesla V100 data center GPUs. The server, which runs the DeepSeek V4.1 Flash model, employs two 4-card SXM2 NVLink boards, four PEX switches, and SlimSAS cables. It sits on a Gigabyte Threadripper Pro motherboard with a 12-core 3945WX CPU and 8x 32GB DDR4 RDIMM memory.
The GPUs, each with 32GB of HBM2 at 900 GB/s, are connected through NVLink for 128GB per board, with communication between boards occurring over PCIe. SlimSAS cables link the boards to the host through four PEX switches. The server primarily handles legal document processing, reading folders of records, extracting key information, and drafting summaries.
It can process up to 215 tokens per second for code generation and up to 118 tokens per second for legal writing. The server is currently in use and has improved performance after addressing initial issues with power and memory. The lawyer believes this setup represents a cost-effective way to run large language models locally, protecting client data privacy.
Written by urgent.news from Tom's Hardware's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.