Ollama was holding back my "weak" Intel GPU, and one swap turned it into a solid local AI setup
My Intel Arc GPU finally became a useful local AI machine
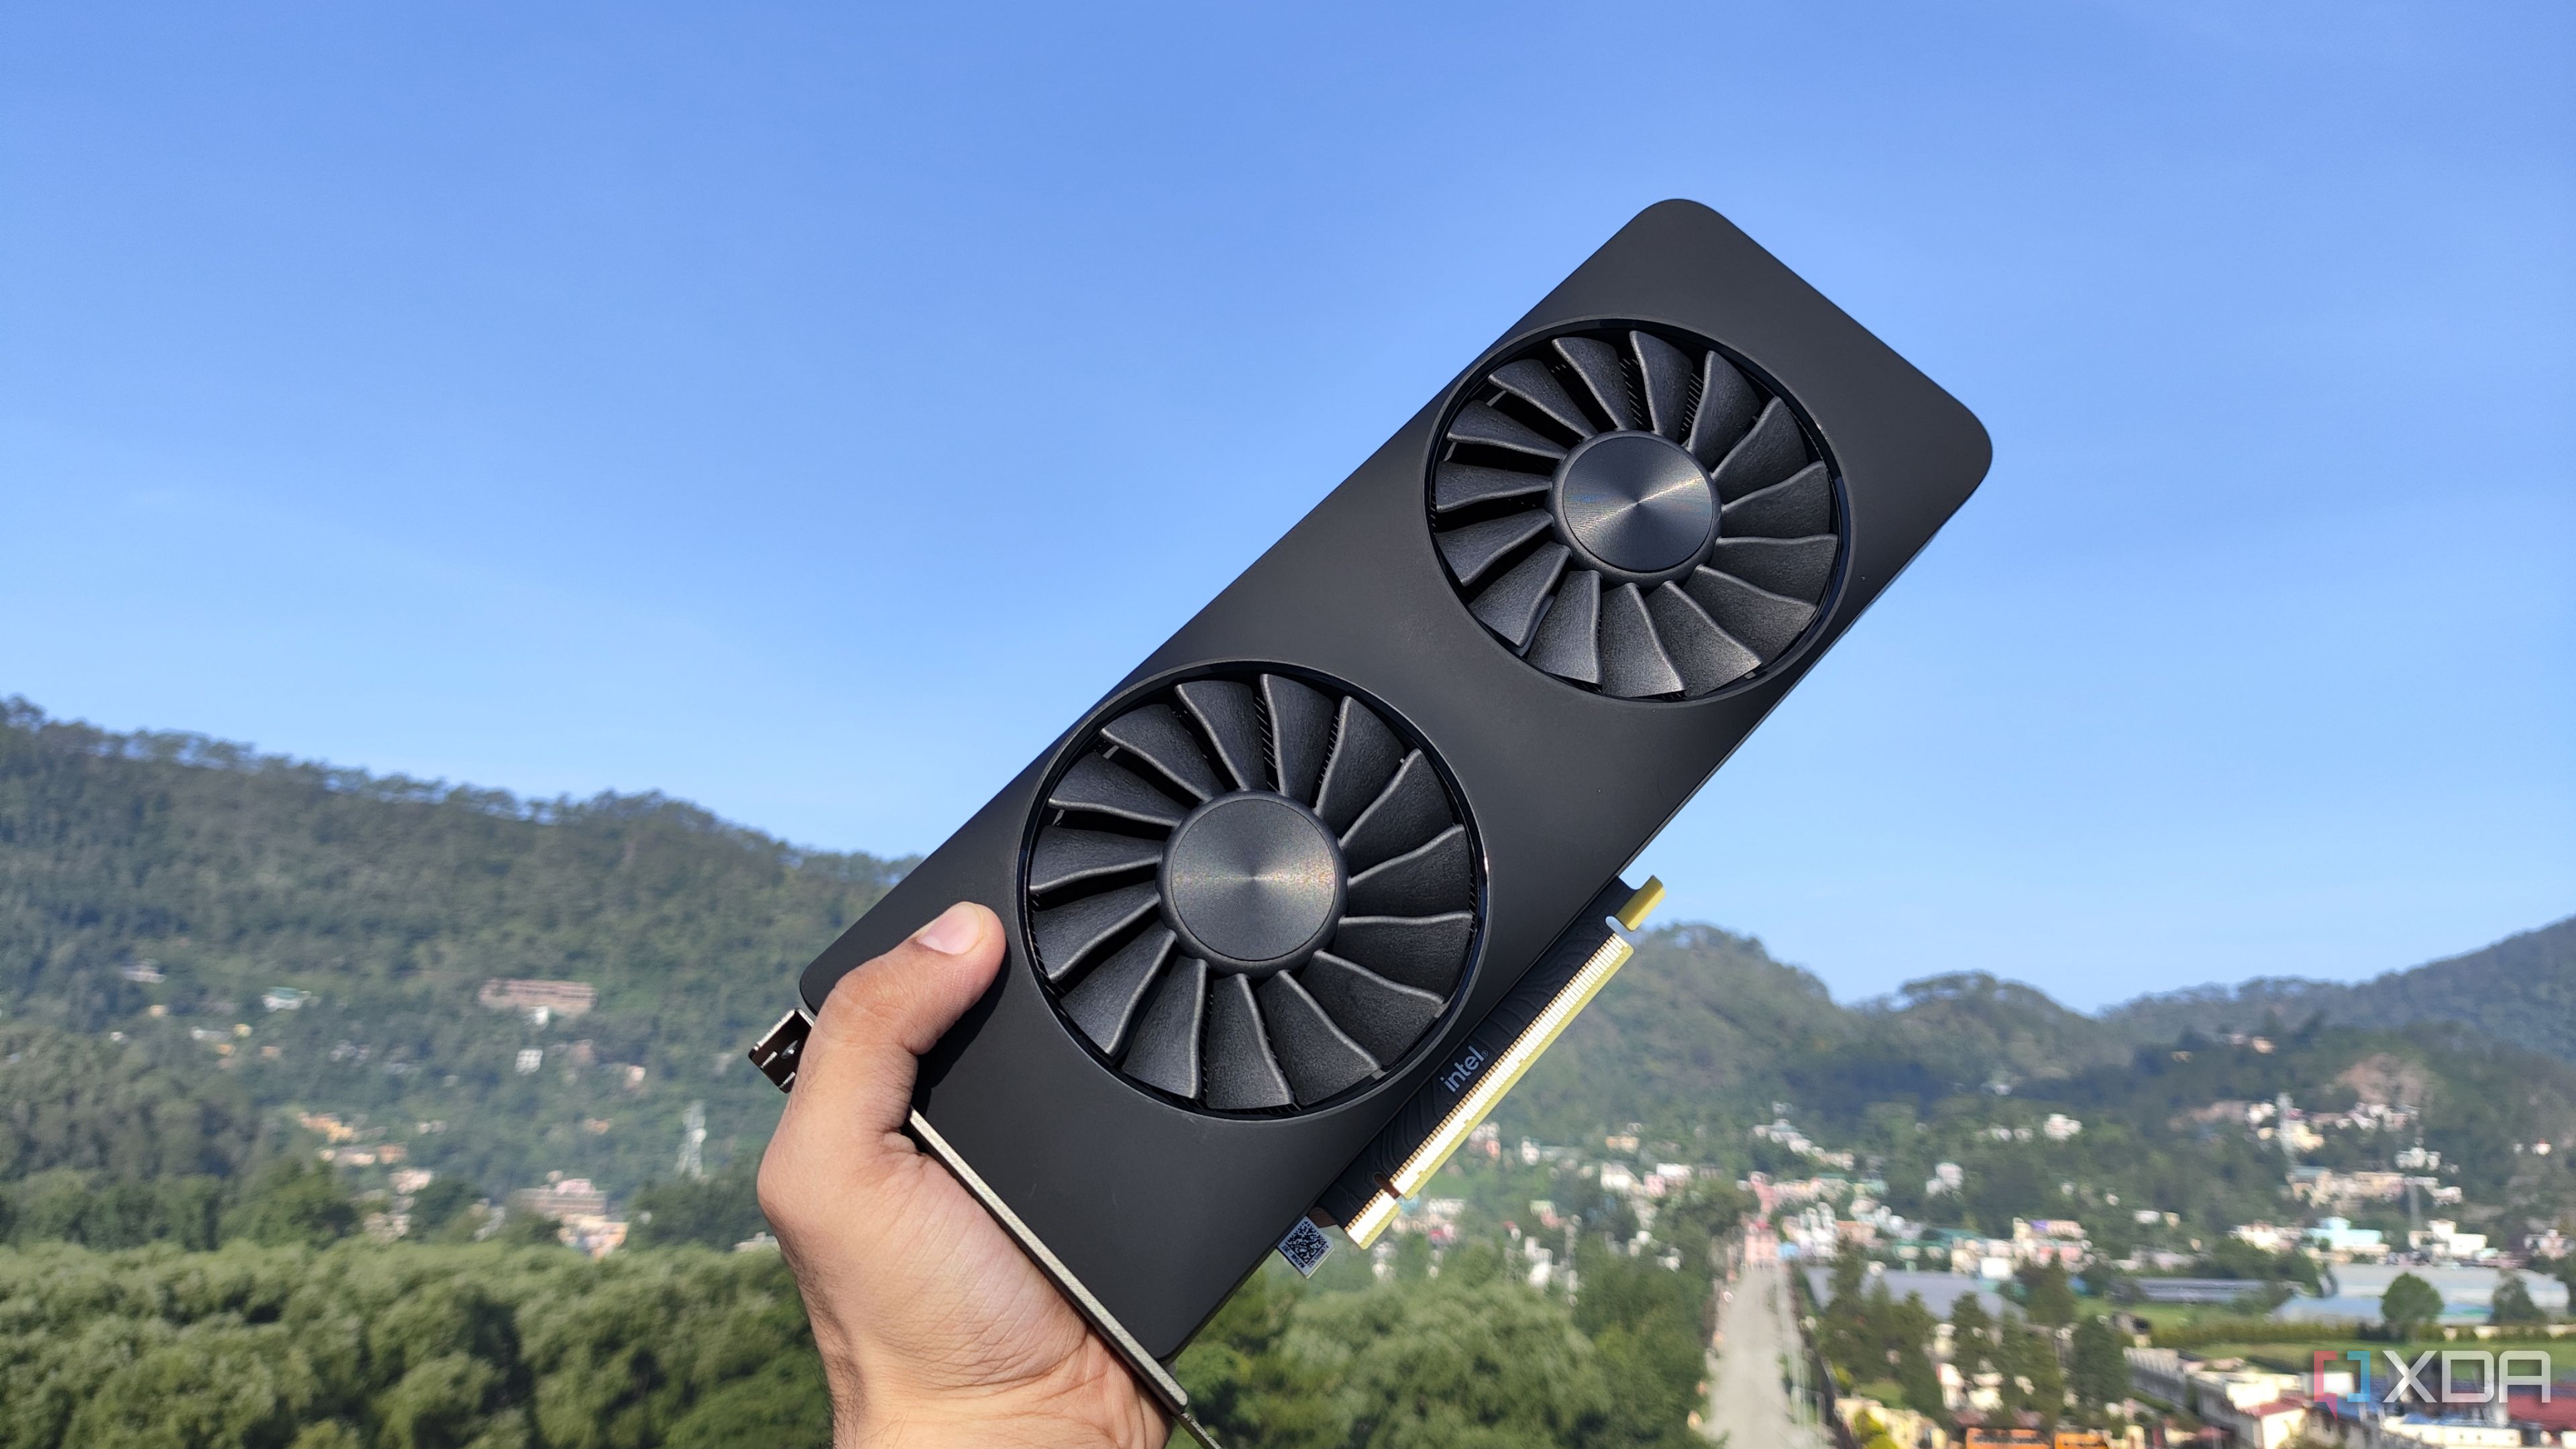
Nvidia cards are often recommended for local LLM tasks due to their powerful Tensor cores and CUDA ecosystem. However, Intel Arc A750 cards can also serve as a solid option for home labbers looking to set up a reliable LLM workstation. Ollama, once a top choice for deploying AI models, was found to waste processing power due to its Go-based management layer and limited token generation rates.
Switching to a llama.cpp instance with Vulkan backend proved to be the best upgrade for Intel-powered AI tasks. Although building llama.cpp with SYCL was challenging, the performance was still lackluster. By using a Vulkan framework with flash attention and increased batch size, the token generation rate reached 35 tokens per second, making it suitable for running models like Gemma 4 E4B on Home Assistant and other self-hosted services.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.