Inside GitHub’s new Git storage architecture
GitHub's new Git storage architecture is built so thousands of agents can push to a single repository at once. Here's how it works. The post Inside GitHub’s new Git storage architecture appeared first on The GitHub Blog .
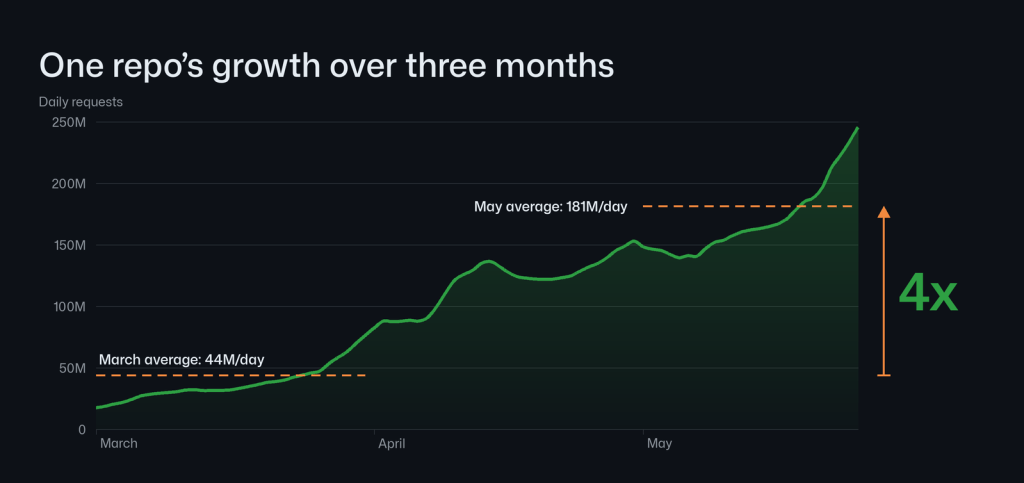
GitHub has unveiled its innovative new Git storage architecture during the recent GitHub Universe event. This architecture is designed to handle thousands of writes per second with read scaling on demand, supporting up to 5,000 concurrent agents working on a repository while serving read traffic with low latency. The new architecture builds upon the foundation laid by GitHub to support agentic development for hundreds of millions of developers.
The new architecture takes two core principles: minimize coordination and decouple storage from compute. Virtual replicas, which were introduced in the previous post, form the first step towards this new architecture. In this design, only reference updates require agreement, while the rest of the Git infrastructure scales independently.
Rubicon, the new architecture's name, represents a critical point of no return for the industry as it crosses into the era of agentic development. This architecture allows for thousands of writes per second and supports multiple writer nodes, which improves fault tolerance and speeds up recovery when a node fails. Furthermore, it minimizes commit latency by recording changes in order for each reference while enabling quick linearization across references.
The system's data plane is new and routes each request to one of a small group of virtual replicas assigned to that repository. These virtual replicas serve as disposable compute nodes that handle reads, ensuring that the system can scale independently and meet the demands of agentic development.
Written by urgent.news from GitHub Blog's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.