I measured my local LLM’s power bill and it costs less than a single $20 ChatGPT, Claude or Gemini subscription
The math isn't close, and it never really was
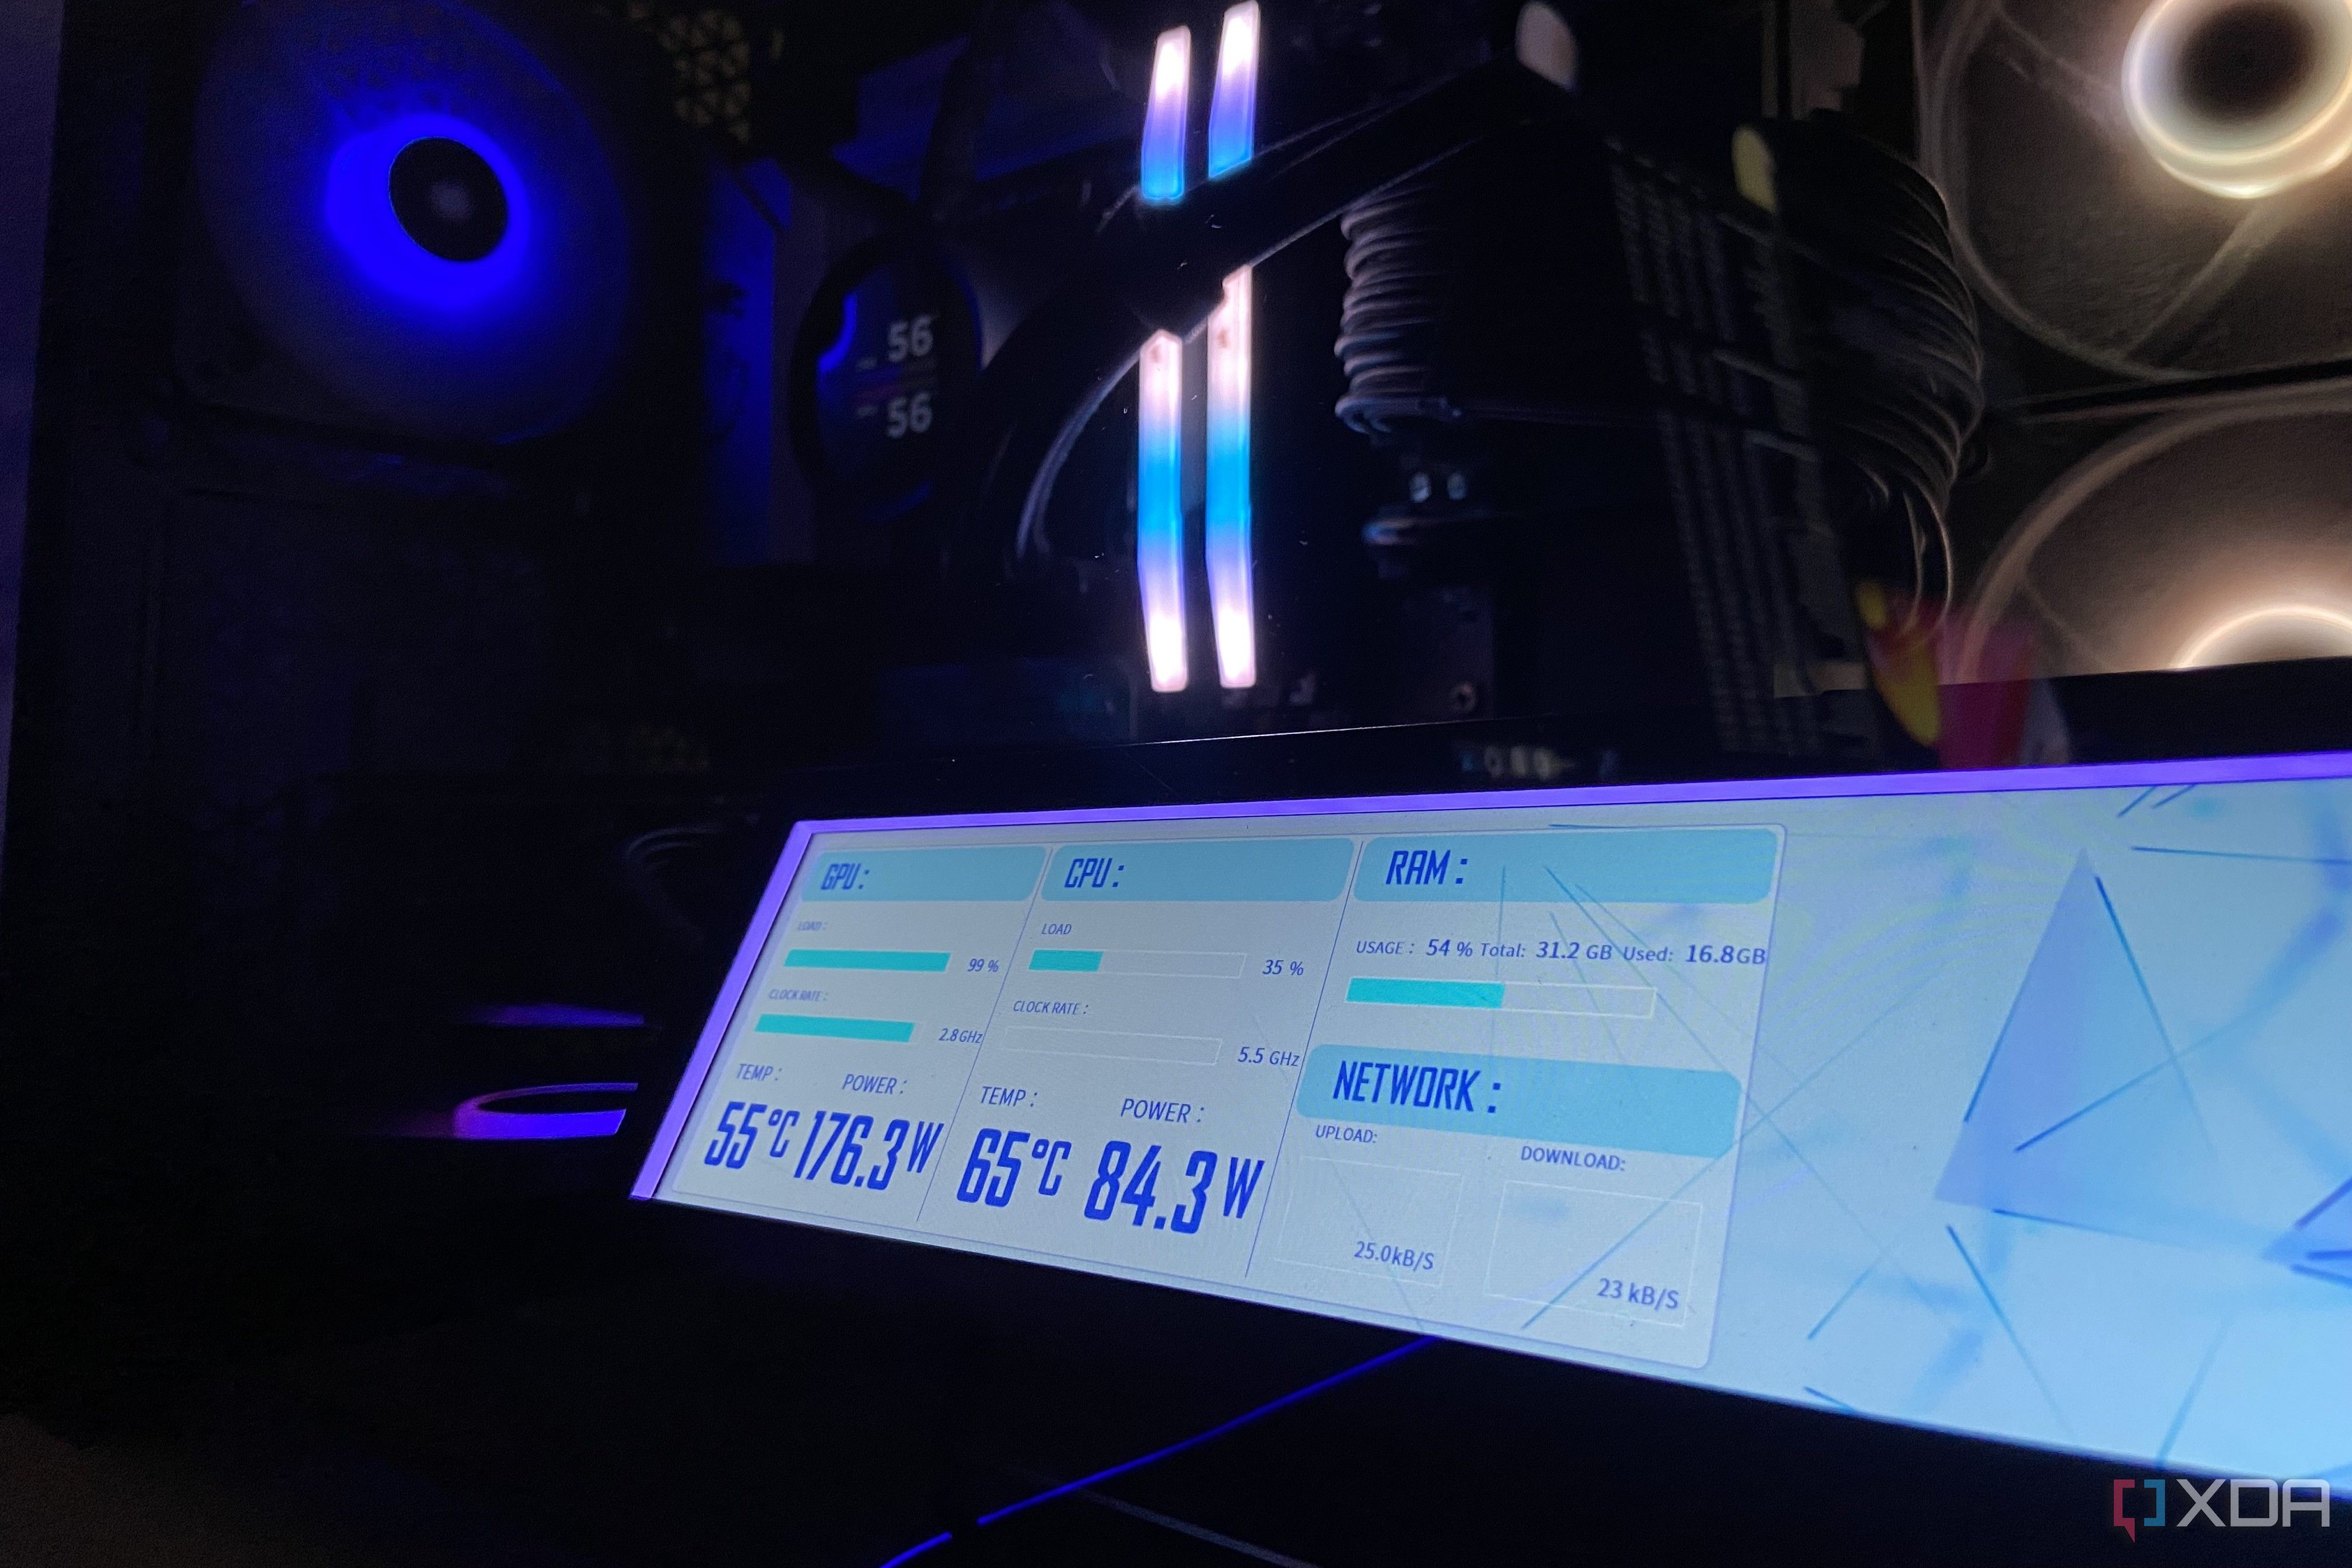
A self-hosting AI advocate recently put the power bill costs of running a large AI model on a personal PC to the test. By benchmarking Qwen3.6-35B-A3B on an RTX 4070 Ti Super, the author found that the cost was far less than the price of a single $20 ChatGPT, Claude or Gemini subscription. To do this, the author utilized llama-bench, HWiNFO, and Nvidia’s nvidia-smi to measure the power consumption of both the CPU and GPU while running the model.
Despite the high peak power usage of up to 251.9W, the author calculated that running the model non-stop for a month would still cost less than a single subscription, even when accounting for the extra power draw of the CPU and an additional 100W. The author emphasized that these costs can easily be misconstrued due to the high power draw of GPUs, but it is important to note that memory usage plays a larger role in token generation than raw compute power.
Comparing the costs of local model running versus cloud-based subscriptions, the author concluded that the power bill costs for running a local model are significantly lower, making self-hosting a more cost-effective option.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.
This story
This is one outlet's version. Read the fullest account.
- 'We were highly skeptical about the cost of AI': Revolut reveals it cut AI coding costs by cutting out Claude entirely techradar.com
- Claude's new AI report card tool gives companies a closer look at costs — and flags 'inefficiencies' businessinsider.com
- Revolut says it cut AI coding inference costs by ~90% in less than a year by making self-hosted GLM models its default over commercial tools like Claude Code (Tobias Mann/The Register) theregister.com