My self-hosted AI models research, code, and generate images, and all they cost is a GPU I already own
The only $20 I'm paying to is my savings account
For the past year, the author has been conducting numerous experiments with multiple local large language models (LLMs), but feels they have barely tapped into the potential of local AI technology. While advocating for a local-first approach for data privacy and cost-efficiency, the author acknowledges that no single model is proficient in deep research, coding, and image generation, making local models less competitive against cloud-based alternatives.
However, the author has discovered a solution by utilizing three distinct models for specific tasks on their PC equipped with a 16GB RTX 4070 Ti Super and Ryzen 5 7600X processor.
The first model, BigBang-v1, is a fine-tuned version of Qwen3.6-35B-A3B, released under the Apache 2.0 license. It excels in code writing, boasting a BrowseComp benchmark score of 76.5, which indicates its ability to find hard-to-find information on the web. To accommodate its 19.3GB weight size, the author uses the --n-cpu-moe flag, allocating about 7GB of system RAM to run the model. Despite its limited VRAM capacity, BigBang-v1 can write 68 to 78 tokens per second with a 128K context window.
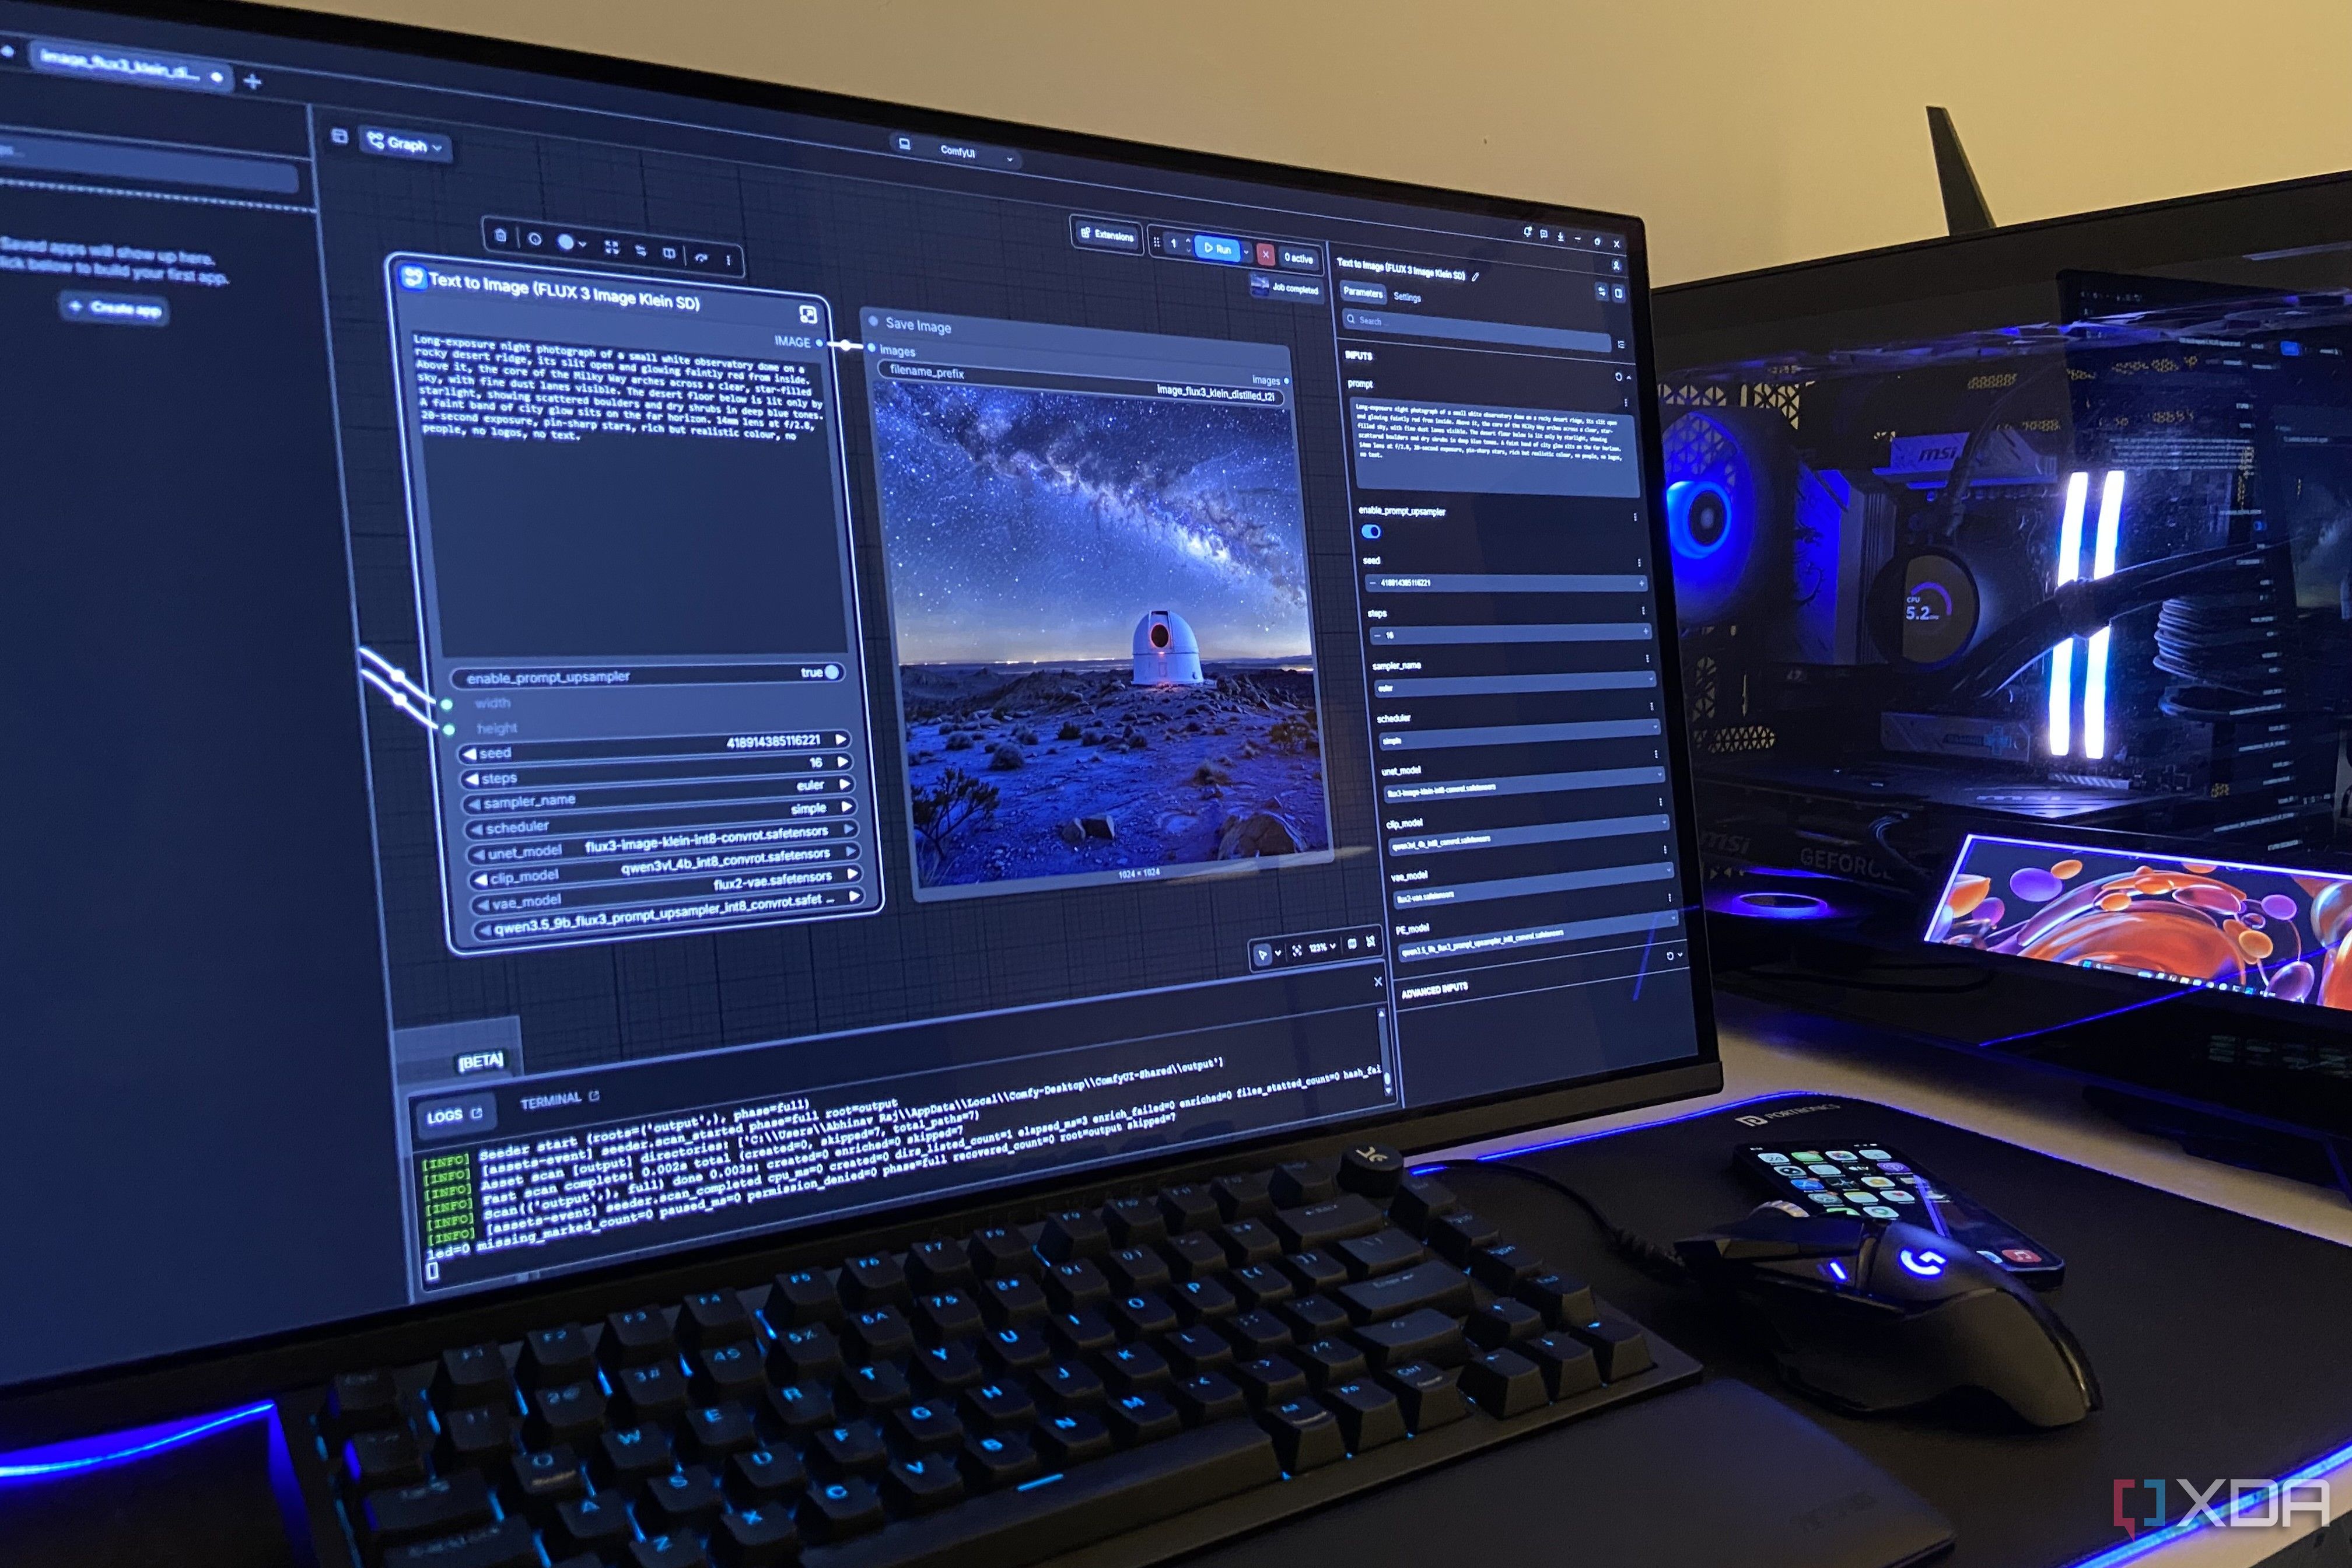
The second model, FLUX 3 Image Klein, focuses on image generation and editing. At just 5.6 billion parameters, it utilizes the same weights as the other models, ensuring efficiency. It requires two additional models: a 9B Qwen3.5 for prompt upsampling and a 4B Qwen3-VL as a text encoder. By running INT8 builds of these three models in ComfyUI, the author achieves 1024x1024 image generation in around 16 seconds, with minimal wait time.
The setup eliminates subscription fees, watermarks, and usage limits, granting the author full ownership over the image generation process.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.