My RTX Spark laptop rendered a Blender scene too big for an RTX 5090, and a local LLM on the same machine built it
It's not faster than an RTX 5090, but the additional VRAM makes for some cool tricks.
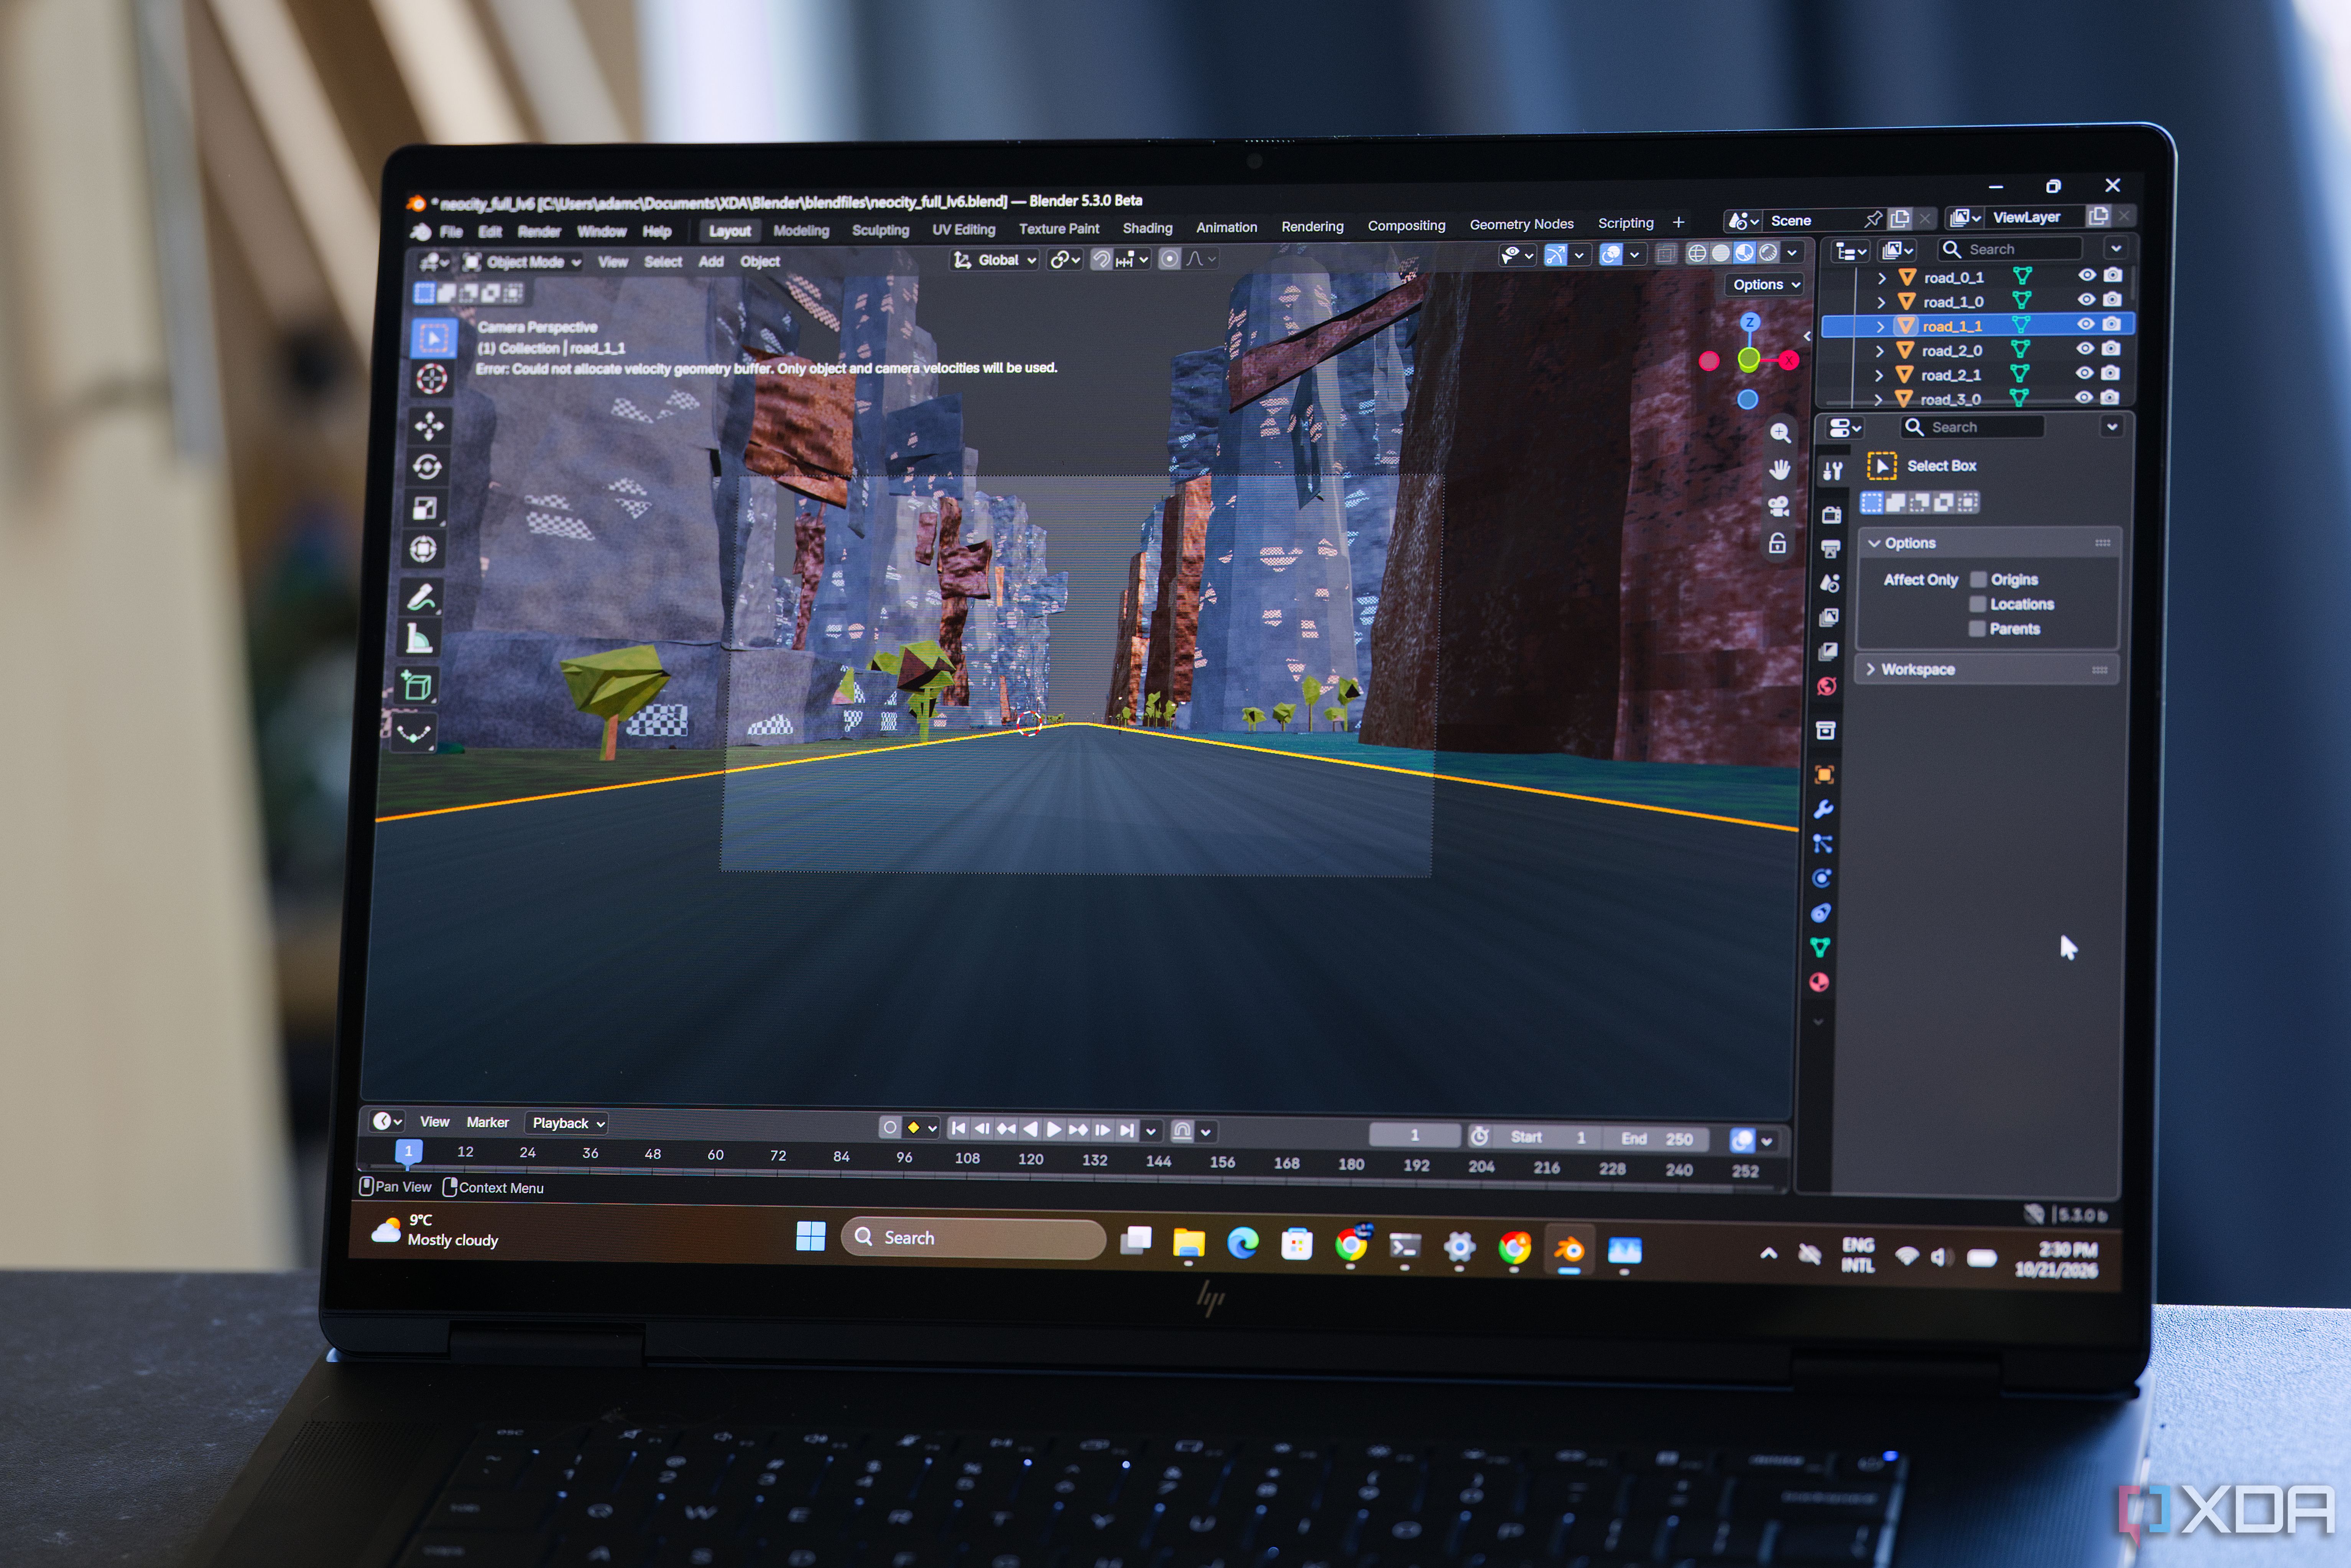
Local LLMs are often discussed in the context of laptops with 128GB of unified memory, especially when considering Nvidia's RTX Spark. The ability to run Qwen3.8 Flash Next on a portable device is indeed impressive. To test this capability, I used the HP OmniBook Ultra 16, which boasts a 20-core Grace CPU, a 6,144-core Blackwell GPU, and 128GB of LPDDR5X-9400 memory.
This laptop costs $6,229.99, though it's significantly less than some workstation GPUs. The RTX Spark system reserves a portion of its memory for the GPU, which Windows reports as dedicated GPU memory. Despite the model's 125 billion parameters, only six billion are activated per token, allowing for up to 45 tokens per second. I used this model, running locally, to generate a procedural city in Blender using Qwen3.8 Flash Next powered by llama.cpp.
The model interacted with Blender, optimizing the scene's complexity based on memory constraints. The final render took 81 minutes, producing a detailed 1080p image composed of procedural materials and lighting. All elements, including the 13,600 objects and 18 camera positions, were generated by the model's code.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.