How Fortune 500 Companies Build Data Platforms
Explore how large enterprises build scalable data platforms using lakehouses, batch and streaming pipelines, data mesh, governance, and layered architectures.
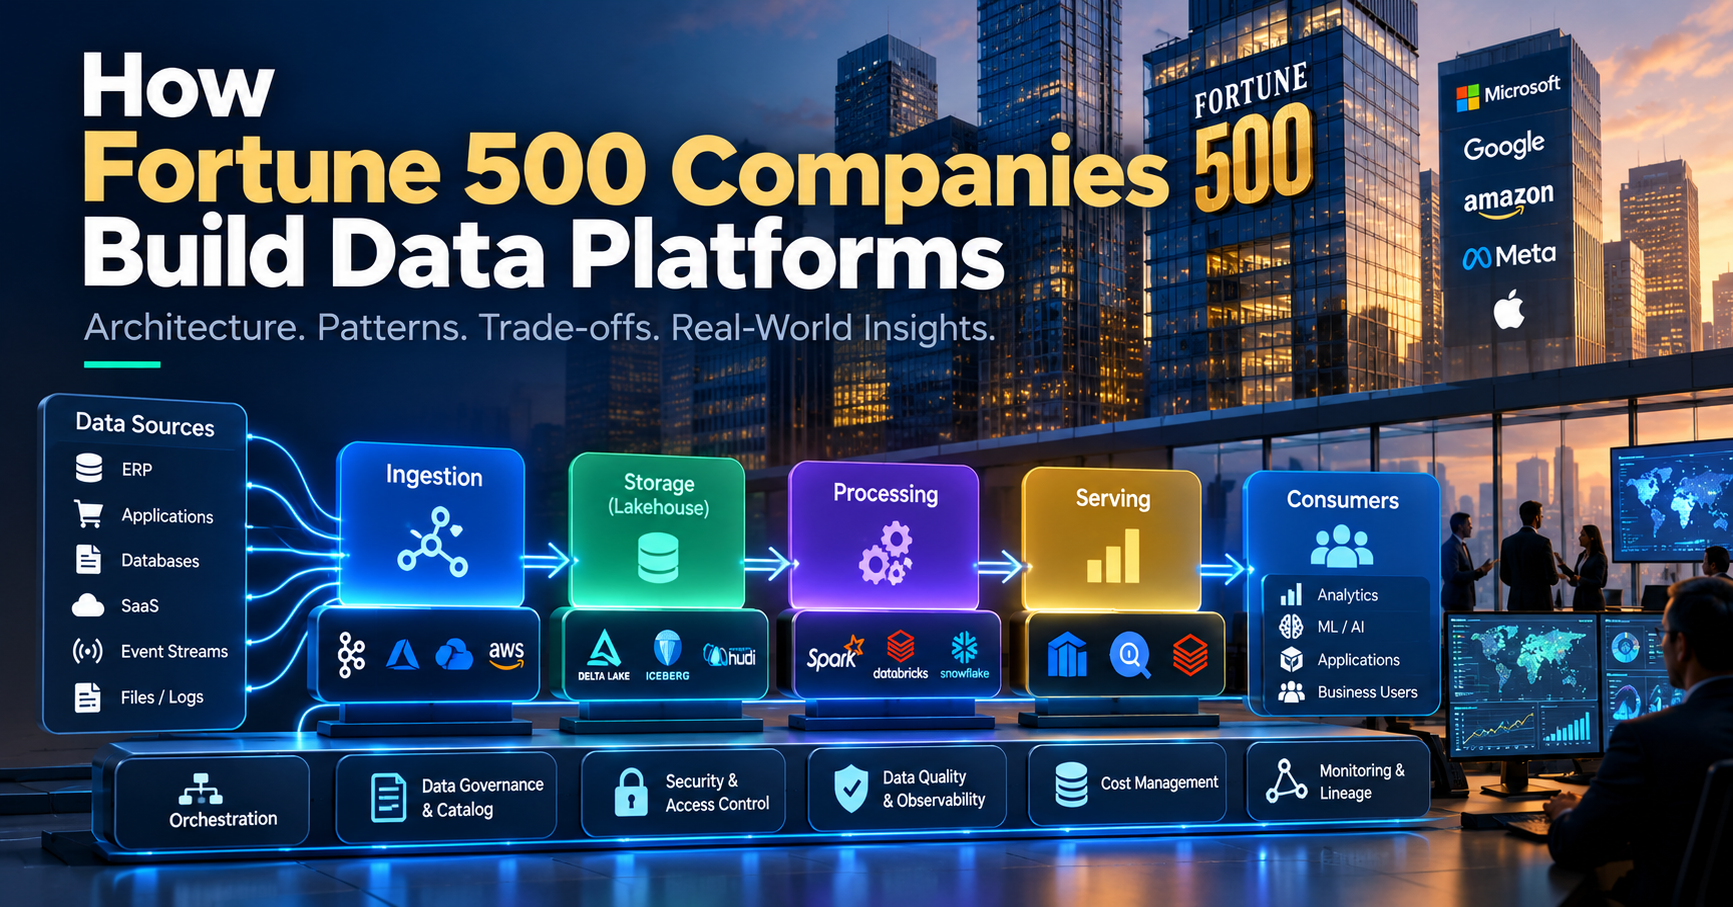
In the world of Fortune 500 companies, building a data platform is crucial for managing the complexity that comes with growth. A simple query, asking how much was sold and how much was profitable last Tuesday, can involve six systems, four teams, and two definitions of profitability in a large enterprise. This is where a data platform comes in, providing a set of layers to carry data from its point of creation to where it can be trusted and used.
These platforms can be broken down into five layers, with shared services underneath. The bottom layers - ingestion, storage, processing, and consumption - are the core of the platform. However, the grey bars at the bottom, representing orchestration, governance, security, and cost control, are just as important. They can consume a significant portion of the budget and are often overlooked in the initial setup of a platform.
One of the biggest challenges in building a data platform is ensuring data quality and access control. Without a catalog and access policies, it can be difficult to determine who has access to certain data, such as customer addresses. Additionally, keeping an untouched copy of the raw data is essential, even if it is messy. This helps prevent issues when transformations go wrong, allowing teams to replay history instead of apologizing to finance.
The lakehouse approach has become popular in recent years, combining the strengths of both warehouses and lakes. Data is stored in cheap object storage, and an open table format adds the benefits of strict structure and time travel. Apache Iceberg, Apache Hudi, and Delta Lake are examples of projects that have emerged from the need to handle large volumes of data in object storage.
However, the decision to use a lakehouse is not always clear-cut. While open table formats offer flexibility and reduce lock-in, they also add operational work and may not be necessary for smaller teams. Enterprises may choose to use a cloud warehouse like Snowflake or BigQuery as their primary engine, finding it satisfactory for their needs.
In terms of data processing, most enterprises need both batch and streaming capabilities. Fast processing, such as rolling windows and joins, is typically done through an event log like Apache Kafka. Slow processing, which involves backfills and heavy joins, is handled by a separate path. The newer approach is to let both paths write into the same table format, ensuring that consumers see a single, unified dataset. While this is not perfect, it is certainly better than manually reconciling two different answers.
To ensure data quality, many stages of refinement are used within the lakehouse. Each stage has a different audience and level of refinement. Bronze is the raw copy, kept as received. Silver is cleaned and prepared for analysis, while gold is business-ready and has passed quality checks. Having these stages helps to ensure that the data is trustworthy and meets the needs of different users, from engineers and auditors to executives and regulators.
The organization of a data platform is also an important consideration. Traditionally, a central data team would build and manage everything, but this can lead to bottlenecks and delays. An alternative approach, known as data mesh, involves the domain teams owning their data and publishing it as products with owners, schemas, and service levels.
A central platform team provides the shared tools and infrastructure, allowing domain teams to focus on their specific data needs. While this approach has its challenges, it can be a more efficient and effective way to build and maintain a data platform in large organizations.
Written by urgent.news from HackerNoon's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.