I replaced Google search with a local LLM for a week, and it changed how I find answers
The web, minus the scrolling and ads
Searching with Google used to be the go-to solution for information. However, nowadays, the search results are buried under a few sponsored listings and an AI summary that may not be accurate. The process to find the answer often involves more scrolling than the original question requires, leading people to settle for the first result, which may not be the most reliable.
Local Large Language Models (LLMs) have become adept at answering questions without transmitting any data to large technology companies. I recently integrated one of these models with filesystem access, which eventually replaced Windows Search for the majority of tasks. However, models that fit on an 8GB GPU are typically small and only know what they were trained on, which means they lack information about recent events.
Therefore, I granted mine web access. Google search has been deteriorating for years, as research from Germany revealed. The top results across Google, Bing, and DuckDuckGo were predominantly pages built around affiliate links, and a significant amount was SEO spam. While Google improved slightly over the year they monitored it, the average user likely wouldn't notice, and the spam issue persisted.
Additionally, AI overviews are a double-edged sword. They are incredibly convenient, but there's a risk of presenting personal opinions from forums as facts, necessitating further verification. This situation might be improved by returning to the previous method of scrolling through results. Google now determines what I see before I even begin reading.
The top of the results page is filled with content that Google wants to display, often not matching the user's query. A local model has access to information only if it was included in its training data, which is satisfactory for explaining concepts or providing information outdated by a few years. However, recent information will be an approximation, such as when I asked Gemma E4B about the date, and it confidently replied 2016.
The solution is to give the model the ability to perform web searches, which I accomplished around January. The process is relatively simple; one must switch on a toggle in the settings and install the Jan browser extension. By default, it queries Exa on a free endpoint without requiring an API key, ensuring that my inquiries bypass Google.
Search and fetch serve different purposes. Search generates a list of results with titles and brief snippets, whereas fetch opens one of those pages and reads the actual text. Jan's built-in web search provides both functionalities, allowing the model to conduct a search and subsequently select a result to examine independently.
The fetched pages are truncated to a specific length before reaching the model to prevent the context from becoming too large. LM Studio can perform these tasks as well, and I already had Brave Search set up in LM Studio, which is advantageous if you prefer an engine that operates its own index rather than relying on Google or Bing.
This involves creating an account for the Brave Search API and modifying the mcp.json file. On an 8GB GPU, the choice of models depends on the extent to which the model engages in tool calling. For lighter conversations, I recommend the Qwen 3.5 4B Q4_K_M model, while the Qwen 9B also at Q4_K_M is more suitable for more intensive tasks.
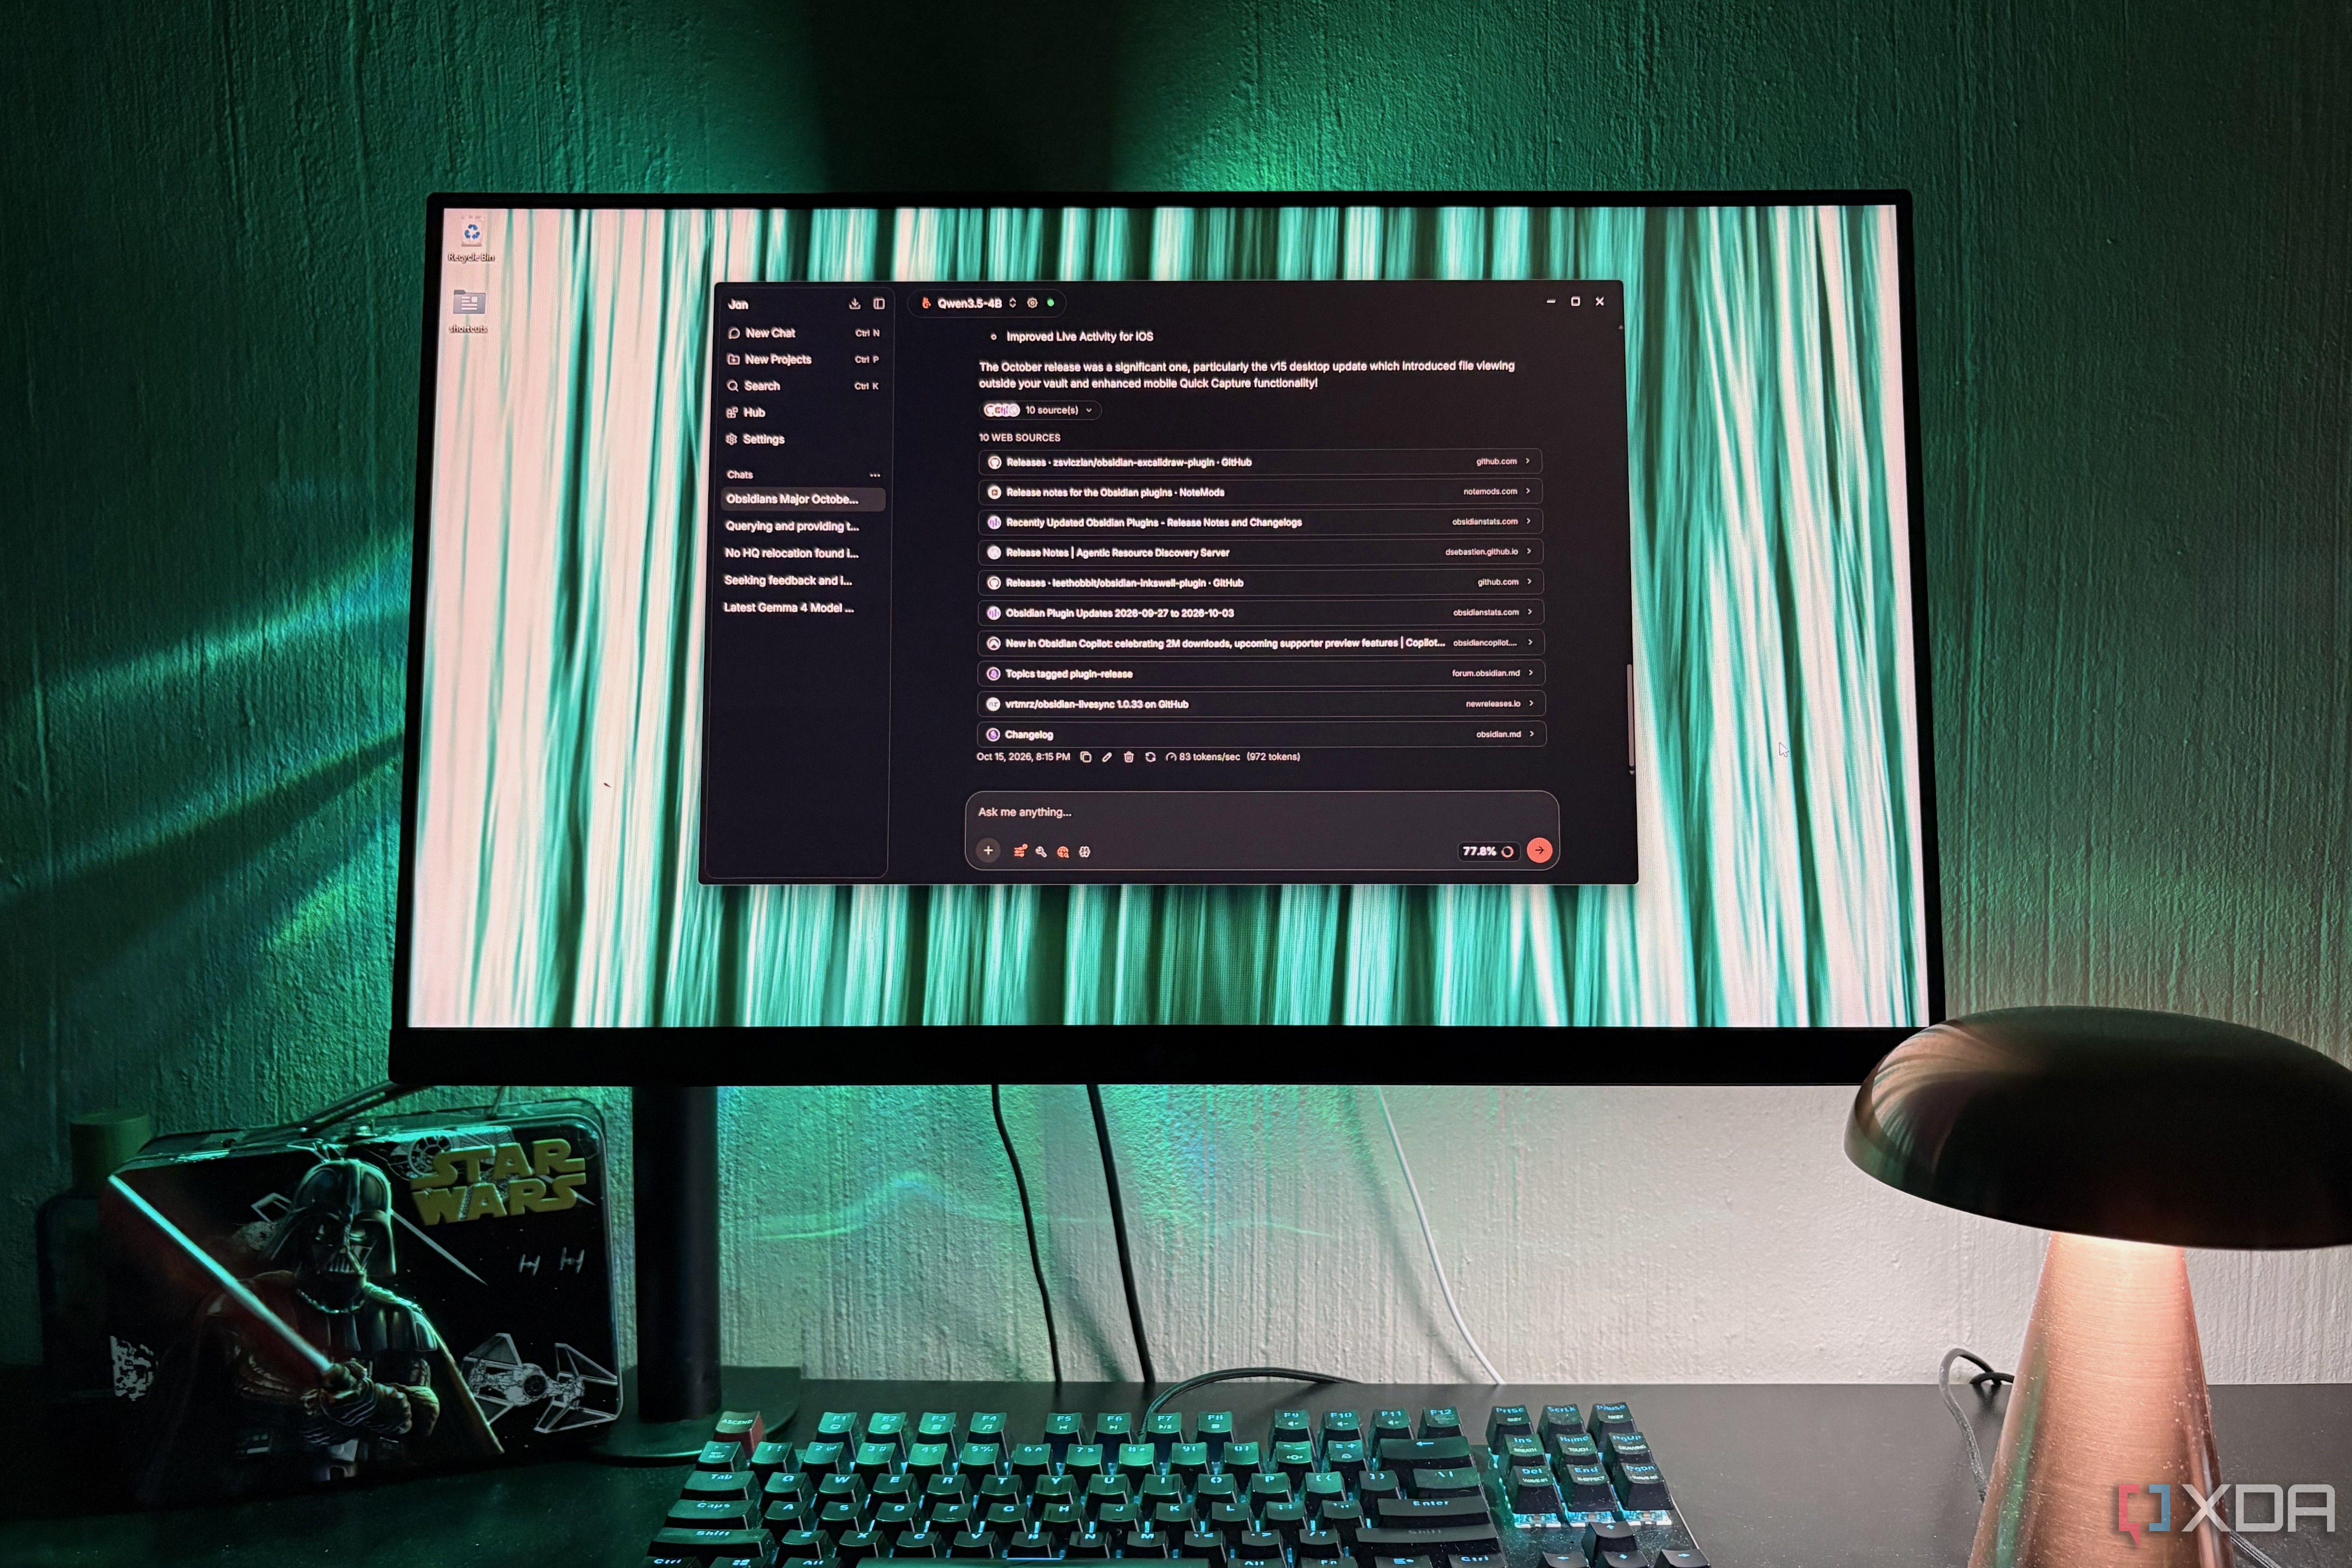
Unlike Gemma, Qwen initiates searches without being prompted. However, Qwen is not entirely reliable. For instance, when I asked about Obsidian's release this month, it listed ten sources and dated the update to October 2035, with a version number that doesn't exist anywhere, with only one source being from Obsidian itself. Despite this, Jan provides the sources under every answer, enabling users to easily verify the information.
The user-friendly implementation allows for direct access to the official page. One should be cautious of context, as using a large portion of the context window can be an issue. On a smaller GPU, finding a balance between the model, quantization, context length, and prompt formulation is crucial. While this may seem like a hindrance, it promotes more mindful inquiry, an aspect that has diminished since AI entered the search engine arena.
Although I still access Google for specific queries, such as logging into an account or finding real-time information about restaurant hours, I now initiate searches using my local LLM.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.