Urgent.News

What's breaking now, across thousands of outlets.

AI

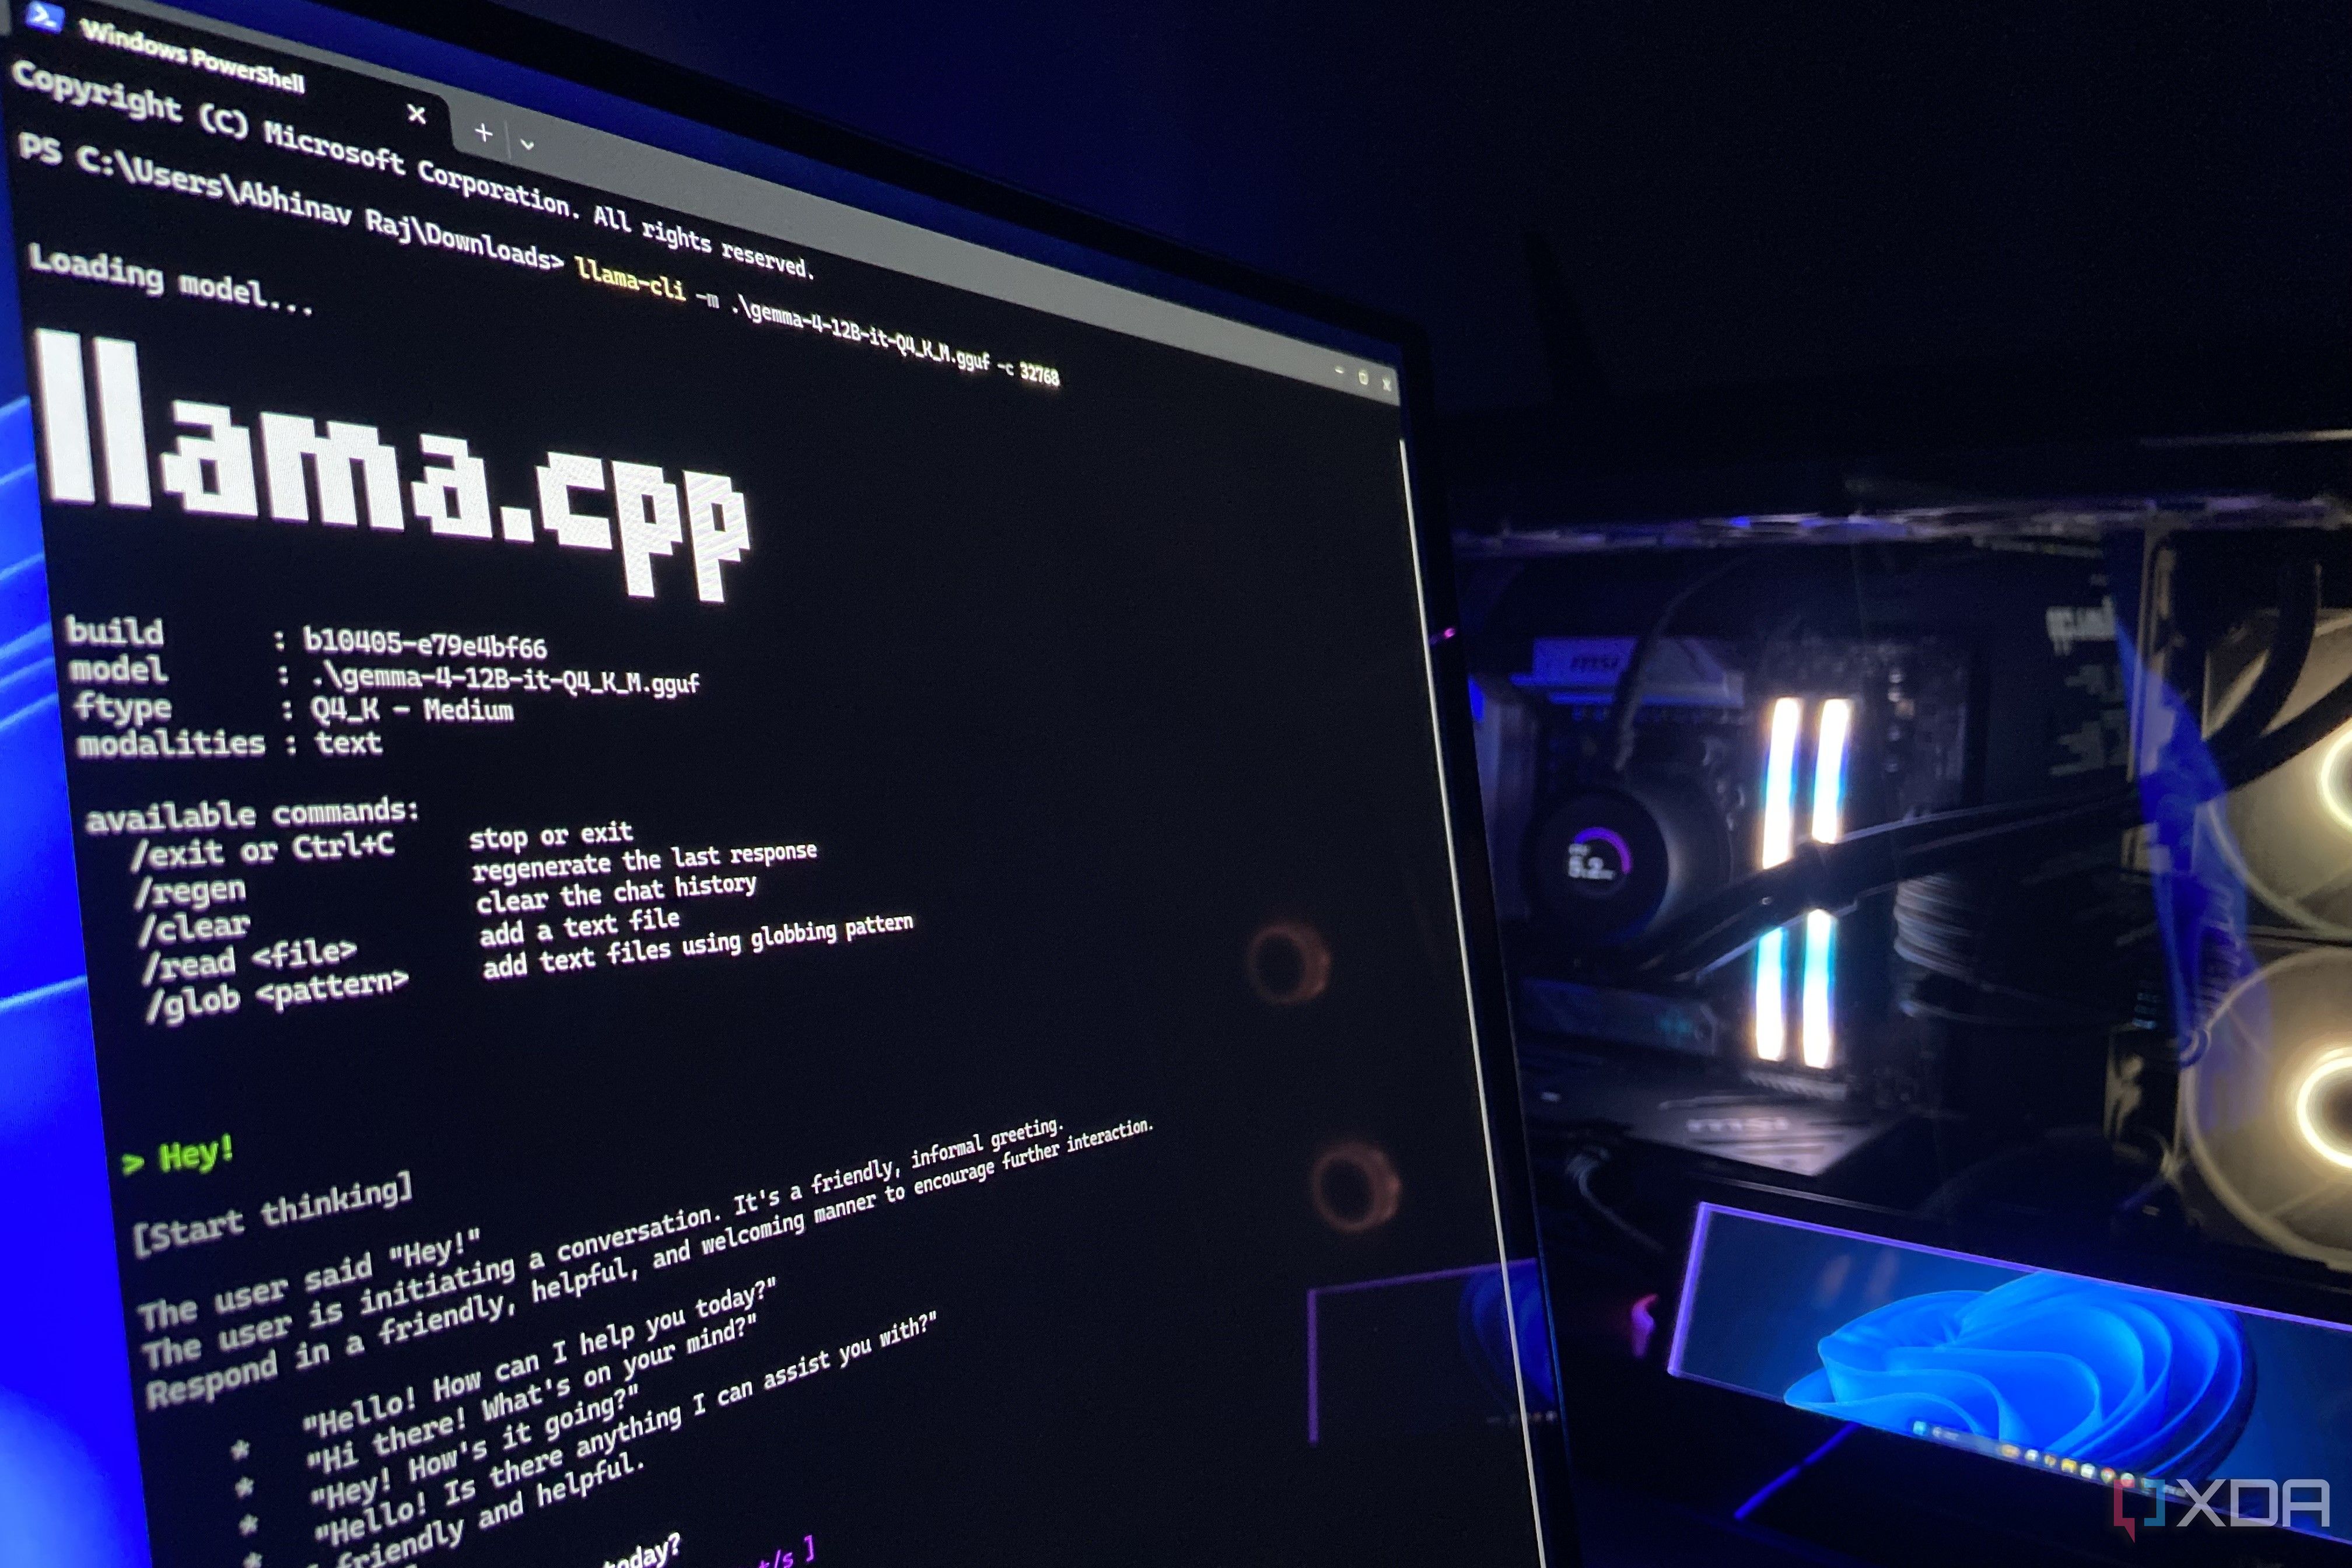
I moved my local models from Ollama to llama.cpp, and the reason I stayed has nothing to do with speed

Convenience beats tokens generated per second, always
I moved my local models from Ollama to llama.cpp, and the reason I stayed has nothing to do with speed

Having initially relied on Ollama for hosting local AI models, I recently transitioned to llama.cpp and discovered the primary reason for my continued use has nothing to do with speed. Although both interfaces now provide comparable speeds for the models I utilize, llama.cpp's additional features and ease of use have made it my preferred choice.

Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.
Read the original at xda-developers.com →

More in AI

AI-Generated Tests Can Agree With the Bug

An AI coding agent implements a feature, generates tests, runs them, and opens a pull request with a green build. That looks like independent verification. It often is not.

  • AI-generated tests can agree with bugs due to correlated output
  • Example shows AI misinterpreting discount calculation requirement
  • Independent validation needed to avoid false confidence in code

More from Thursday 15 October →