An E-Commerce Platform Is a Reliability Problem Disguised as a Website Project
Learn how to design a production-grade e-commerce web platform with clear domain boundaries, caching, search, inventory consistency, checkout reliability, obser
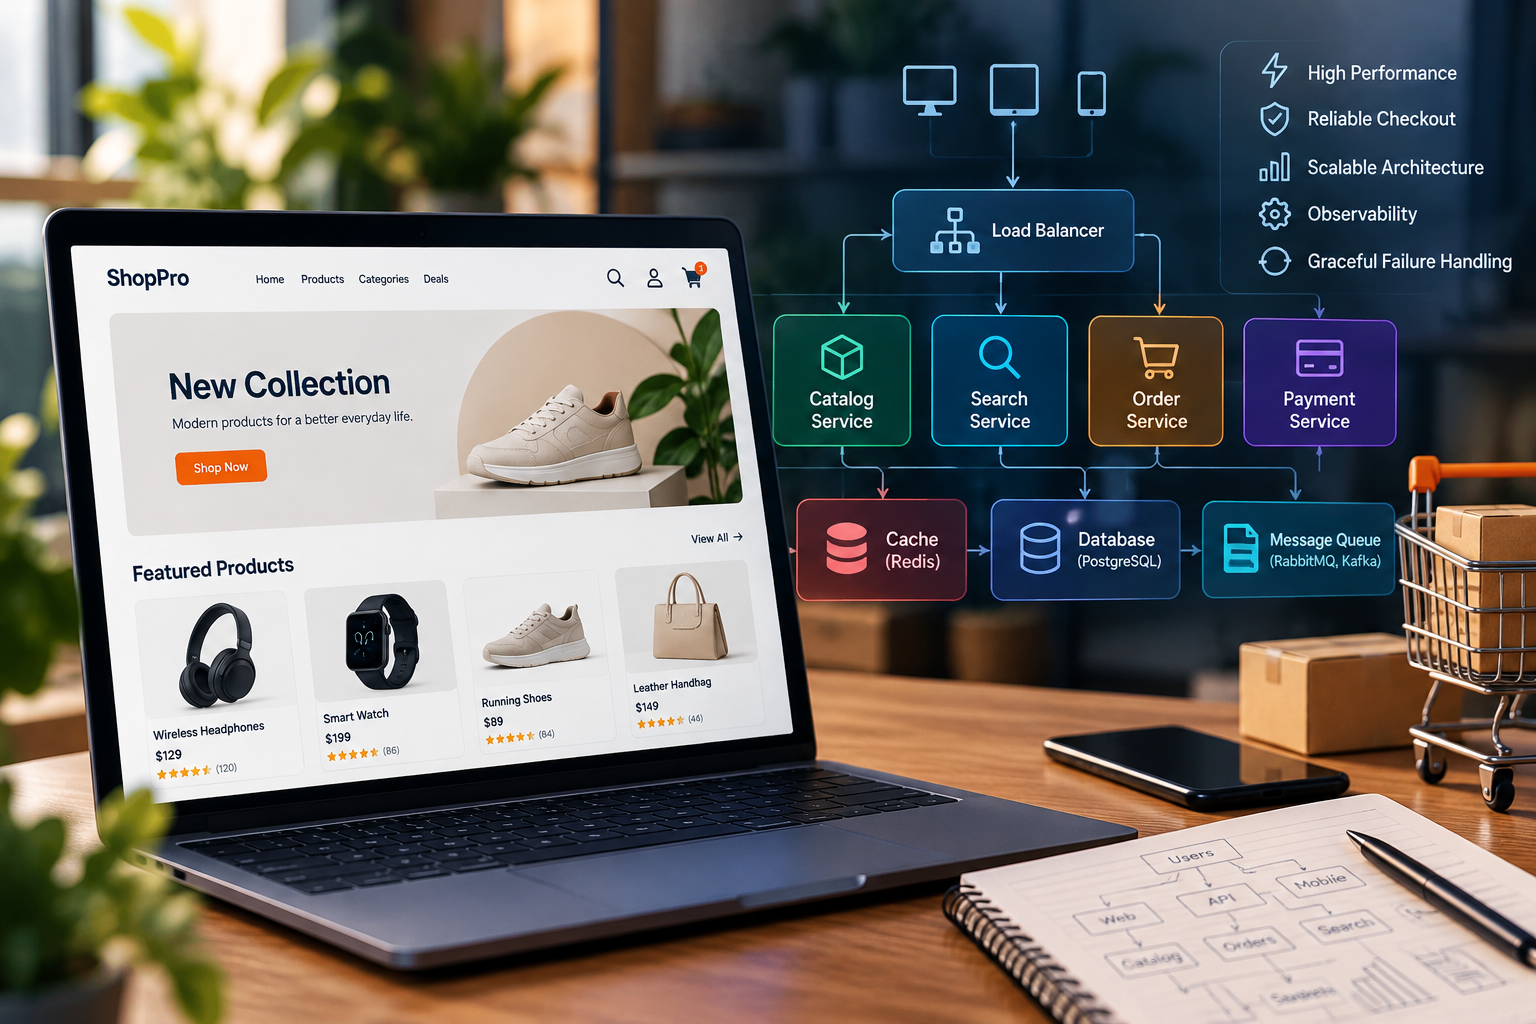
Designing an e-commerce platform requires careful consideration of reliability issues beyond just building a simple website. A common mistake is picking a framework before establishing proper domain boundaries. These boundaries are the key architectural decisions that shape a scalable e-commerce system.
An e-commerce platform typically consists of several logical areas: catalog management, customer accounts, sessions, the shopping cart, orders, payments, discounts, and inventory. While these can initially appear as a straightforward CRUD application, the system quickly evolves into a distributed application with multiple consistency boundaries once real-world factors like inventory, promotions, payments, user accounts, and third-party integrations come into play.
The first step is to define these domain boundaries before selecting any technology stack. Many teams make the mistake of choosing a framework first and then trying to fit their business model into it. This often leads to poorly defined services and increased complexity through network failure modes. A better approach is to start with modular monolith architecture, which preserves domain boundaries while still allowing deployment as a single application.
Another critical aspect is separating read-heavy and write-critical workloads. Product listing pages and search results receive thousands of reads, while inventory updates, order creation, and payment confirmations happen infrequently but require strong correctness guarantees. Implementing a caching strategy that takes advantage of this imbalance can significantly improve performance without sacrificing data integrity.
Read-heavy operations like category pages, product details, and search results can leverage browser caches, CDN/edge caches, and application caches. In contrast, write-critical operations such as reserving inventory, creating orders, recording payments, applying coupons, and issuing refunds need transactional thinking to avoid creating inconsistencies.
Caching should be implemented in a hierarchy where the cache closest to the user is the cheapest to read from, and the system's source of truth is the cache closest to it. For instance, product descriptions can have longer cache lifetimes compared to inventory data, which might need very short TTLs or event-driven invalidation. Properly versioned cache keys become essential when schema or serialization changes occur to prevent stale entries from being deserialized.
Search functionality is another subsystem that requires careful design. A simple SQL query may suffice initially, but as requirements grow, search needs to handle typo tolerance, stemming, synonyms, faceting, filters, sorting, ranking, autocomplete, personalization, and availability constraints. At this point, relying solely on relational SQL becomes increasingly difficult to maintain.
Instead, a more scalable architecture involves using a primary database for domain events, an indexing worker that builds a search index, and a search API that serves as the read model.
Finally, inventory management demands stronger guarantees than catalog data due to its critical role in ensuring proper stock levels and avoiding overselling. A naïve read-then-write approach is prone to errors when multiple customers attempt to purchase the last unit in stock simultaneously. To mitigate this risk, a more robust inventory management system should be implemented, taking into account the high stakes involved in maintaining accurate stock levels.
Written by urgent.news from HackerNoon's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.