Your Agent Retries Because It Can't Tell a Timeout From a Failure
A timeout is not a failure. How to stop an AI agent re-running finished work: an unknown state, a gate in the executor, and an open-source demo.
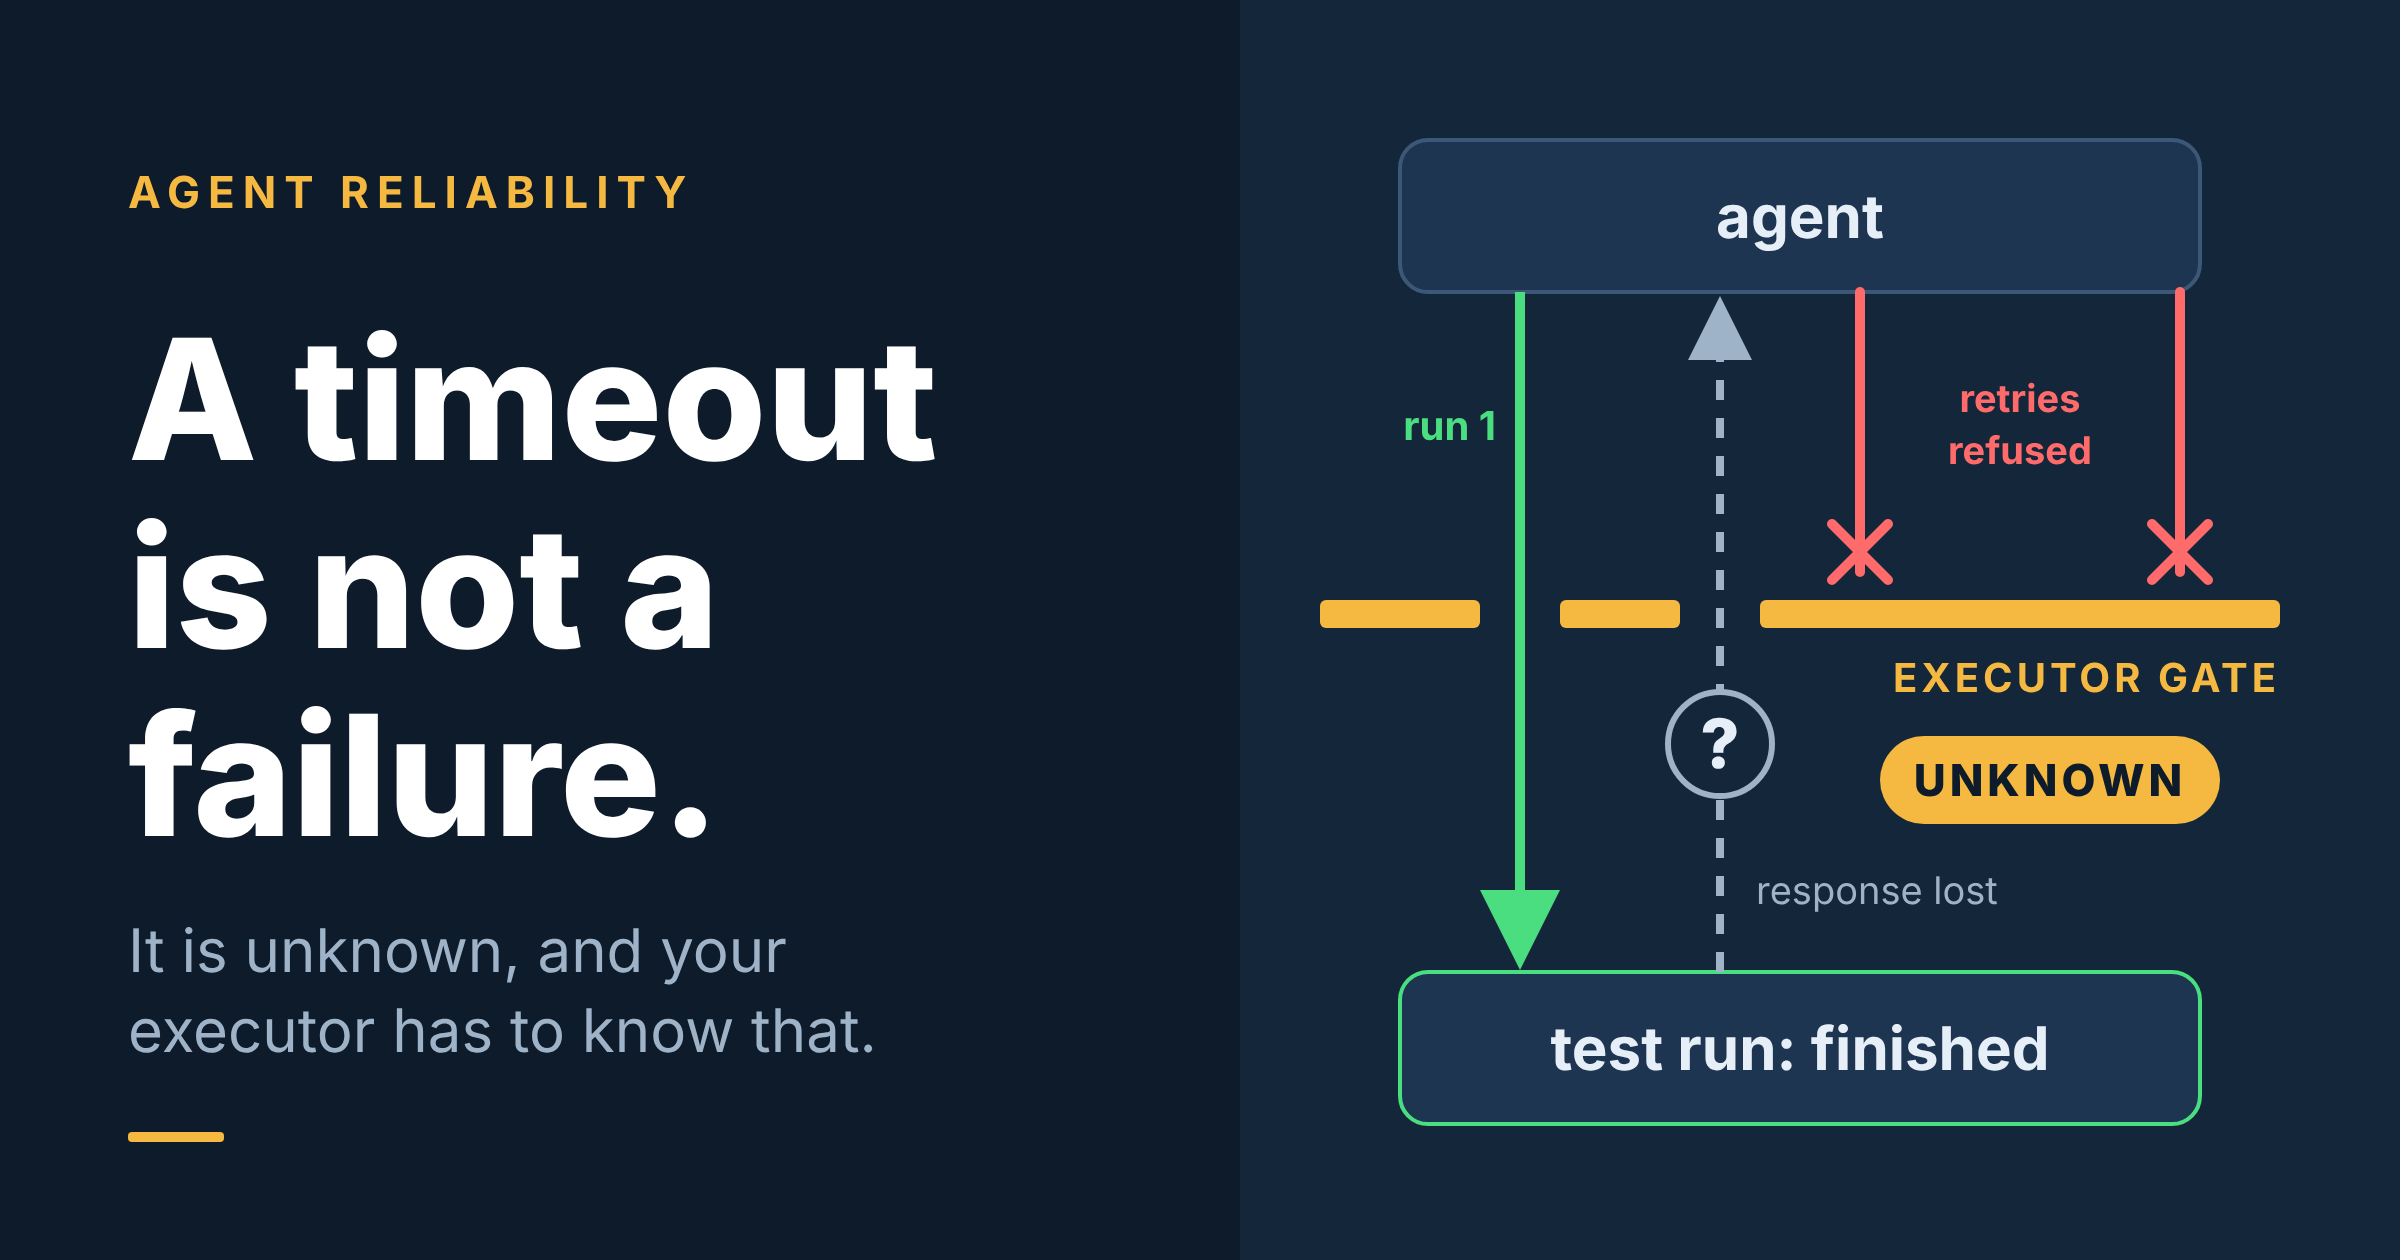
An AI agent tasked with reviewing automated test coverage encountered a timeout and mistakenly treated it as a failure, causing it to retry the already-finished task. The agent successfully identified various errors it encountered during these retries, including timeouts, locked records, and missing VPN connections. However, its behavior remained consistent regardless of these errors.
The real issue lies in the model's inability to differentiate between a failure and an unknown outcome, which needs to be handled by the execution layer, not the model. The solution is to introduce a third state, "unknown," which allows the system to distinguish between a failed action (requiring a retry) and an action whose result is unknown (requiring further investigation).
This approach prevents the agent from accidentally repeating work that has already been completed and ensures more accurate execution of tasks.
Written by urgent.news from HackerNoon's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.