Why DNS Needs to Be Treated as Critical Infrastructure
DNS is one of those infrastructure components that only gets attention when something breaks, and by then, the damage is already done. An application may appear healthy, servers may be reachable, and network connectivity may show green across the board. However, users cannot get in, and the on-call engineer is staring at logs trying to […]
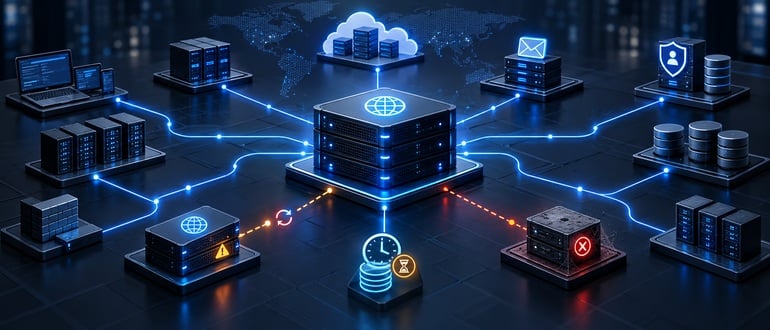
DNS is an integral part of modern infrastructure, often unnoticed until it malfunctions. Despite servers being reachable and network connectivity appearing green, users may be unable to access applications due to DNS misconfigurations. These issues can arise from a single record edit, affecting application accessibility, mail delivery, or resolution for every hostname in a zone.
Moreover, the effects of a faulty change can linger even after the mistake is rectified because DNS responses are cached. Therefore, before making any critical DNS changes, teams should have a comprehensive understanding of the current record, the systems it affects, and an effective rollback plan.
TTL (Time To Live) settings are particularly crucial, as dropping a record's TTL immediately prior to a change does not assist. Resolvers have already cached the old value, and TTL needs to be lowered in advance, allowing cached responses to expire. Validation should extend beyond confirming the update on the primary server, including checking secondary servers and testing resolution from relevant networks.
A simple "change" button does not constitute a process. DNS requires a well-defined change life cycle. Most organizations have a secondary DNS server, but merely having one does not ensure redundancy. Secondary servers must be properly synchronized and capable of answering queries independently. Zone transfers can silently fail, causing delays in syncing.
Secondary servers may fall behind without anyone noticing, and placing the primary and secondary on the same underlying infrastructure offers no real protection if that infrastructure fails. Similarly, recursive resolvers configured for a single resolver can turn a minor DNS issue into a widespread availability problem. True redundancy necessitates verified synchronization, independent infrastructure, and regular failover testing.
If the team has never intentionally taken the primary server offline and confirmed that resolution continues, the redundancy is merely theoretical.
DNS zones gradually become inaccurate, not suddenly. Servers get decommissioned, IPs are reassigned, PTR records remain pointing to old IPs, and applications migrate to new platforms without cleaning up old CNAME records. These small gaps accumulate, leading to a DNS environment that no longer aligns with the actual network. Regularly comparing zone data against IP address assignments, DHCP leases, and asset inventories is essential to maintain accuracy.
In dynamic environments, integrating DNS with DHCP and IP address management can significantly reduce manual efforts. Siloed DNS, DHCP, and IPAM data can lead to widening gaps.
Unrestricted write access to DNS poses operational risks, not just security ones. Accidental deletions, typos in critical records, or removal of zone transfer restrictions can all occur in environments with unclear DNS administration boundaries. The principle of least privilege should apply, where engineers troubleshooting do not need permission to modify records, and teams responsible for specific services should have access scoped to the zones they own, not the entire DNS namespace.
Restricting zone transfers to explicitly authorized secondary servers and keeping recursive resolvers away from the internet can prevent unexpected changes.
However, managing DNS requires understanding its role in different organizations. Each environment, whether internal zones, external services, cloud workloads, or hybrid setups, has unique requirements. The key is managing all these elements consistently, encompassing clear zone ownership, documented naming conventions, detailed change procedures, tested recovery processes, and sufficient visibility into how DNS connects various parts of the infrastructure.
As organizations increasingly adopt automated deployments with rapid IP address changes, DNS must evolve from a manual process to an integral part of the stack, requiring consistent management and governance alongside other infrastructure components.
Written by urgent.news from DevOps.com's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.