Speeding Up Software Delivery Is Changing How We Debug Performance
Deployment frequency has become one of the clearest markers of a mature engineering organization. Teams that once shipped monthly now ship daily, and teams that shipped daily now ship several times a day. This shift has largely delivered on its promise. Smaller changes are easier to reason about, rollbacks are faster, and feedback loops are […]
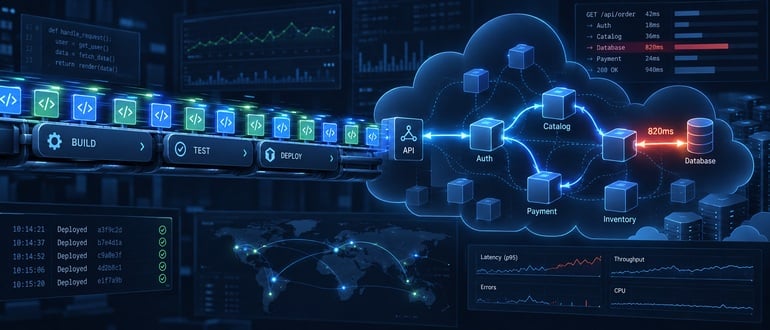
As software development speeds up, a new challenge emerges in debugging performance issues. Teams that once released monthly now deploy daily, and some release several times a day. While this shift has brought benefits like smaller changes and faster rollbacks, it has also complicated performance debugging. Traditional methods rely on a stable baseline to compare against, but with frequent deployments, this baseline moves continuously.
Performance issues can now trace back to any recent deployment, making it difficult to pinpoint the cause. Smaller, frequent deployments simplify review and rollback, but attributing a performance issue to a specific change becomes a process of elimination across many changes. Transaction level visibility, such as tracing specific methods or queries, can help isolate performance issues independent of deployment history.
Dependency mapping also aids in understanding service interactions. However, delivery speed and diagnostic speed are separate measures. An organization can improve deployment frequency without necessarily improving diagnostic time, which can increase if investigation practices haven't kept pace. To address this, runtime visibility should be integrated into every deployment, not added later, to maintain the velocity gained from frequent releases when investigating performance issues.
Written by urgent.news from DevOps.com's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.