The Most Dangerous Reliability Failures Aren’t Component Failures
A production provisioning failure shows why reliability problems can emerge from interactions between healthy components, and how system-level constraints and feedback can prevent them.
When a production system experiences failure, engineers typically investigate which component is responsible. However, this approach may lead to premature conclusions. Some failures occur due to the interaction between components, not individual component malfunctions. Systems-safety methods can help analyze these types of failures.
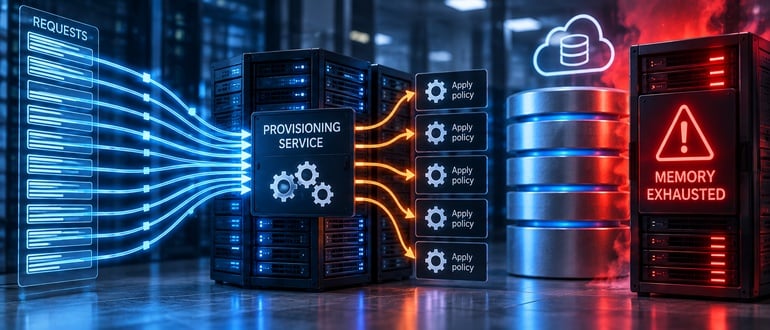
In a large-scale provisioning system, the issue arose when creating storage partitions on demand. The system applied an access-control policy to each new partition using a shared library. The library had been optimized for serial usage but not for concurrent calls, which is how the provisioning service utilized it. Concurrent calls caused memory usage to grow rapidly and eventually exceed the system's limits.
The designers had assumed the policy library's resource cost would remain bounded, but this assumption failed when used concurrently at scale. The solution was to make resource constraints explicit by setting a system-level rule limiting the amount of work the provisioning service accepts based on its resource budget. This approach ensures that the system can handle the combined workload of multiple components behaving correctly simultaneously.
Systems-safety methods like STPA (Specification Through Program Analysis) provide a broader perspective on reliability by considering control actions, feedback mechanisms, and constraints. By analyzing the system as a whole rather than individual components, engineers can identify potential issues before they cause failures.
Written by urgent.news from DevOps.com's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.