Dev proves LLMs will run on anything – even a $10 microcontroller
Nearly 10 tok/s and it's mostly coherent — What's not to like?
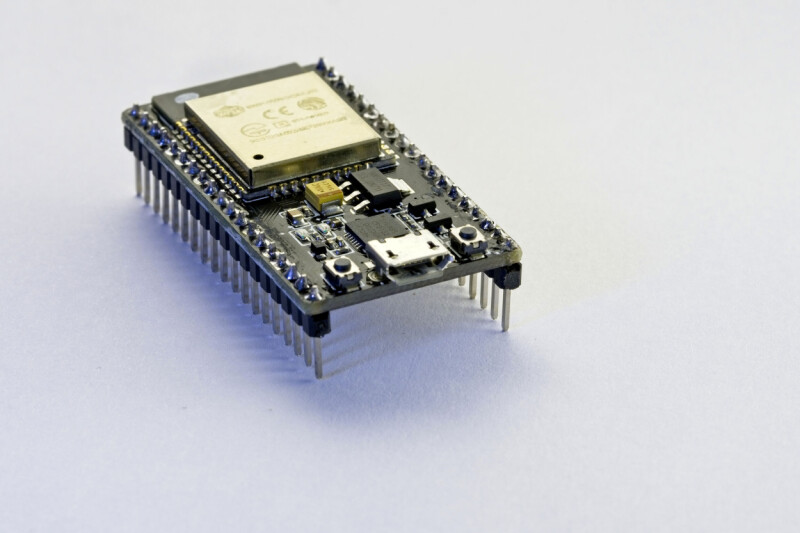
Tiny language models have become increasingly accessible on low-cost devices, even those as small as an ESP32 microcontroller priced under $10. A developer named SlvDev demonstrated this capability, running a TinyStories model on the ESP32-S3 microcontroller, which generated nearly 10 tokens per second. TinyStories is a 28.9 million-parameter model, significantly smaller than typical LLMs, but still challenging to run on such constrained hardware.
To fit the model, SlvDev reduced its precision through quantization, from 16-bit to 8-bit or 4-bit, and leveraged per-layer-embedding (PLE) to offload about 25 million parameters to the ESP32-S3's flash storage, cutting memory requirements by 75 percent. After these optimizations, the model required only 2 MB of memory, mostly in PSRAM and SRAM, achieving 9.88 tokens per second – faster than an average person can read.
However, the practical applications of such localized AI are limited. TinyStories can generate short, coherent stories but is unsuitable for chatbots, code generation, or agent tasks. Even more advanced models like Barista, which perform better, are still too small to be widely practical. That said, the ability to run such lightweight models on ESP32 and similar devices showcases the ongoing advancements in AI miniaturization, enabling local chatbots, calendar management, and resistance to reliance on cloud-based services, despite their occasional inaccuracies.
Written by urgent.news from The Register's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.