Dynatrace just laid out its AI observability playbook at KubeCon. Here’s why it matters for developers.
A new AI model goes live for a small group of users. Some of them start seeing errors. The build The post Dynatrace just laid out its AI observability playbook at KubeCon. Here’s why it matters for developers. appeared first on The New Stack .
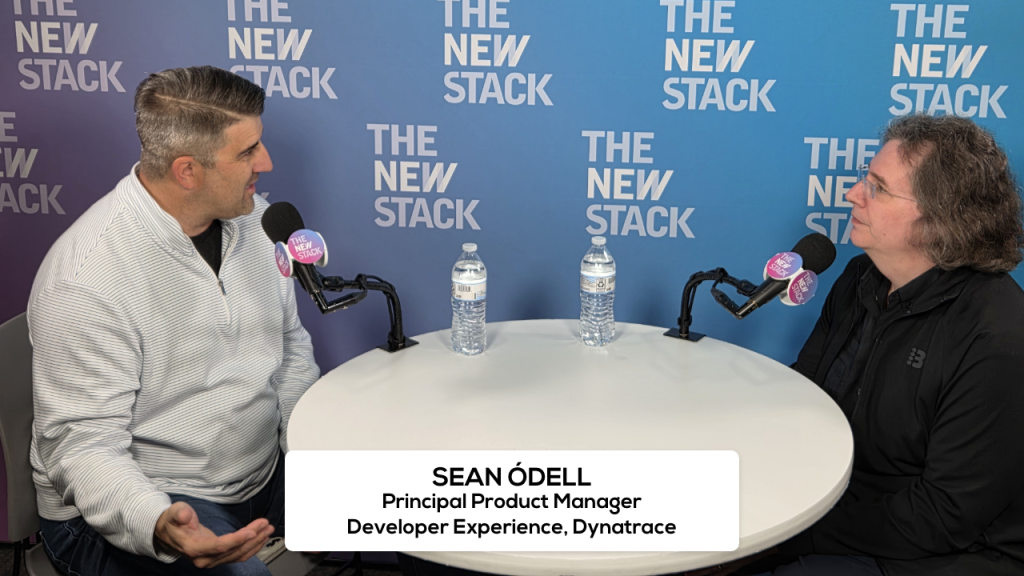
At KubeCon + CloudNativeCon, Dynatrace presented its AI observability playbook, highlighting how the company can simplify investigations for developers. Sean O'Dell, who leads developer experiences at Dynatrace, discussed the importance of identifying which users received a new AI model and understanding what was happening in the application when errors began.
The solution, according to O'Dell, lies in using feature flags to roll out new features or models to a subset of users. By combining this approach with observability data from application code, infrastructure, and AI workloads, developers can quickly pinpoint the root cause of issues.
O'Dell emphasized the significance of OpenFeature in facilitating progressive rollouts, as it allows teams to see both who received a change and how the application behaved afterward. This capability enables teams to disable the feature if it starts causing problems, preventing a flood of theories in the incident channel. O'Dell also mentioned that OpenTelemetry serves as a foundation for AI instrumentation, and OpenInference builds upon it to provide more specialized AI observability.
To effectively troubleshoot complex issues that involve multiple components, Dynatrace recommends using its Grail data lakehouse and Smartscape platforms. These tools help correlate data from various sources, such as services, code changes, and infrastructure modifications, to provide a comprehensive view of the problem. Dynatrace's approach recognizes that telemetry, which provides context about the system's behavior, plays a crucial role in decision-making.
Rewritten by urgent.news; may contain errors — check the original.