These small local models keep saving my 8GB GPU from an upgrade
I'm not upgrading my card any time soon
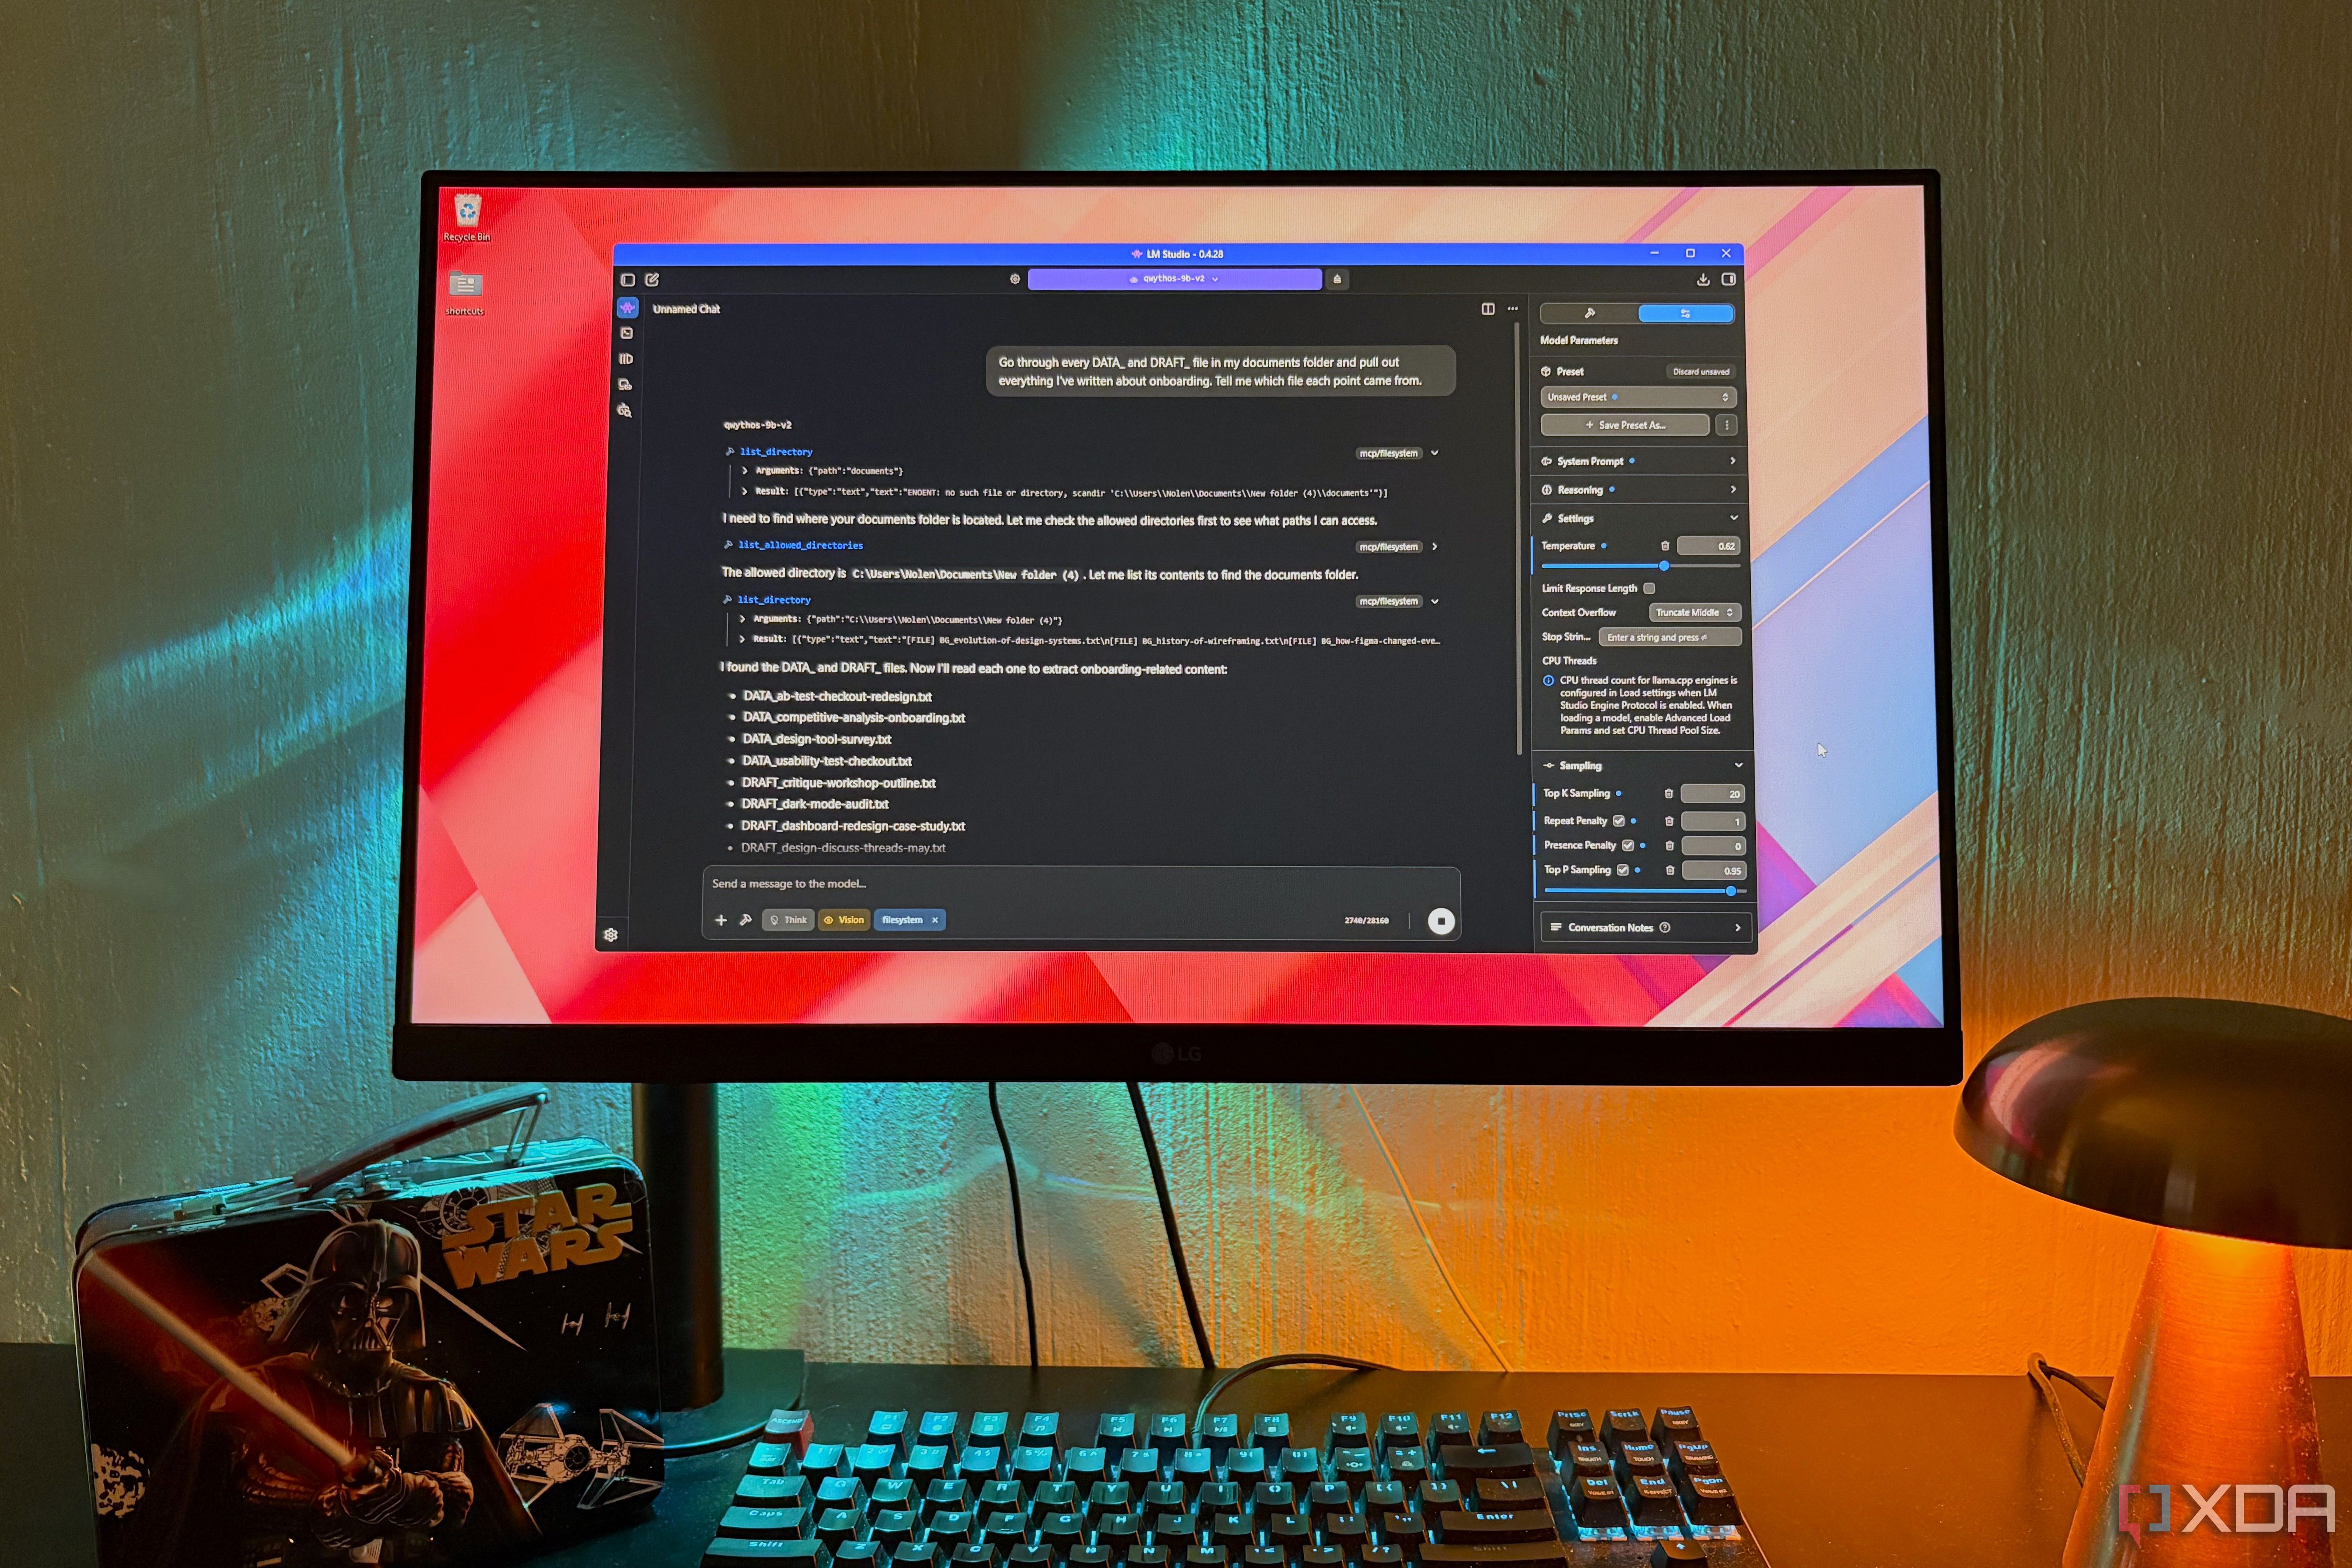
Every few weeks, a new open-weight model emerges, often exceeding the 8GB GPU capacity I currently possess. However, instead of upgrading, I opt to utilize small models that run efficiently on my existing hardware. These models cater to my specific needs, such as handling contracts, legal documents, financial records, and health-related information.
One such model is Gemma 4 E4B, released by Google in April 2026, which boasts 8 billion effective parameters but operates more like a 4.5B model due to its per-layer embedding tables. It can process images and audio inputs, making it versatile for personal research and synthesizing information. Another model, DeepSeek's Llama 3.1 8B, retrained on around 800,000 examples, excels in math and logic tasks.
Additionally, FluentlyQwen3-Coder-4B, a community fine-tune on Qwen3-4B trained on NVIDIA's OpenCodeReasoning dataset, is particularly useful for building simple tracking tools and cleaning up YAML frontmatter on journal entries. Despite newer models being released, these small models continue to serve me well, proving that sometimes less is more when it comes to AI capabilities.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.