(LEAD) Ruling party leader says will push for 10-year exam ban for AI-assisted cheating
SEOUL, Nov. 17 (Yonhap) -- The leader of the ruling Democratic Party (DP) said T...
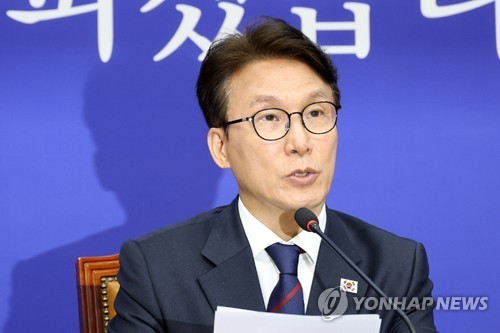
Seoul, Nov. 17 - The leader of South Korea's ruling Democratic Party has announced plans to introduce legislation prohibiting individuals found using artificial intelligence devices to cheat on national exams from retaking the tests for a period of up to ten years. Party representative Kim Min-seok made this statement in an official YouTube video.
He elaborated that while current penalties for exam cheating in South Korea include a five-year ban, extending this ban to ten years would serve as a more effective deterrent against cheating. The DP called for comprehensive measures to be put in place before the upcoming college entrance exam, emphasizing the need for clear guidelines in addressing suspected AI-assisted cheating incidents.
The ruling party's move comes amid growing concerns over the increasing instances of AI-assisted cheating in South Korea, including recent cases involving the use of AI glasses in university entrance exams and middle and high school tests.
Written by urgent.news from Yonhap News's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.