Los Alamos boffins to put NextSilicon's Maverick-2 through natural selection in Darwin testbed
Tiny test system opens door to a new generation of GPU-less supers
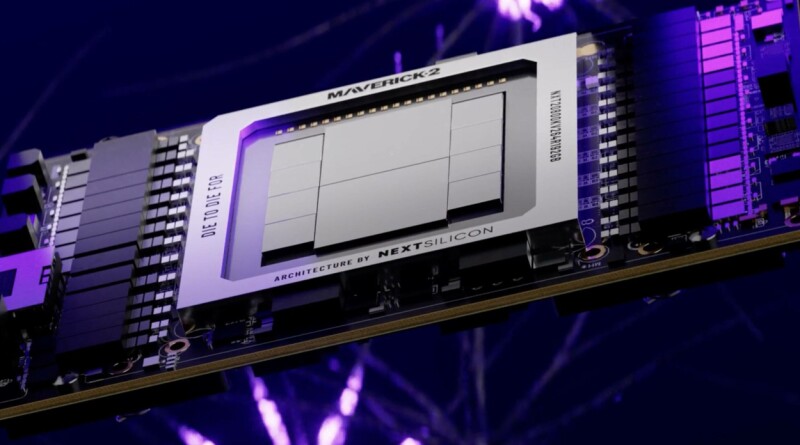
The US Department of Energy (DoE) is strengthening its partnership with HPC-first chip startup NextSilicon. At the Supercomputing 2026 event in Chicago, the Israeli company unveiled that the agency had installed its second Maverick-2 cluster in the Darwin testbed at Los Alamos National Laboratory (LANL). This deployment occurred just six months after LANL powered on NextSilicon's first supercomputer, featuring 64 nodes and 128 of the company's "runtime-configurable" accelerators.
While the latest DoE system is smaller, with only four accelerators, it is more significant for LANL because it offers rapid evaluation and integration of new technologies. Darwin serves as a long-lived testbed environment where LANL brings in newer technologies for evaluation, allowing the lab to quickly validate and port codebases to the chips, identify issues, and collaborate with NextSilicon to influence future chip capabilities.
Los Alamos' interest in Maverick-2 is the first step toward deploying NextSilicon silicon in larger-scale future DoE supers. Many of LANL's critical workloads, such as multi-physics simulations for nuclear deterrent effectiveness and energy sources like fusion reactor fuel candidates, cannot be run on public systems. These workloads involve complex simulations with varying compute requirements, making it challenging to identify a specific platform that performs optimally for all.
CPUs excel at workloads with large serial sections and irregular access patterns, while GPUs are ideal for dense matrix-multiplication heavy tasks. NextSilicon's Maverick-2, however, uses a dataflow architecture that overlaps communication and computation, with a grid of arithmetic logic units (ALUs) configured to perform operations as needed.
This architecture can be extremely efficient in bandwidth-bound scenarios, which has implications for HPC, scientific computing, and AI inference clusters. NextSilicon has developed a compiler that can decompose existing codebases into a graph that can run directly on its chips, making it easier to validate the systems against various benchmarks, such as HPCG, LAMMPS, and Sparta.
Written by urgent.news from The Register's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.