My 8GB laptop now runs an AI that can see and talk, and it never goes online
Small LLMs are doing less for more, and I'm here for it
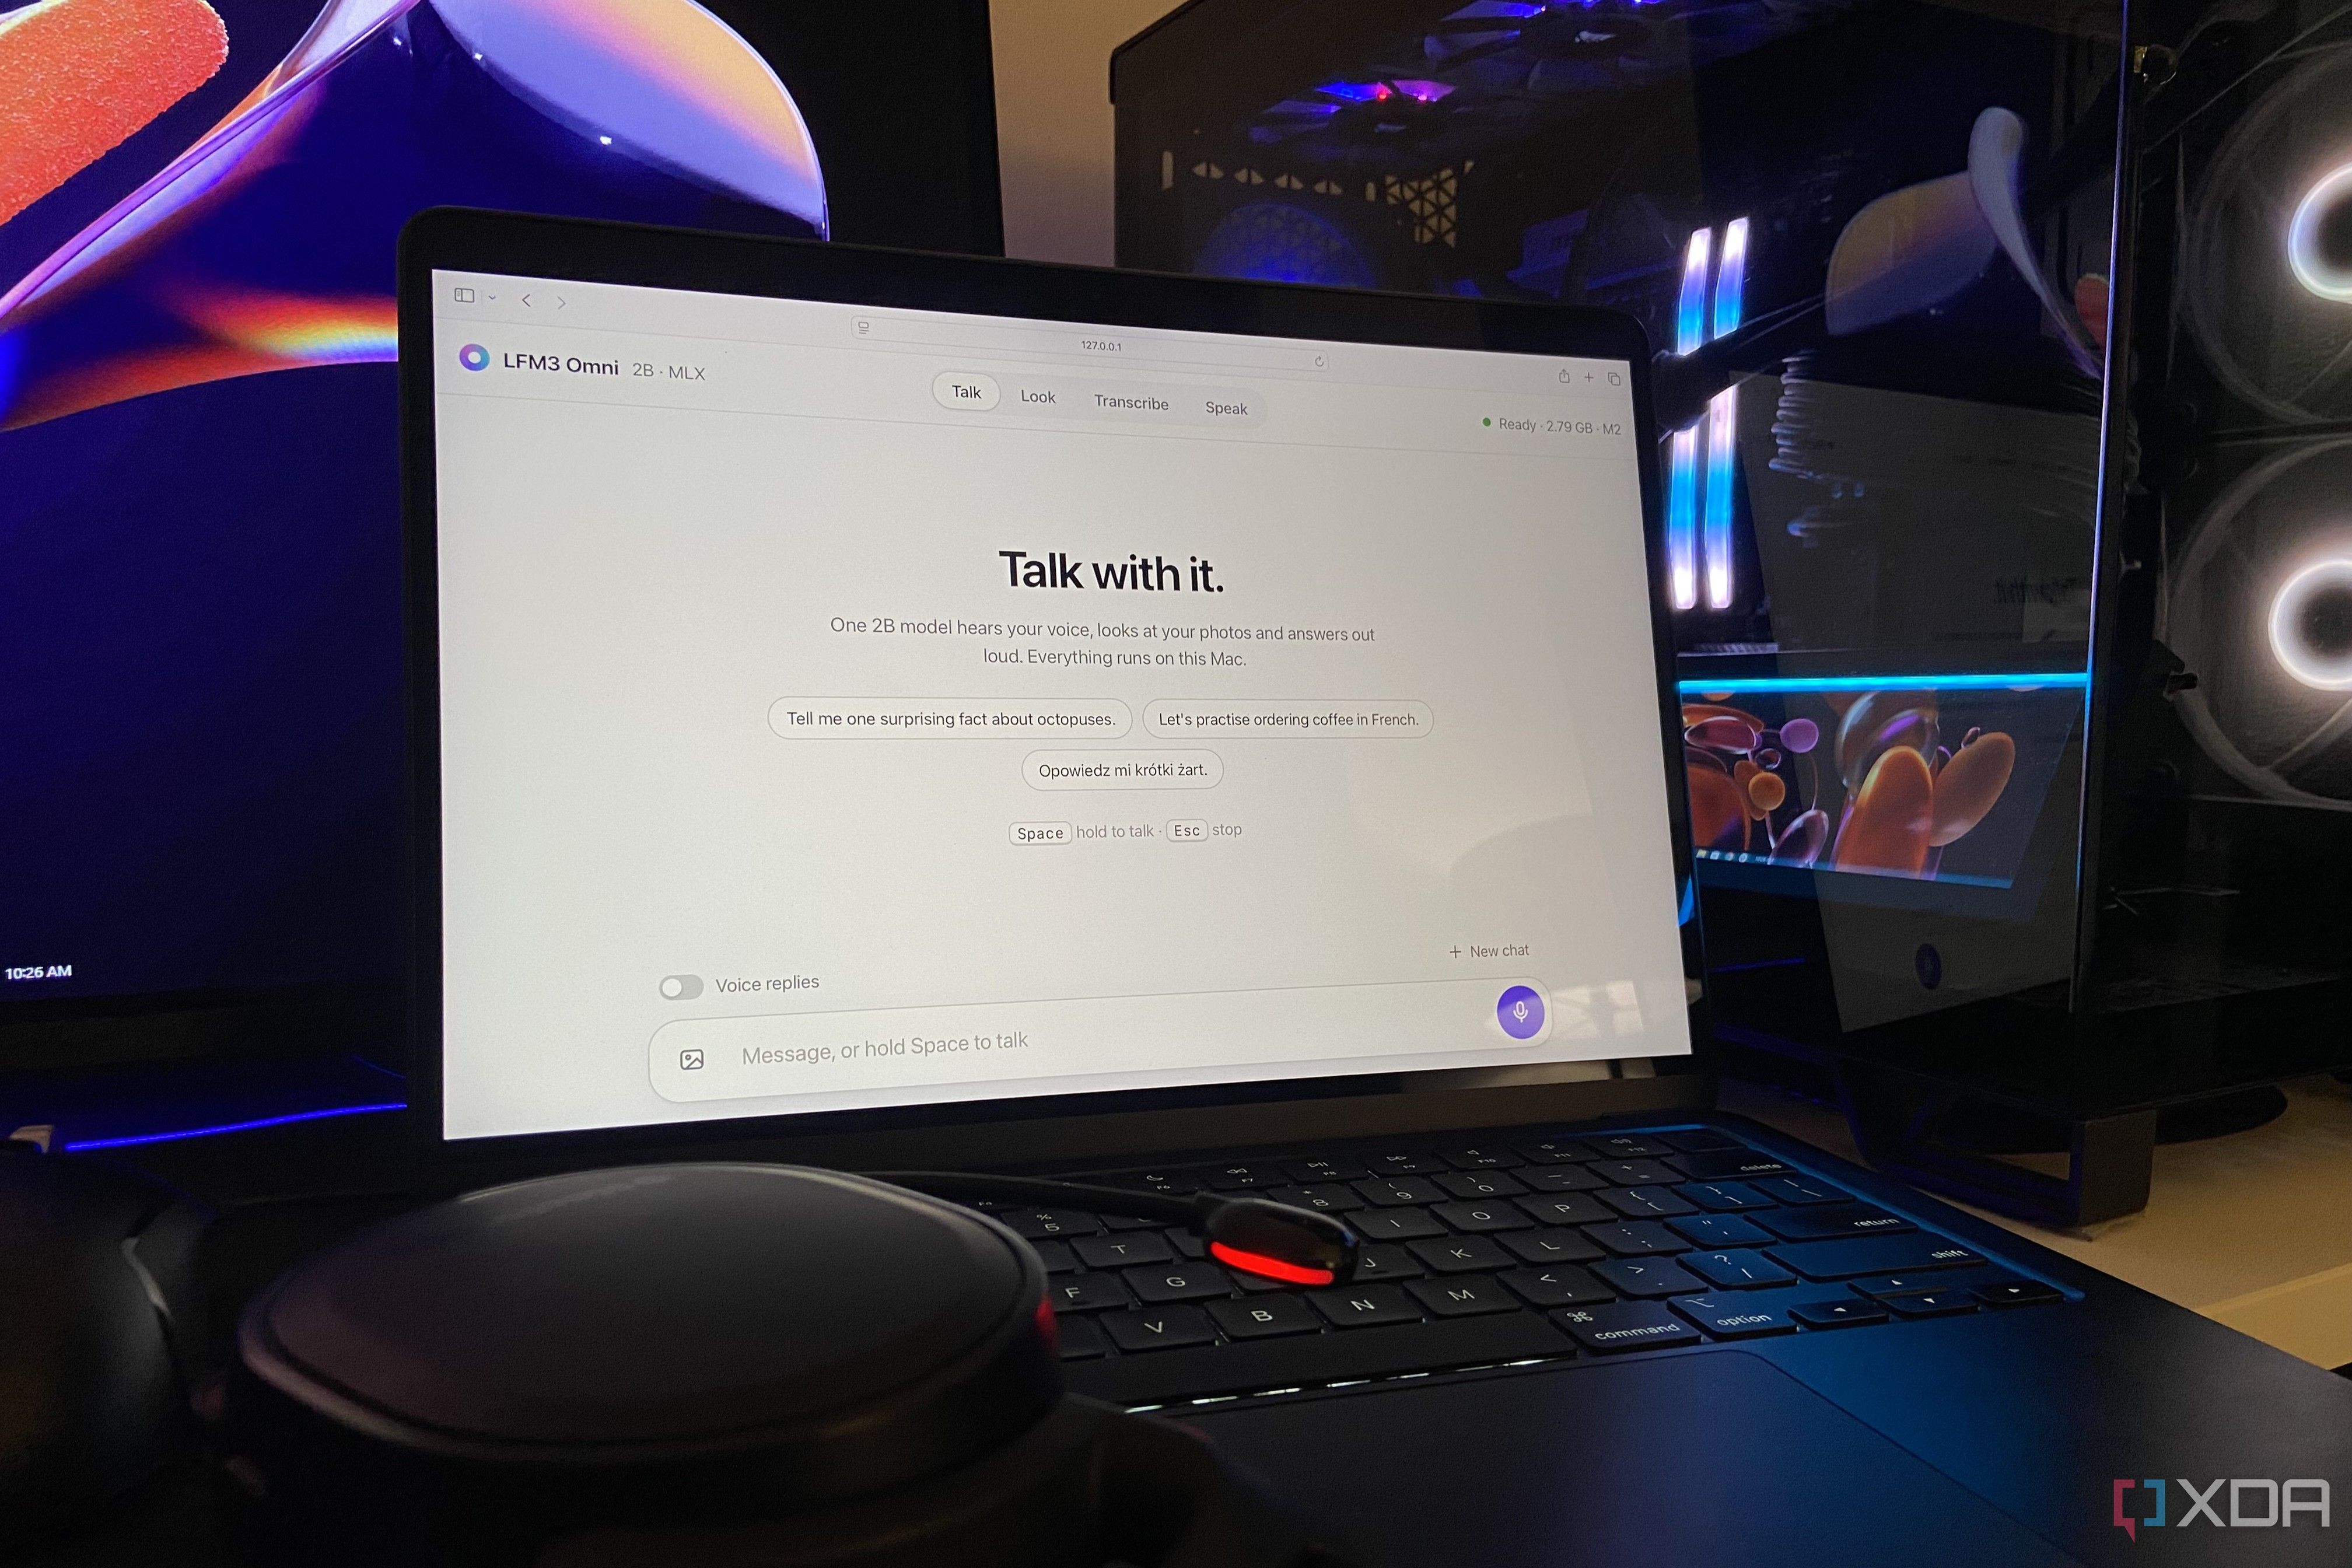
My 8GB MacBook Air, a device usually insufficient for running sophisticated local large language models, has now been equipped with an AI model named LFM3-Omni. This model, boasting just 2.2 billion parameters, released on October 27, can process images, video, and speech and respond either in text or speech. What sets this model apart is its ability to perform all these tasks on the 8GB system without needing to connect to the internet.
Developed by Liquid AI, LFM3-Omni is an open-weight model released under the LFM Open License v1.0. I initially attempted to run it via Ollama, but it only supported text and vision processing. To enable speech capabilities, I utilized a free community app called lfm3-mega-demo, built by a developer known as overment on Github. This app employs Liquid's official 8-bit build through Apple's MLX framework to display a web interface with tabs for talking, looking, transcription, and speech generation.
While I was wary about potential sampling settings in the app, my checks revealed that the app adheres to the same greedy text decoding settings as the model itself. When running the app, I found that the peak memory usage for the app was around 2,968MB, with about 2,814MB dedicated to the model within the Mac's shared memory. This demonstrates the impressive efficiency of LFM3-Omni, leaving ample memory for other tasks.
To evaluate its vision capabilities, I tested the model by presenting various objects to the webcam through the Look tab. The model accurately identified a DualSense controller as a black PlayStation controller and a TKL keyboard as a mechanical keyboard, even when the latter was a compact board without a numeric keypad. During a numerical analysis test, I provided the model with a table of PC components and asked a series of questions.
The model successfully extracted the correct information, with the exception of arithmetic errors, which were attributed to a design choice rather than a limitation of the model's vision capabilities.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.