Kubernetes Is Resilient. Your Recovery Path May Not Be.
Cloud-native infrastructure has changed the way organizations think about resilience. Kubernetes can restart failed containers, replace pods, schedule workloads on healthy nodes and help applications recover from failures that once required manual intervention. That is real progress. But there is a difference between keeping workloads running and keeping infrastructure recoverable. The post…
Kubernetes has transformed how businesses perceive resilience, enabling it to restart faltering containers, substitute pods, and reallocate workloads to healthy nodes, thereby assisting applications in recuperating from failures that once demanded manual intervention. While this advancement is commendable, a critical distinction must be drawn between maintaining operational workloads and ensuring the recoverability of the underlying infrastructure.
When a failure occurs within the infrastructure supporting a Kubernetes environment—be it a router, switch, firewall, WAN connection, DNS service, or management network—the platform might continue functioning, yet the personnel tasked with restoring complete service may lose the ability to access the systems necessary for rectification.
This phenomenon, known as the recovery-path problem, warrants greater recognition as cloud-native ecosystems grow larger, more dispersed, and increasingly entrusted with AI workloads. While the majority of resilience planning revolves around redundancy—constructing multiple clusters, multiple availability zones, redundant links, redundant power supply, and automated failover mechanisms—redundancy alone does not guarantee recoverability.
For instance, a routing alteration that isolates a group of Kubernetes nodes, a firewall policy that obstructs management access, or a WAN outage that disconnects an edge location can still allow workloads to function for a brief period. Monitoring may even aid the operations team in pinpointing the root cause. However, if engineers rely on the same production network to reach the switches, routers, firewalls, and servers implicated in the incident, a network failure can sever the very conduit required to diagnose and rectify the issue.
At this juncture, the question shifts from "Is the application resilient?" to "Can we still reach the infrastructure?" Cloud-native teams have substantially invested in observability, with great reason. Metrics, logs, traces, and increasingly AI-assisted operations can expedite the identification of issues. Nevertheless, visibility and control are distinctly separate capabilities.
A monitoring platform can inform an engineer that a switch is inaccessible or that a cluster has lost connectivity; however, it cannot assure that the engineer maintains a reliable path to the affected device. The same principle applies to automation. Automated remediation proves invaluable when the control plane and management path remain intact.
Yet, when those dependencies become part of the failure, automation may become inaccessible alongside everything else. Consequently, a resilient architecture must address two pivotal inquiries: Can we detect the failure, and can we still reach the infrastructure essential for recovery? The second question is frequently neglected.
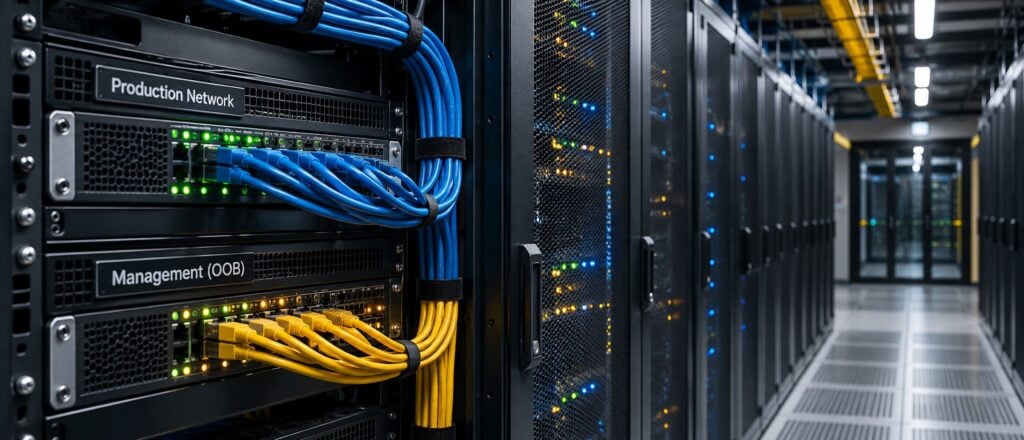
For critical infrastructure, the recovery path should be as independent as feasible from the production path it aims to restore. This may encompass dedicated out-of-band management networks, direct console access to critical infrastructure, alternate WAN or cellular connectivity, securely managed credentials, and the capacity to execute fundamental recovery actions without depending on the primary network.
The objective is not to devise an additional convoluted management environment. In fact, complexity exacerbates recovery challenges. During an outage, teams necessitate a straightforward, predictable means to access the infrastructure, comprehend the changes that transpired, and execute controlled actions. This consideration becomes even more imperative in distributed settings.
A centralized data center may have engineers in proximity. Conversely, an edge site, branch office, colocation facility, or remote AI deployment could be hundreds or thousands of miles away from the personnel responsible for its operation. Without an independent recovery path, a configuration error that should consume ten minutes to rectify might evolve into a truck roll—an extended outage—or both.
Disaster recovery drills typically evaluate whether workloads fail over effectively or whether applications remain operational subsequent to a server or site failure. These assessments are crucial, yet they do not encompass the full spectrum of infrastructure recoverability. A valuable resilience exercise should also presuppose that the standard management path is unavailable.
Can the team still access the network infrastructure? Can engineers engage a console when production IP connectivity is lost? Are recovery credentials accessible and safeguarded? Can someone remotely cycle power when a device becomes unresponsive? Is there a documented protocol for regaining control before attempting broader restoration?
These constitute operational questions, not merely networking queries. Platform engineering, SRE, network operations, and security teams all bear responsibility for the answers. As Kubernetes expands into AI infrastructure, the recovery-path issue assumes heightened significance. GPU clusters introduce costly compute resources, high-speed switching, specialized networking, storage dependencies, and considerable power and cooling requirements.
As Kubernetes assumes the role of a control layer for these environments, application and infrastructure operations become increasingly intertwined. A failure within the underlying network can impact more than merely application connectivity; it can disrupt training jobs, inference services, storage access, and access to expensive infrastructure that organizations aspire to maintain at high utilization rates.
The more valuable and distributed the infrastructure becomes, the more imperative it is to preserve a path to control it. While Kubernetes excels at engineering systems that anticipate component failures, the subsequent step entails extending this assumption to the management path itself. Organizations should not merely query whether their Kubernetes environment can endure a failure; they should also inquire whether their operations team retains the ability to reach, diagnose, and recover the infrastructure when the standard network is unavailable.
Kubernetes can render workloads remarkably resilient; however, when the underlying infrastructure falters, resilience fundamentally hinges on preserving a decisive means of access.
Written by urgent.news from Container Journal's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.