I gave OpenCode a local model on my 8GB card, and stopped worrying about hitting Claude's rate limits
My GPU handles the boring work now
Even though OpenAI has improved Claude's rate limits this year, they still occasionally reach inconvenient limits. Often, these limits are reached when a session is fully utilized on routine tasks, such as checking the contents of a large folder of files before organizing them. Tasks like these do not necessarily require Claude's top models.
A gaming PC like mine, equipped with an 8GB GPU, can run capable models locally. OpenCode, a free rival to Claude, can work with any local model you point it at. The real question is whether my 9B models could handle the same tasks that typically increase my Claude usage.
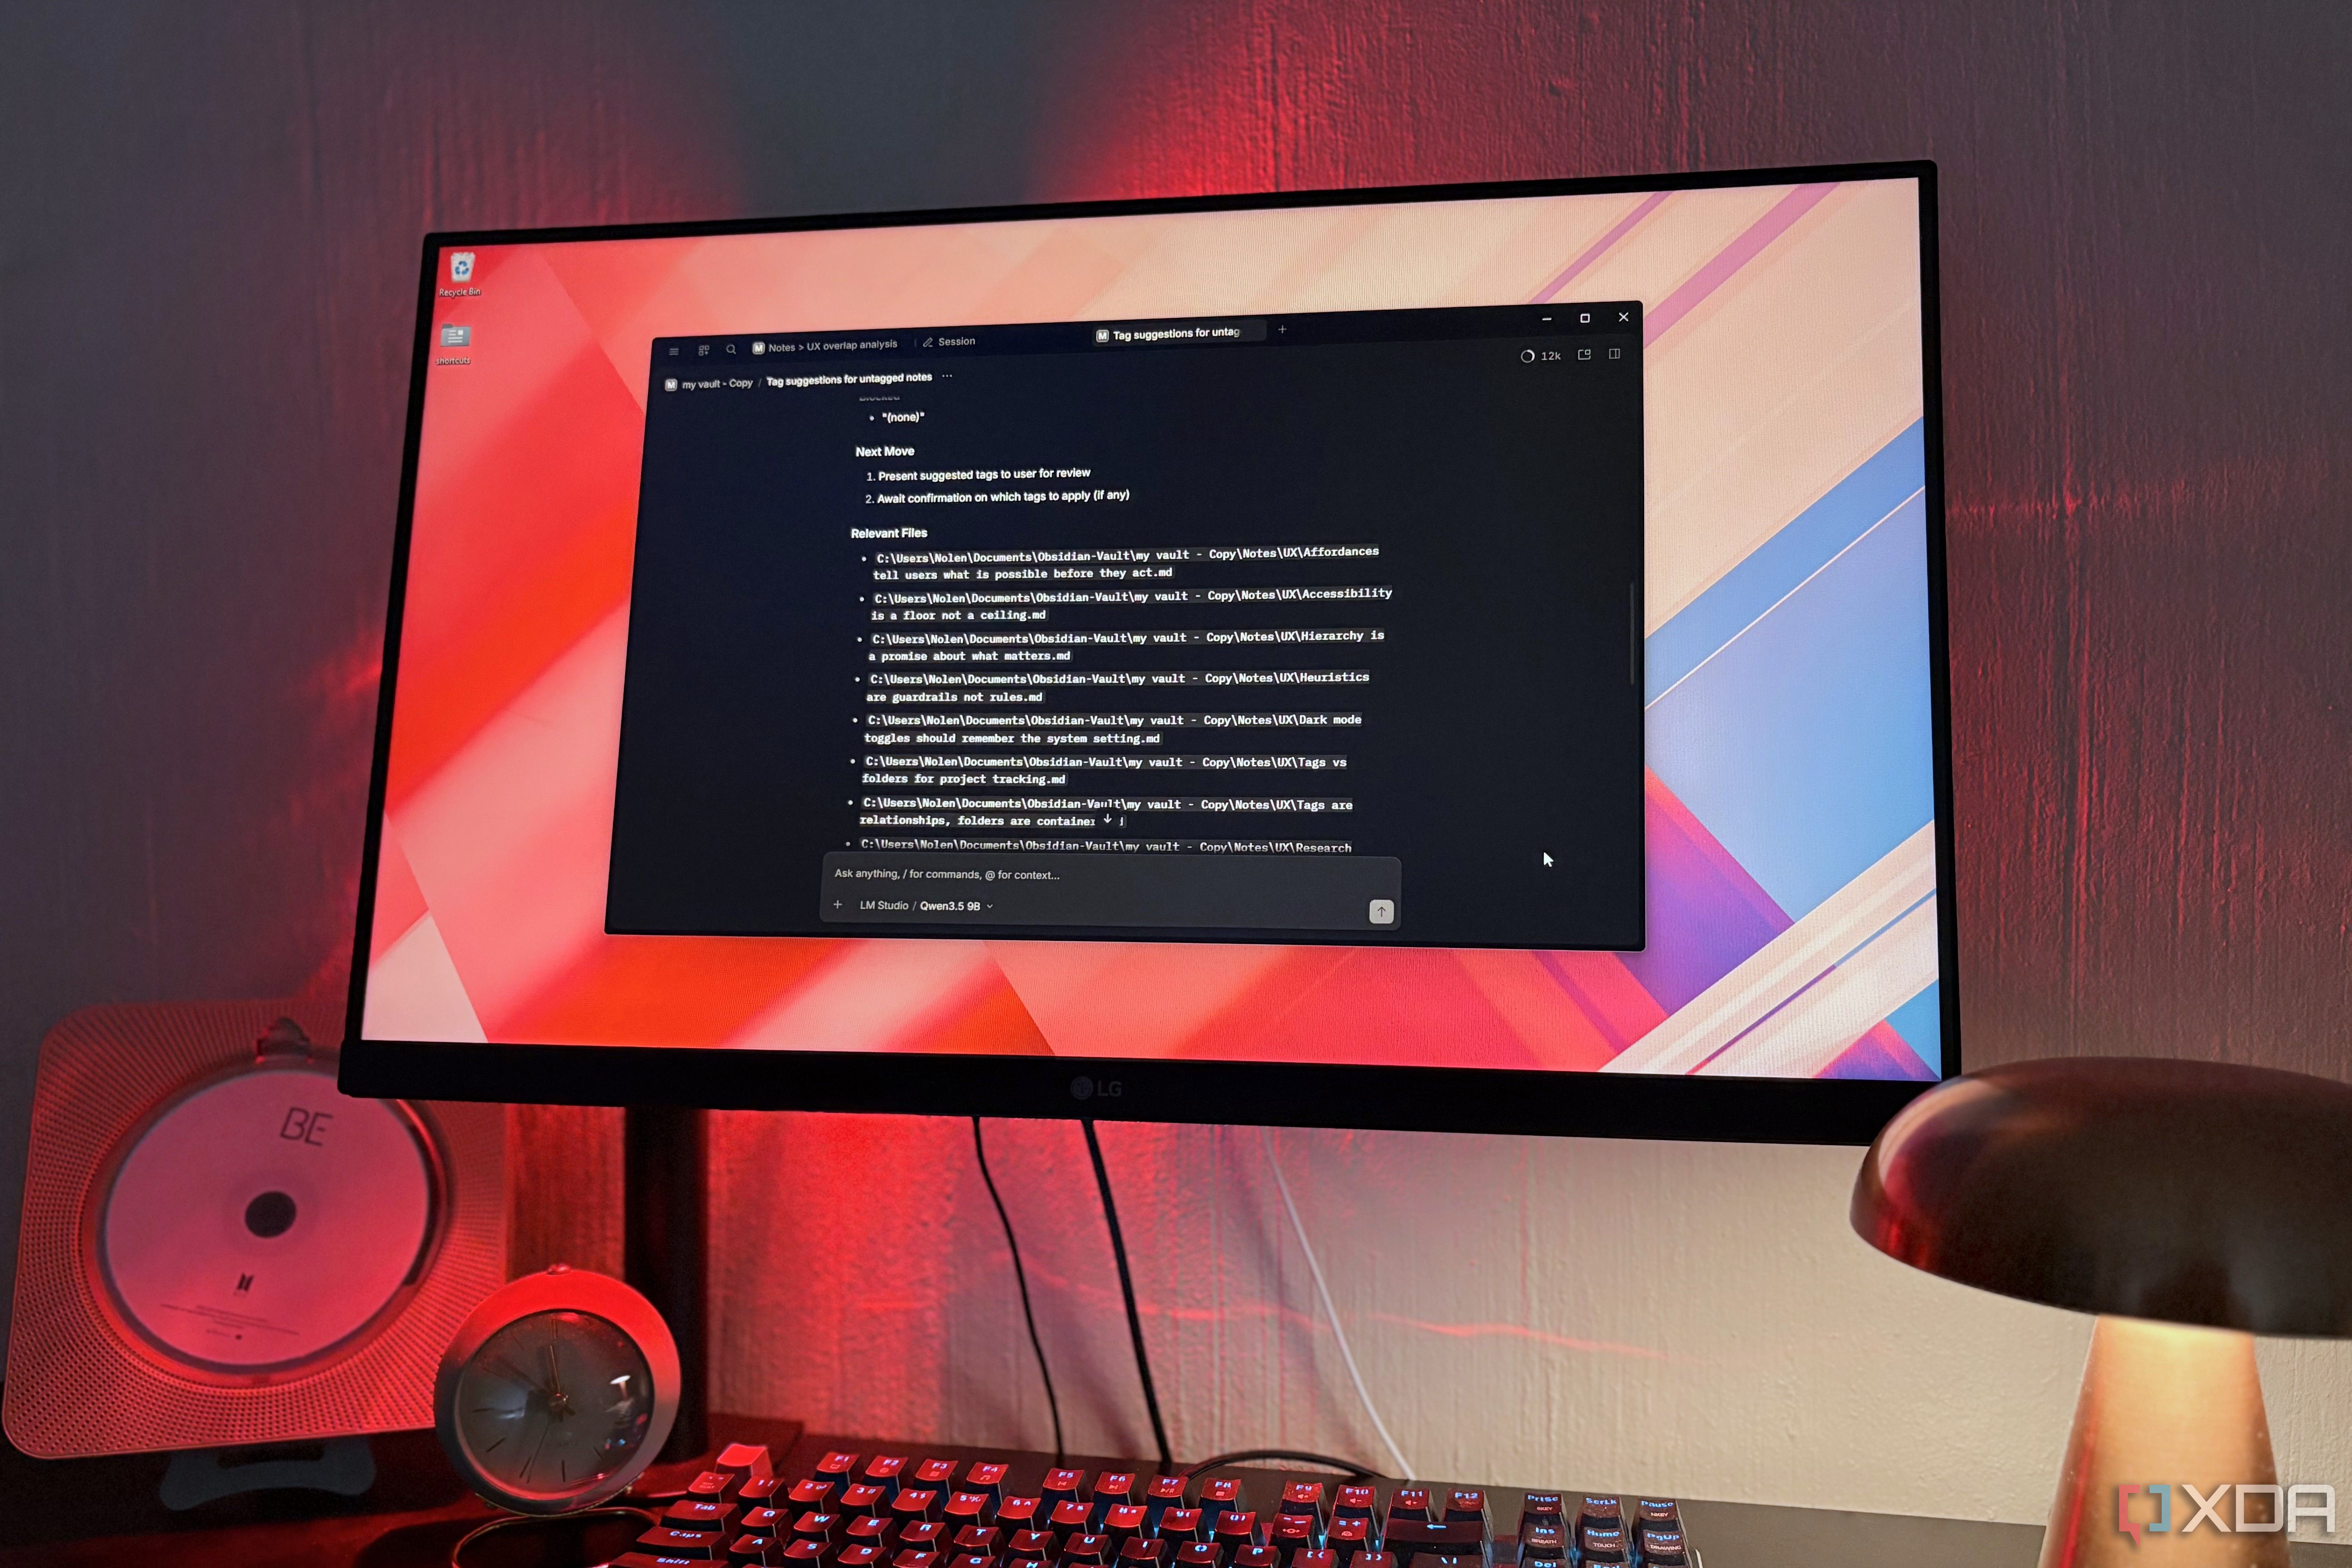
I started using OpenCode's desktop app due to its superior visual interface for AI agents. I loaded my models, Qwen 3.5 9B and Qwythos 9B, both quantized at Q4_K_M and strong at tool calling, into OpenCode. OpenCode picks up models from LM Studio, Ollama, and vLLM automatically as long as they're running on their usual local addresses.
I loaded my LM Studio library of models into OpenCode's settings and toggled on the ones I wanted in the model picker. OpenCode allows the model to read files, which gets added to the conversation and can quickly exhaust the context limit if the context is set low.
I first asked Qwen to find untagged notes across my entire Obsidian vault, but it kept opening files until the context ran out. I then limited it to a small folder, which worked. Qwythos reasons through problems before answering, which can make it slow. Despite this, it provided useful insights, connecting notes I hadn't considered.
OpenCode makes edits to specific lines and shows a diff of changes, taking snapshots of file changes to allow undoing within the session. Both models showed good instruction adherence, making precise changes without touching other parts of the files. However, they struggled with formatting. My hardware and the models I can run are my biggest constraints.
OpenCode's context meter showed that eight file reads took up around 17k context tokens, limiting me to one file or a small batch at a time. This covers many tasks, like fixing button labels across a couple of files. While Claude handles more complex tasks, my GPU can handle smaller, routine tasks that add up, draining my usage.
I still use Claude for more powerful needs, but rely on outdated models that still get the job done.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.