Nature Medicine, Published online: 29 October 2026; doi:10.1038/s41591-026-04655-5 A multimodal vision language foundation model, EVLF-FM, integrates extensive clinical data and advanced training techniques, achieving superior diagnostic accuracy and explainability across diverse imaging modalities, enhancing clinical decision-making through robust reasoning and interpretability.
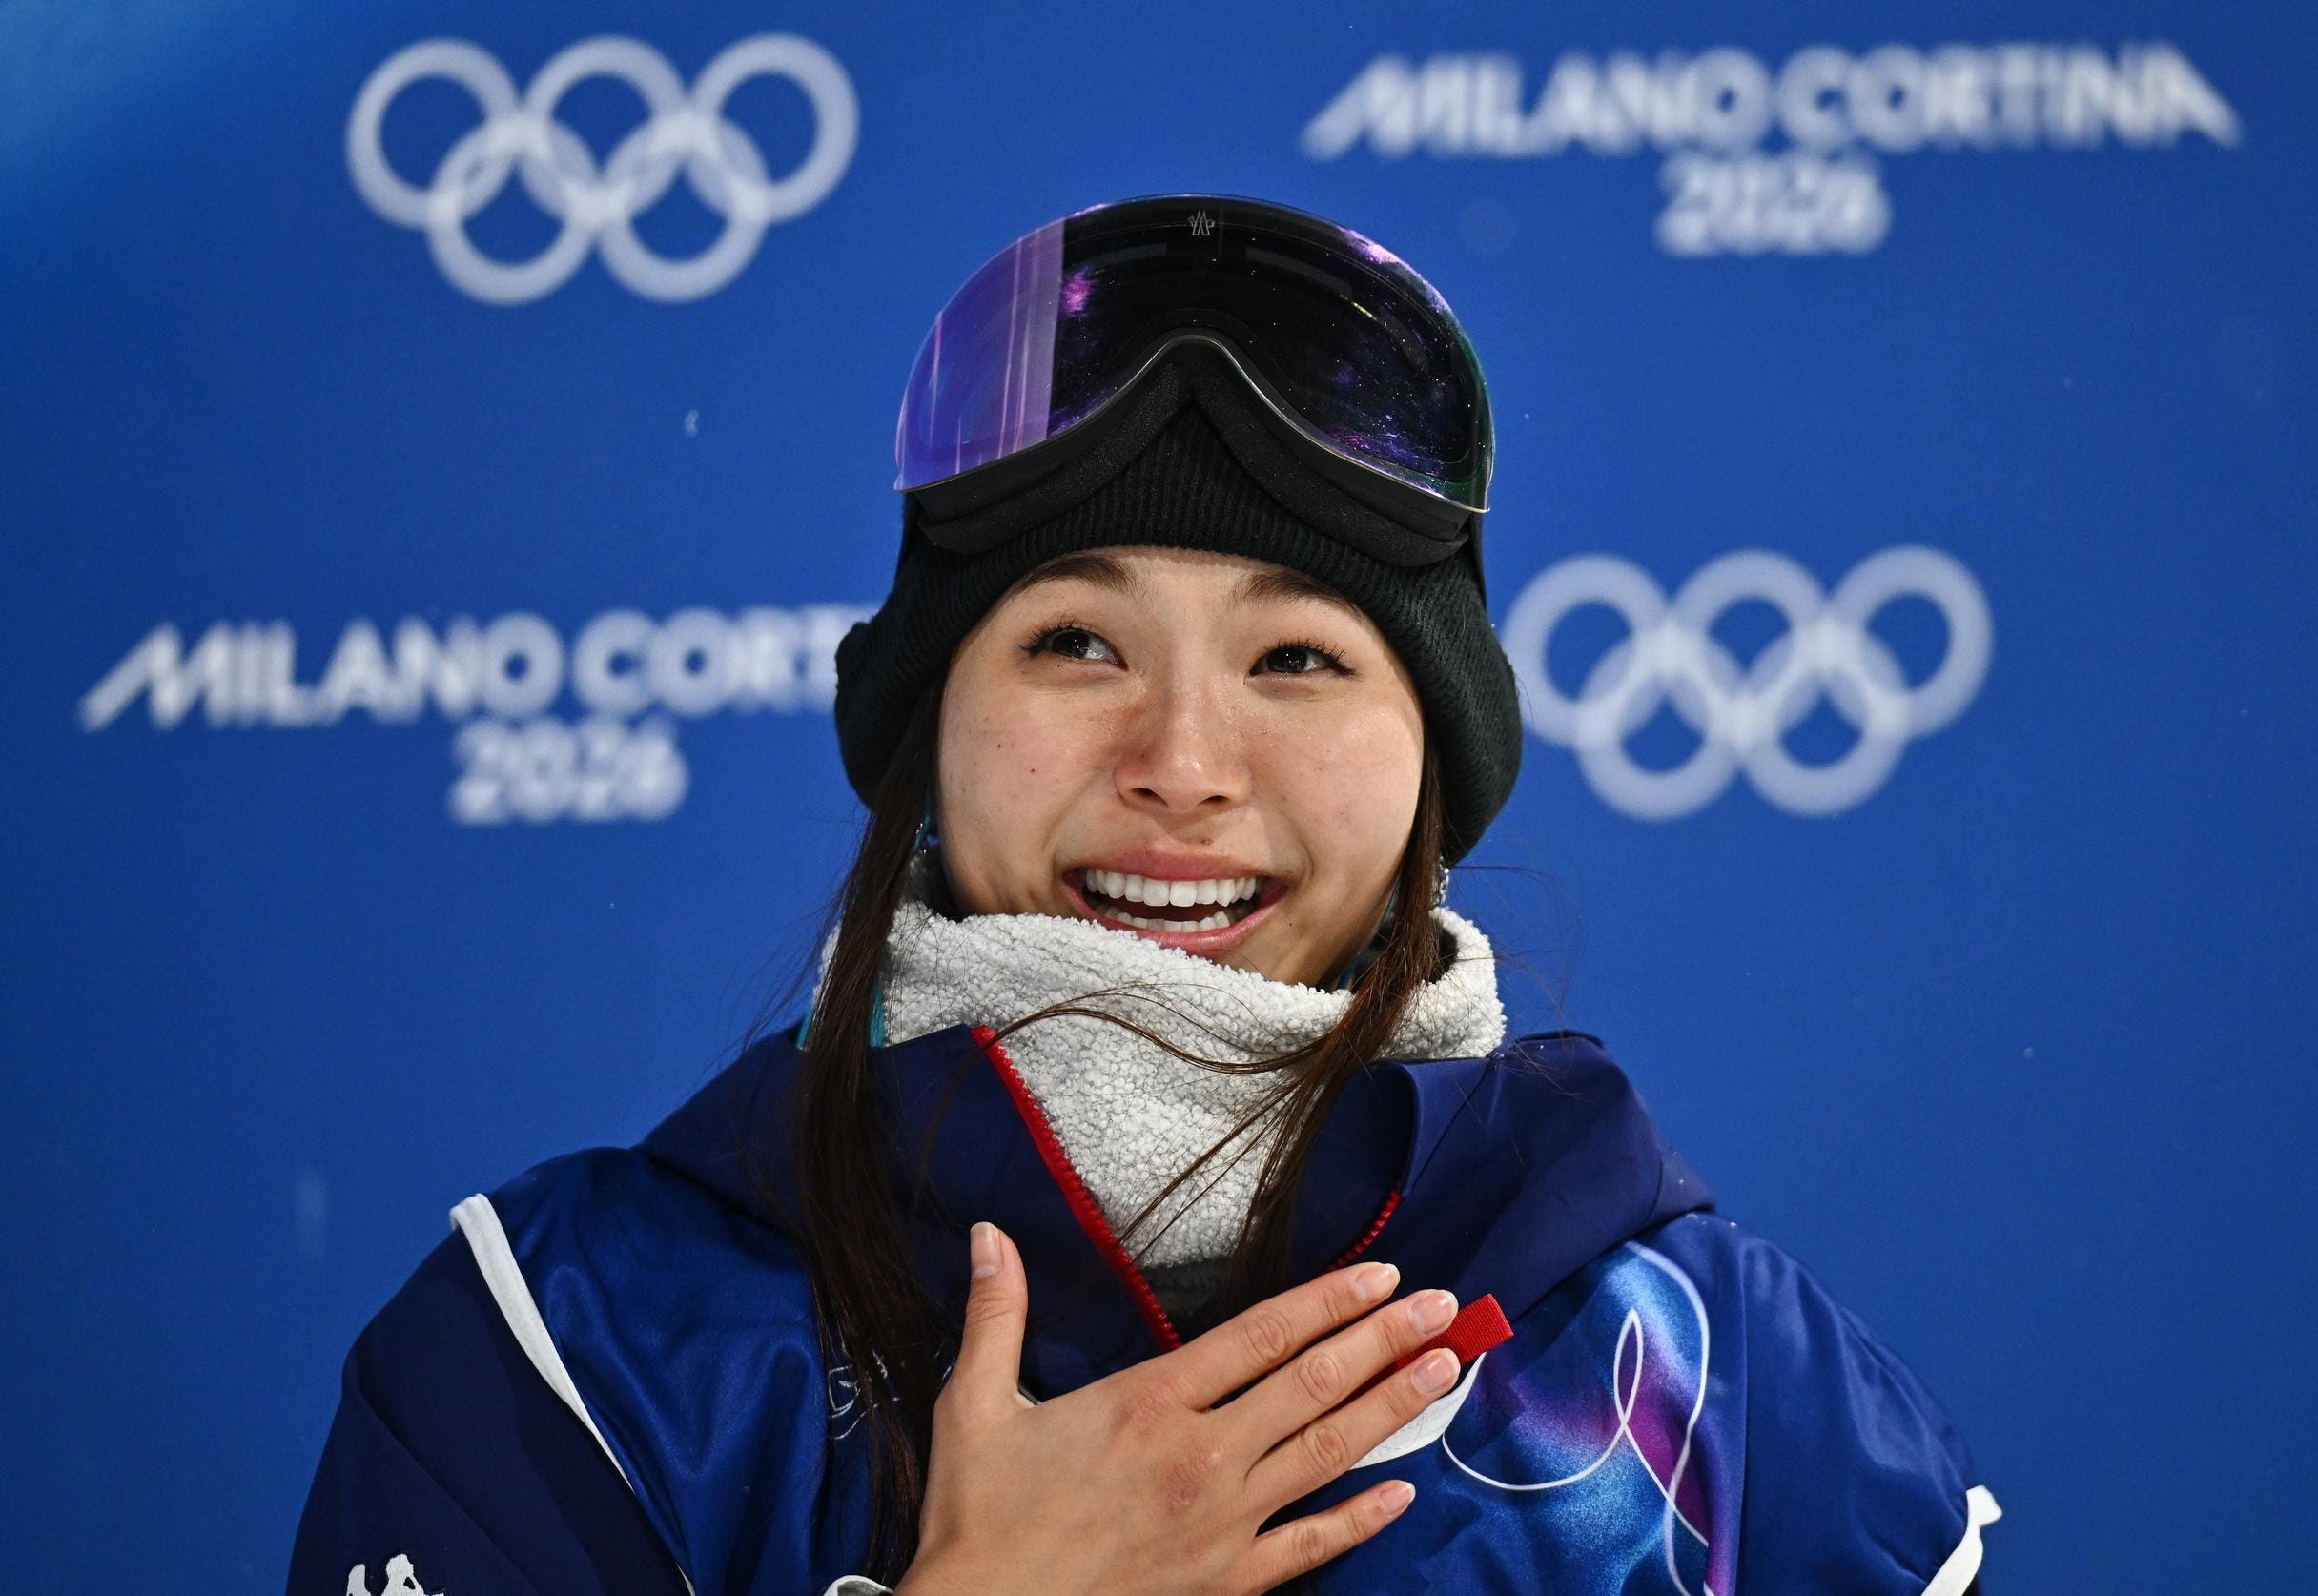
Two-time Olympic gold medalist snowboarder Chloe Kim discusses how her recent diagnosis with attention-deficit hyperactivity disorder took a while and her ADHD treatment
Medical experts have advised women to prioritise their health and well-being by paying attention to their bodies and adopting healthy lifestyles to reduce Read More…