Reconstructing Microservice Topology at Incident Time
Learn how temporal dependency graphs and incident-time topology reconstruction help engineers investigate microservices failures & narrow root cause hypotheses.
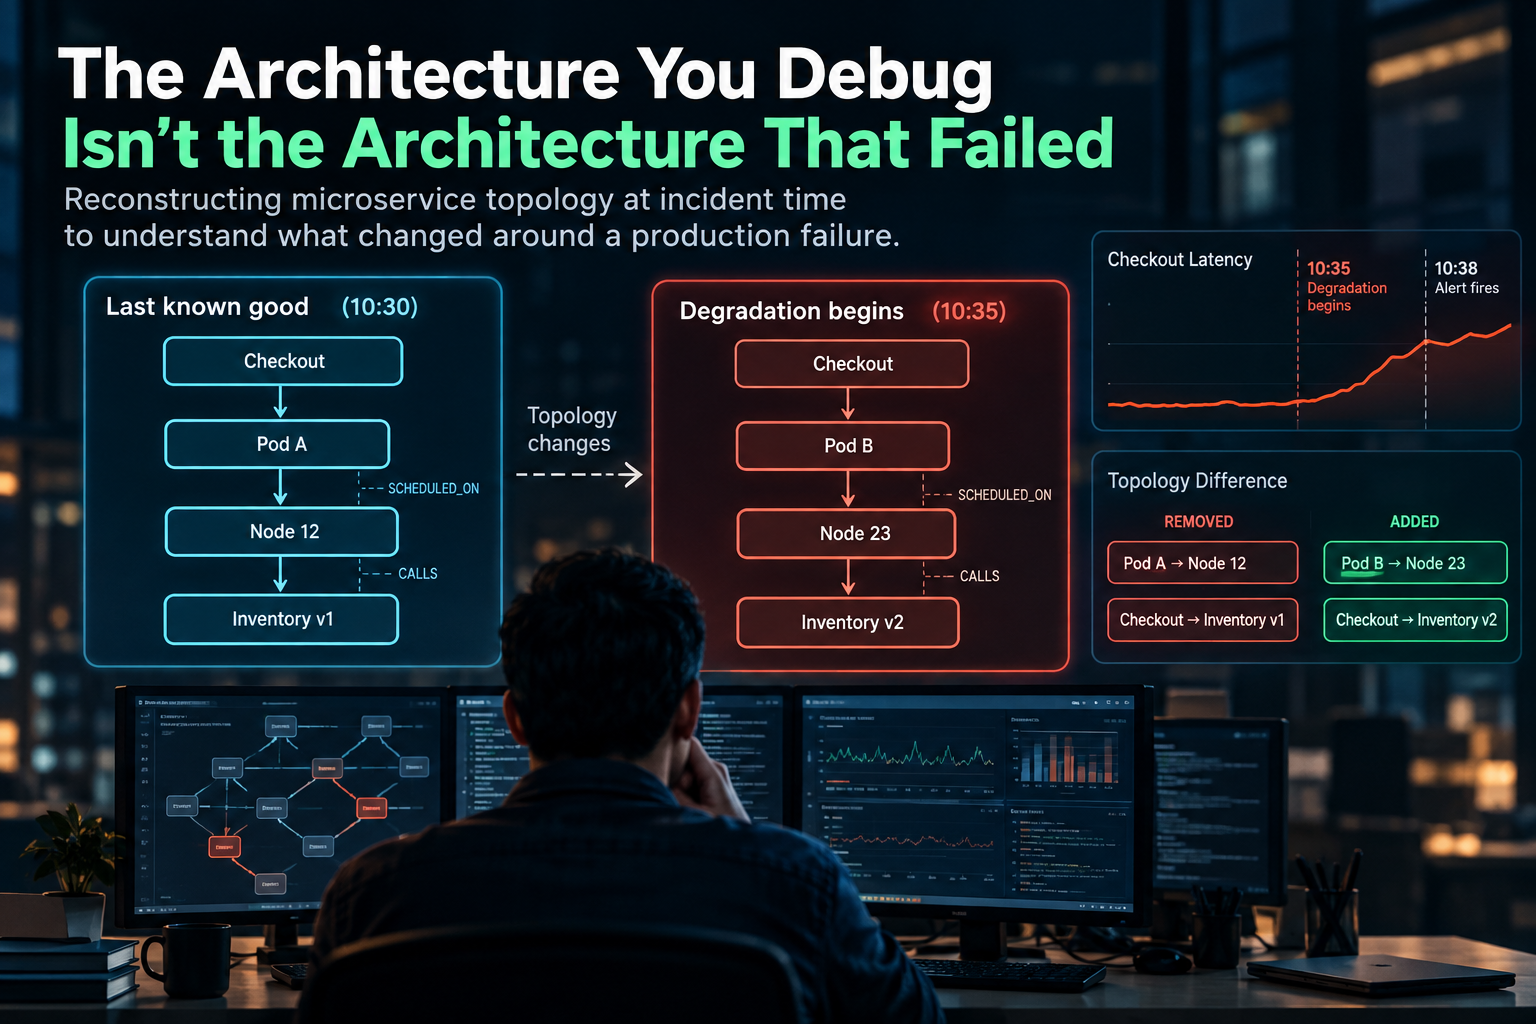
Microservices bring inherent ephemerality to systems due to frequent state changes based on various environmental conditions. During production incidents, the architecture rarely remains stationary. Deployments, scheduler moves, changing endpoints, and shifting service-to-service traffic all occur while an incident evolves. The investigator's dashboard may show a different system state from the one that initially caused symptoms.
Modern observability systems can provide metrics, traces, and change logs for root cause analysis. The challenge is understanding what changes took place between the current degraded state and the last known healthy state. Reconstruction becomes crucial to understand what alterations are around the failure and correlate those structural changes with behavioral evidence.
A conventional dependency graph, G = (V, E), where vertices are entities and edges represent relationships, is insufficient for incident analysis. The time-aware topology model, G(t), captures relationships valid at a specific point in time, treating connections as temporal state. By comparing G(t1) to G(t2), we can identify structural changes that occurred around the incident.
Not all changes are root causes, but they serve as focused contributors to evaluate using telemetry and other evidence. Incident analysis does not require a comprehensive record of all service relationships in production. Focusing on critical information reduces operational overhead. The useful topology includes critical information that explains the operating context of the affected service, its logical dependencies, workload instances, running locations, and any influencing infrastructure relationships.
The approach varies depending on the incident, from a service-level dependency graph for latency changes to expanding the investigation into pods and nodes for placement-sensitive incidents. Correlating topology changes with behavioral telemetry allows for building a causal analysis, effectively a frame-by-frame playback of the incident.
To begin, identify the incident timestamp, Tincident, which marks the first observable point of service degradation, often later than when the fault started. Establish a known-good comparison point, Tgood, before the incident. Reconstruct both topology states at these timestamps, targeting pertinent information and expanding into auxiliary dependencies as needed.
Calculate the topology difference to highlight changes in entities and relationships, filtering out the few relationships that changed. Finally, overlay behavioral evidence on the changed entities to correlate service degradation signs with structural changes.
Written by urgent.news from HackerNoon's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.