I tested Nvidia’s Nemotron 3.5 Bolt, and it changed what I thought my 16GB GPU could do
A 16GB GPU can run agentic AI now, and it's surreal
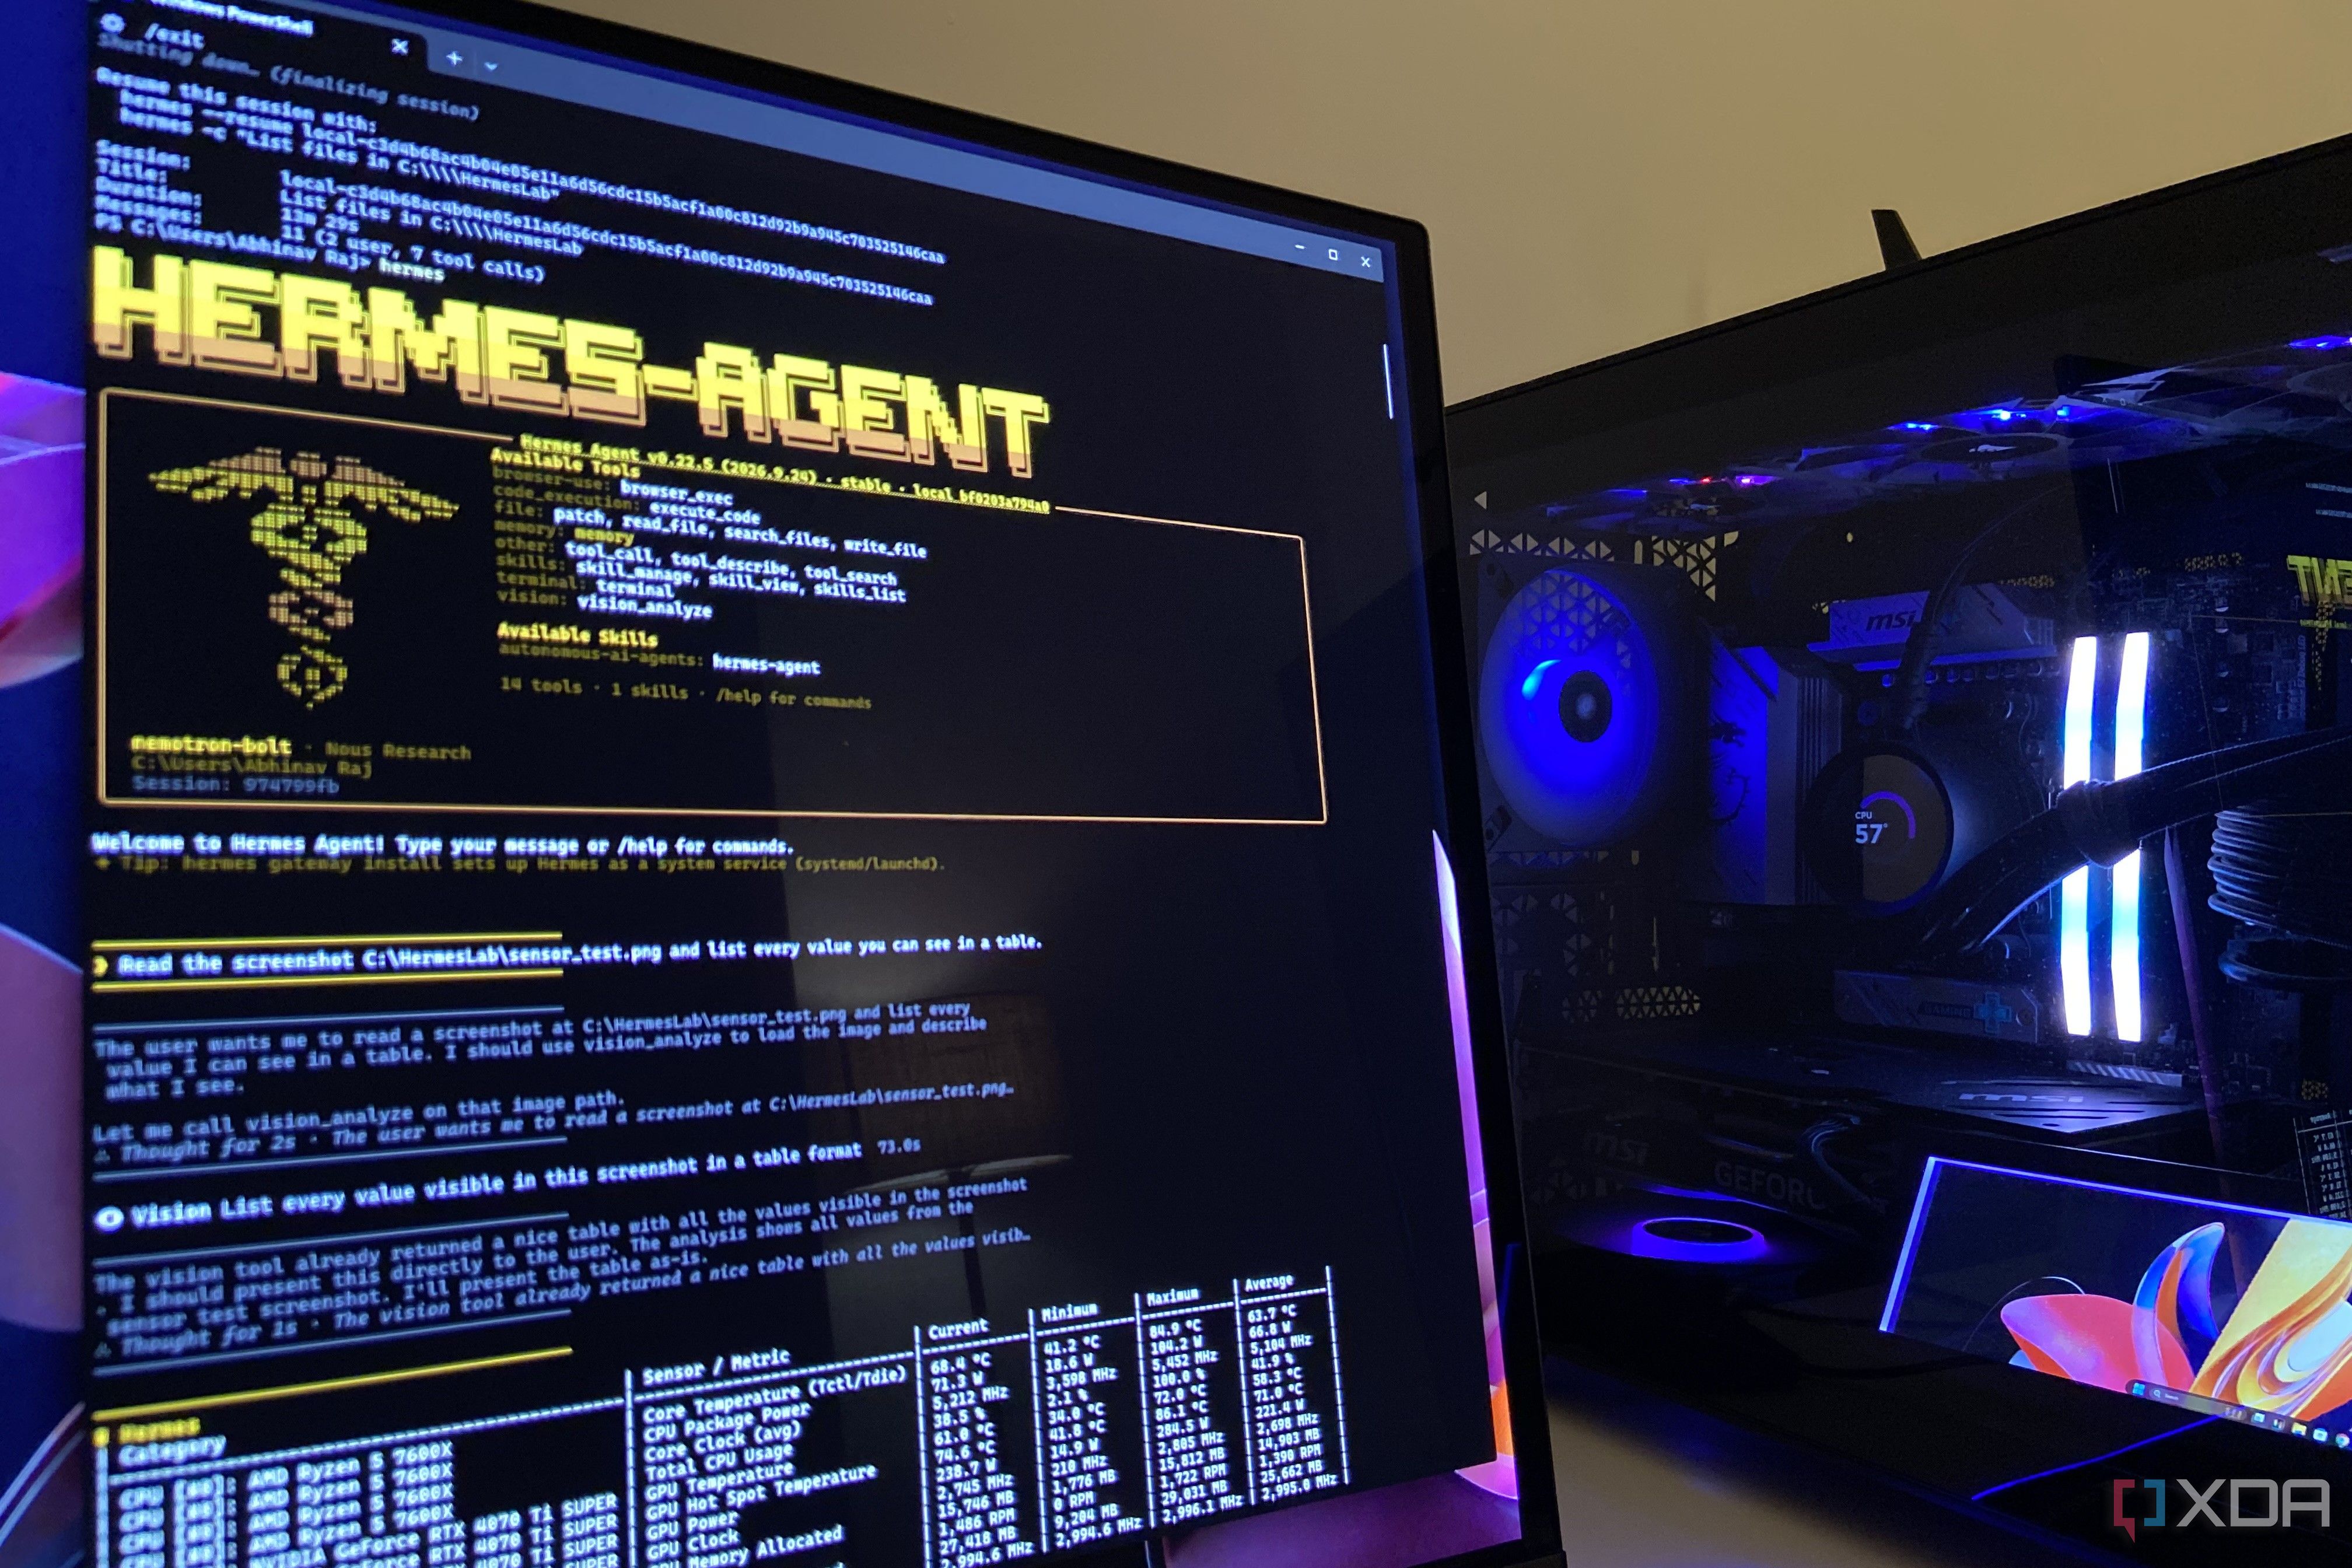
Nvidia's Nemotron 3.5 Bolt AI model has proven to be more capable than initially expected on a 16GB RTX 4070 Ti Super GPU. The 74B model, with 9B active parameters and native 2-bit weights, can run entirely on the 24GB VRAM limit of the GPU. After some adjustments to the llama.cpp build, the model managed to process 19 tokens per second on average, with prompt processing at 110 tokens per second. The inclusion of LiLiCorr slowed things down, so speculative decoding was avoided.
The model's agentic capabilities were demonstrated through Hermes Agent reasoning traces, which were used to create a custom endpoint for llama.cpp. The agent was able to complete a five-step job, including finding installed software versions, checking GitHub for updates, finding a relevant pull request, writing a report, and saving the process as a skill. All of this was accomplished without human intervention, showcasing the potential of Nemotron 3.5 Bolt on a relatively modest GPU setup.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.