6 Lessons From Testing AI Agent Context Compression Across 2,000+ Runs
Does context compression save tokens in AI agents? Data from 2,000+ logged MCP agent runs shows why compression ratios mislead, and what to measure instead
Here are six key lessons from testing AI agent context compression across over 2,000 runs, based on the wire material provided:
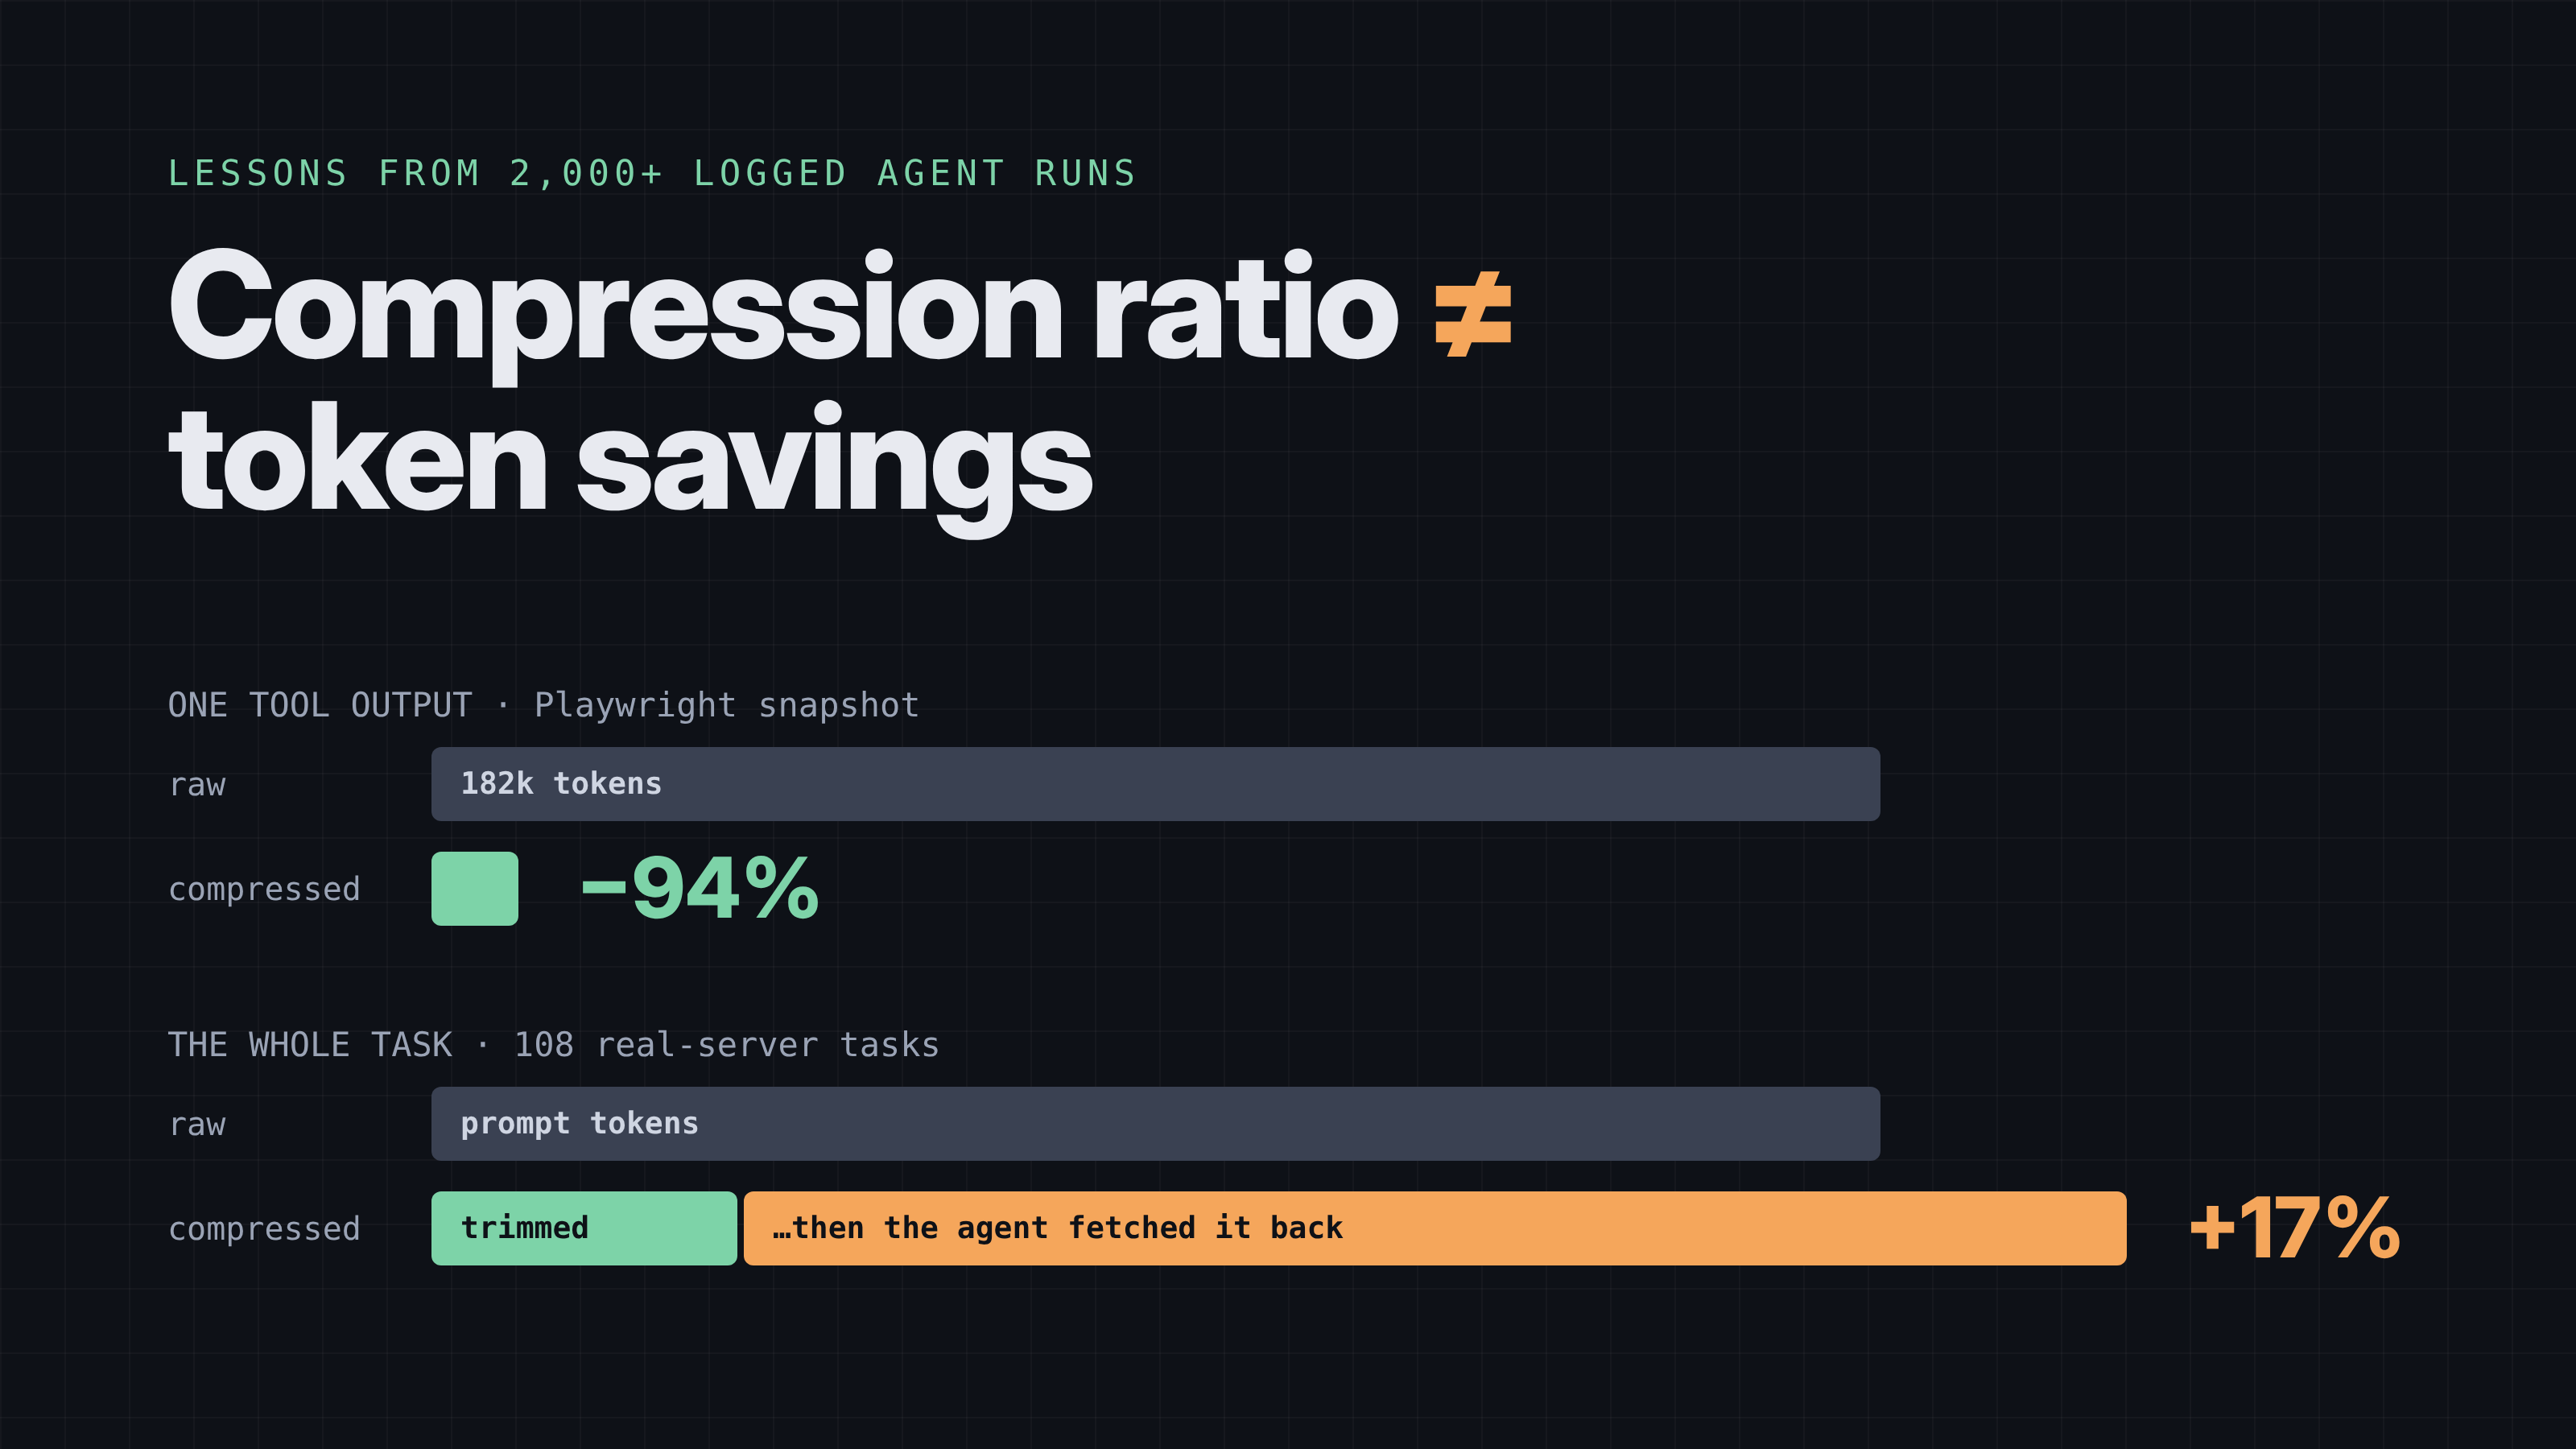
1. The agent fetches the full tool output back after compression. In a test case, a compressed file output of 71,250 tokens still required an additional expansion call to retrieve the full 71,250 tokens when needed. Across 108 real-world tasks, a targeted compression system cost the model an additional 0.3% tokens compared to uncompressed output.
2. Retrieval must be targeted, not all-encompassing. Adding a search mode to allow the model to request only specific lines or sections of a large output eliminated the overhead of re-fetching the entire compressed file in many cases. With targeted retrieval, compression costs were reduced or eliminated in most scenarios.
3. Adding a compression tool can distract smaller models. In a diagnostic run, adding a compression tool to a 4B model's toolset disrupted its performance, causing it to call the tool unnecessarily and reducing its success rate from 50% to 41.7% on standard tasks. Only listed tools that are actually used by the compression system should be made available to the model.
4. Even simple truncation can silently lose critical information. Truncating responses to a fixed length can save tokens, but may result in important data being cut off and lost from the model's knowledge. Evaluating compression methods should consider not just token savings, but also potential information loss that affects the model's ability to answer correctly.
The overall takeaway is that context compression can offer benefits, but the implementation details matter greatly. Targeted retrieval, careful tool addition, and full consideration of what data might be lost are crucial for realizing true savings and maintaining model performance.
Written by urgent.news from HackerNoon's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.