My local LLM kept thinking in circles, and the fix was downloading a different version of the same model
The wrong quantization turned my local LLM into a circular thinker
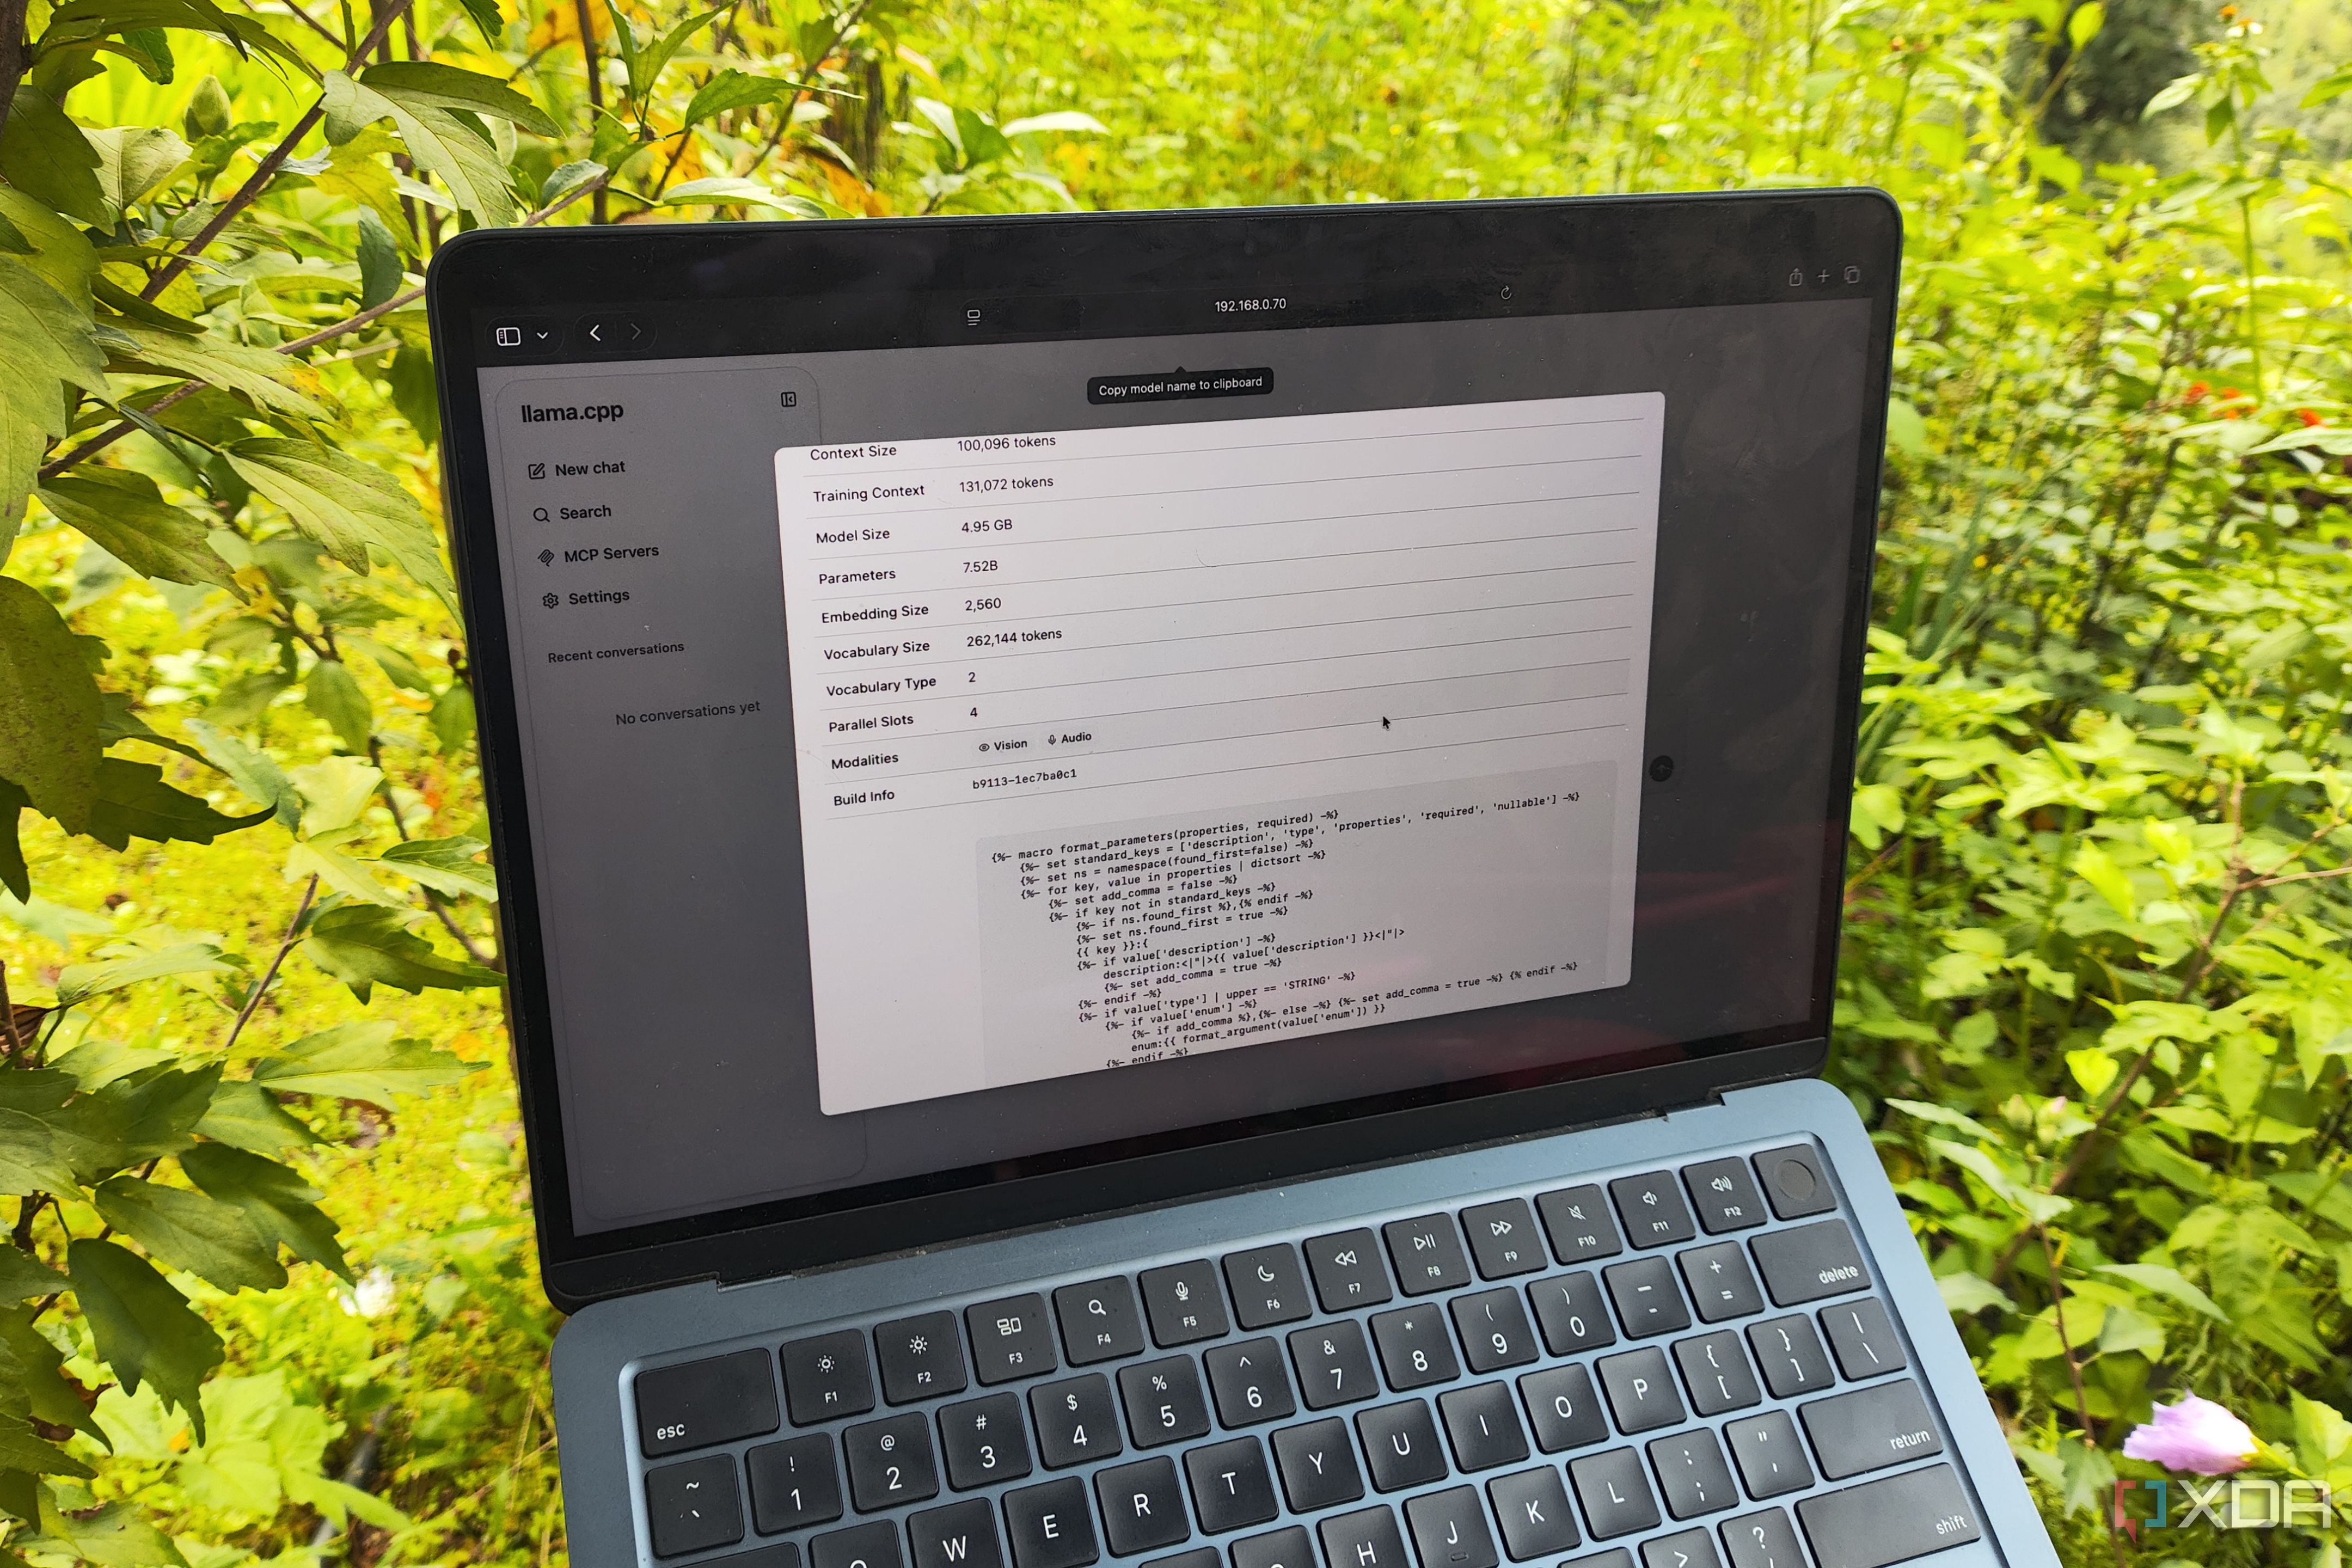
During recent months, I have experimented with various locally-hosted language model setups on budget GPUs, mini-PCs, and Raspberry Pi devices. While optimizing token generation rates without compromising reasoning capabilities has been challenging, sometimes these modifications caused my models to enter endless loops and generate incorrect information.
Among the potential culprits are the wrong quantization settings and chat templates. For example, using Q2 or Q3 quantization for models like Gemma-4-12B can significantly enhance performance, but may lead to reasoning penalties and potential loops. My solution was straightforward: download a different version of the same model with appropriate quantization and template configurations.
Quantized model variants, such as Q2, Q3, or Q4, have lighter VRAM requirements (4.2-4.5GB) compared to the unquantized BF16 variant (26.7GB). However, lower quantization rates might reduce accuracy. When using LLMs for productivity tasks, such as tagging notes or generating coding prompts, selecting the right chat template is crucial.
The chat template formats prompts that the LLM understands, and using the wrong template or mixing templates across different models can drastically lower accuracy. Switching to models with mixture-of-experts (MoE) capabilities has further improved my inference tasks. MoE models use a routing mechanism to activate a small subset of parameters, reducing VRAM usage by offloading inactive parameters to system memory via flags like --n-cpu-moe on llama.cpp.
This approach allows for efficient performance even on lower VRAM-capable GPUs, like my RTX 3080 Ti for Qwen3.6-35B-A3B (Q4_K_M) at 24 tokens/second and my GTX 1080 for Gemma-4-26B-A4B (Q4_K_M) at 14+ tokens/second.
Written by urgent.news from XDA Developers's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.