AMD and Intel will work together to create a single PyTorch code path for AI inference on CPUs
AMD and Intel are working together to bring CPU inference optimizations for PyTorch under the unified oneDNN library.
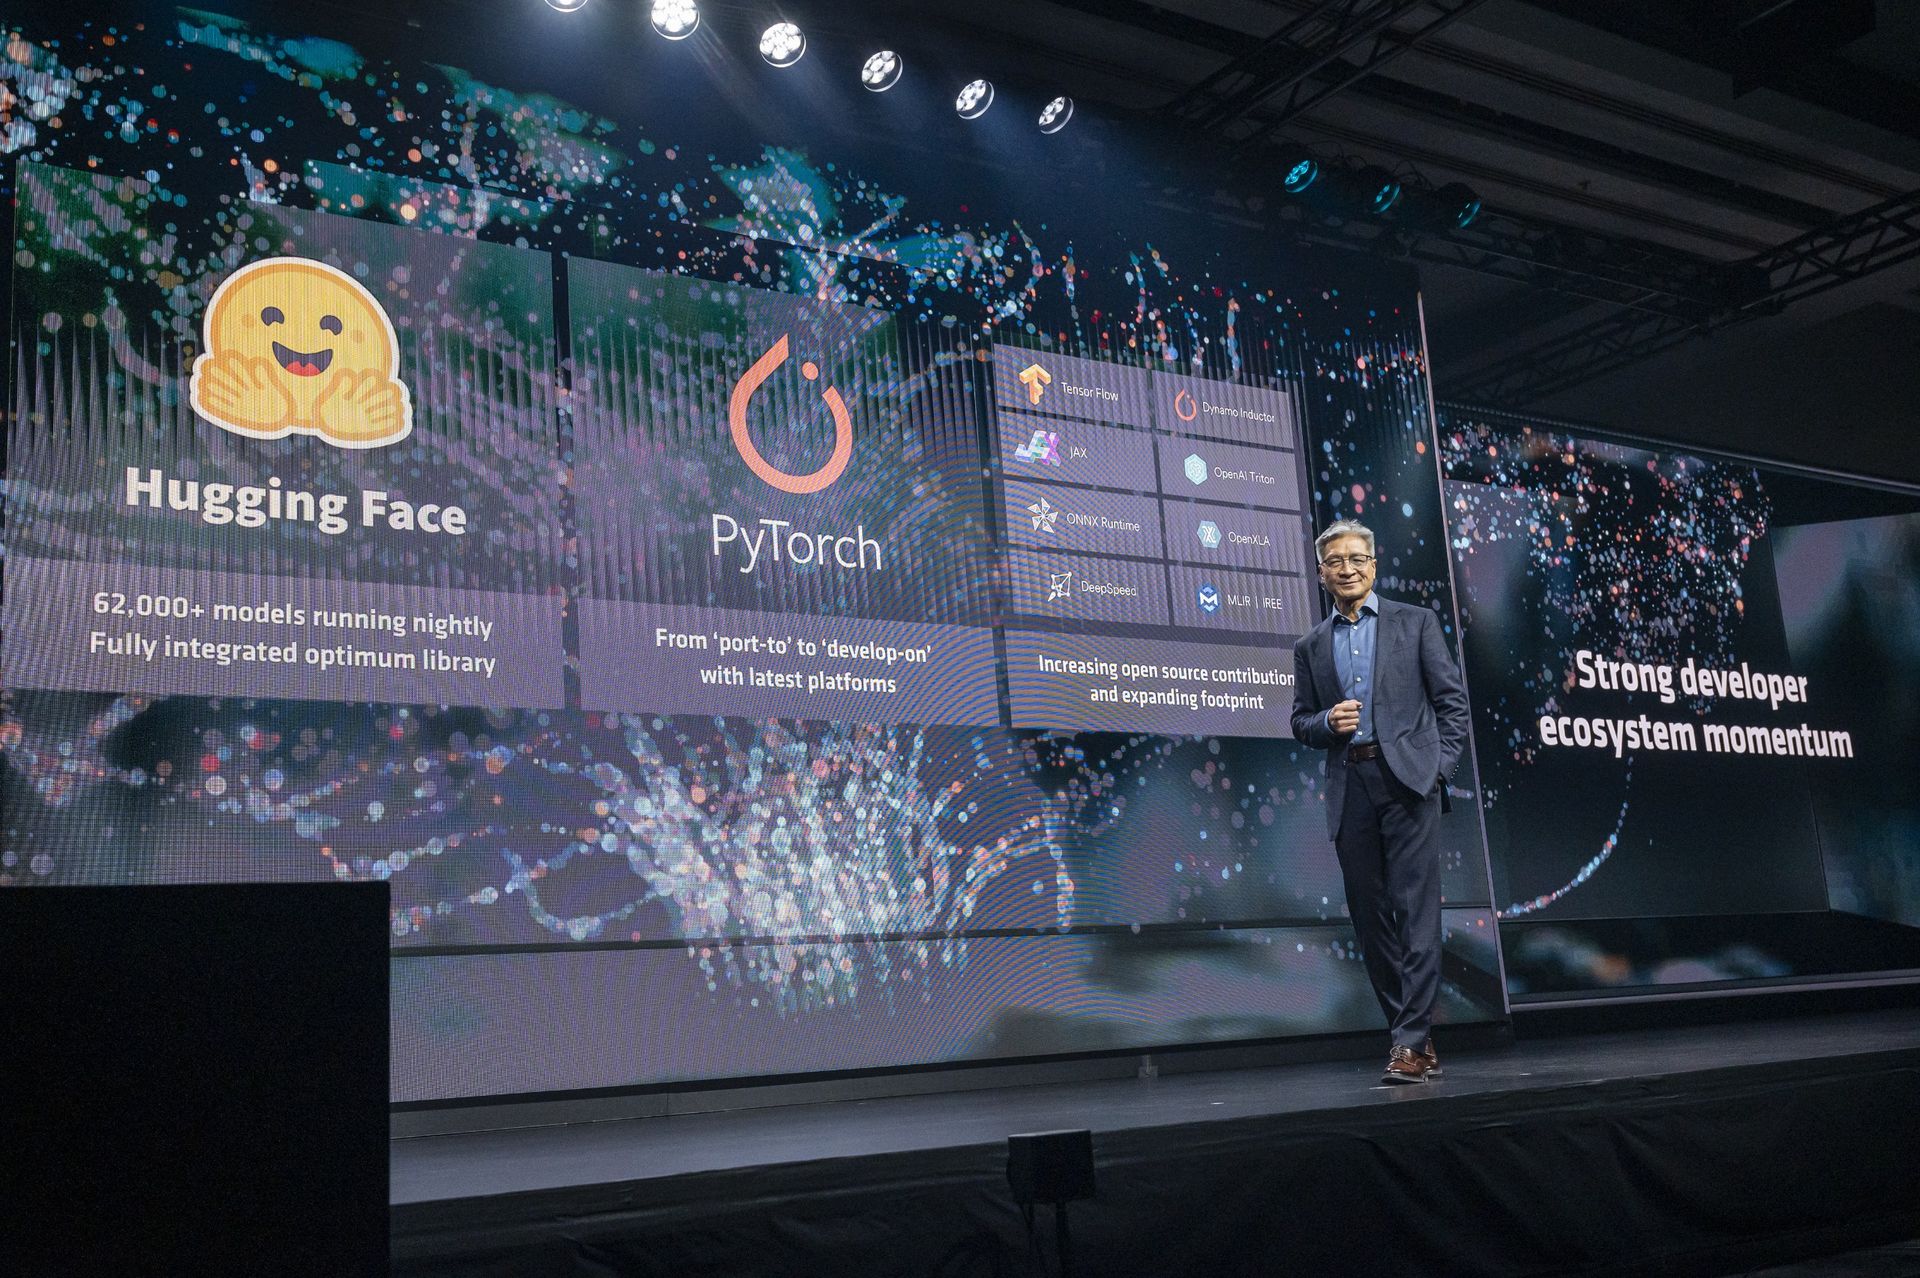
Intel and AMD are collaborating to create a unified PyTorch code path for AI inference on CPUs. The companies have integrated their CPU optimizations into a single library, oneDNN, which will offer tuning for both AMD and Intel chips. AMD has moved its ZenDNN version of oneDNN into the open-source oneDNN, published by the UXL Foundation, and joined the UXL Foundation as a steering member.
This move was recommended by the x86 Ecosystem Advisory Group (EAG), a joint initiative between Intel and AMD. The oneDNN backend is designed to accelerate CPU inference for the latest Intel and AMD chips in frameworks like PyTorch. It automatically detects hardware features at runtime to generate optimized kernels and supports low-precision data types.
This collaboration aims to simplify working with PyTorch across different systems, ensuring a single backend provides the proper optimizations for any hardware. Although the focus is on the x86 platform, oneDNN is a cross-platform library that also works on Arm and RISC-V architectures.
Written by urgent.news from Tom's Hardware's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.