SK hynix showcases next-generation AI memory technologies beyond HBM
SK hynix said Friday that it has showcased its next-generation artificial intelligence (AI) memory technologies aimed at expanding the boundaries of AI infrastructure beyond conventional high-bandwidth memory (HBM). The company presented the technologies at the OCP Global Summit 2026, held in California from Tuesday to Thursday (local time). The summit is an annual conference organized by the…
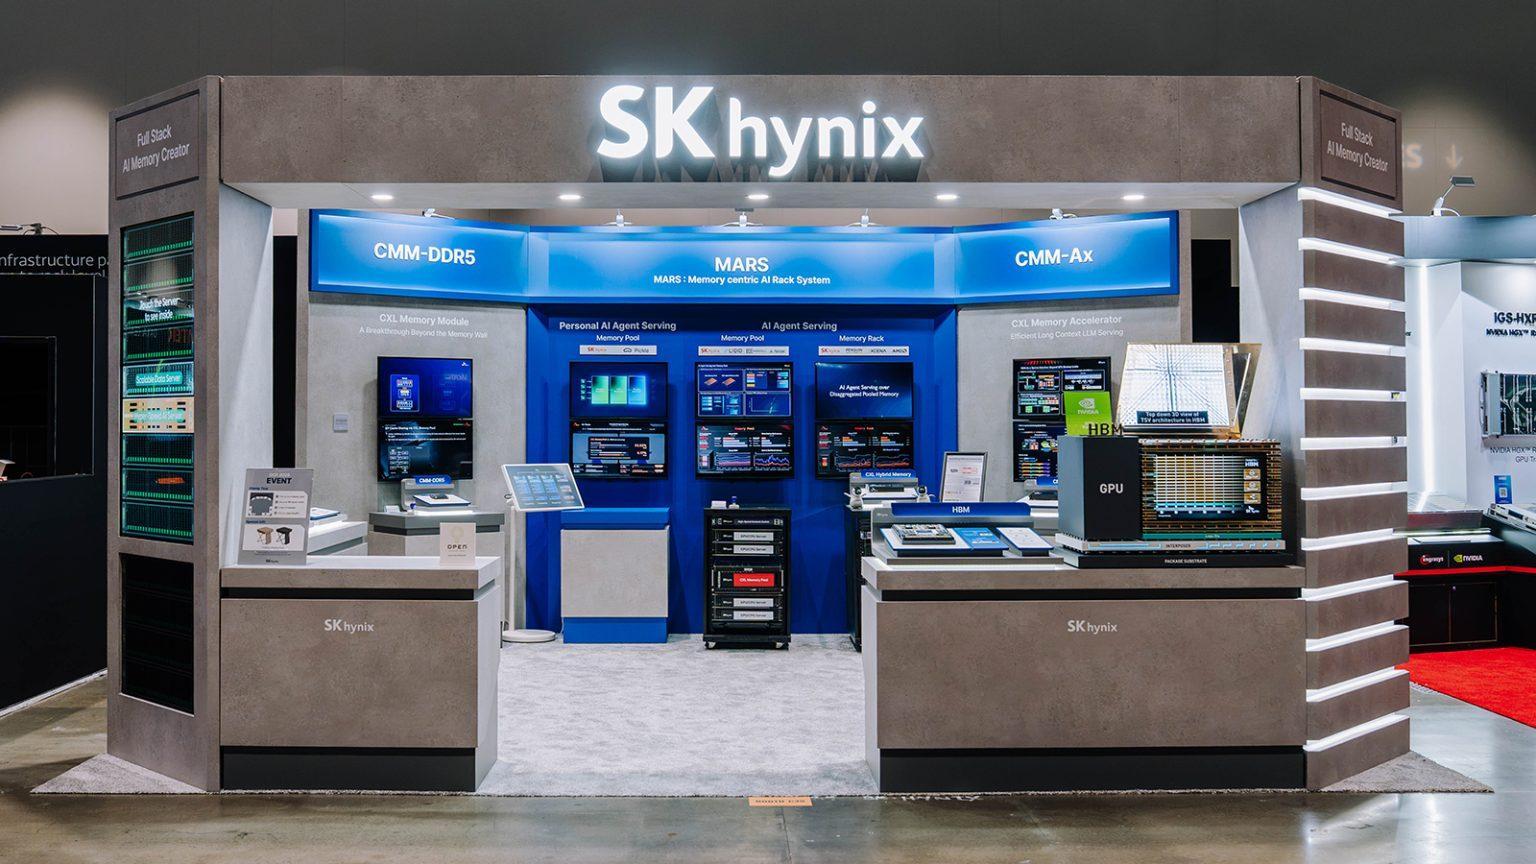
SK hynix has unveiled its next-generation artificial intelligence (AI) memory technologies at the OCP Global Summit 2026 in California, aiming to push the boundaries of AI infrastructure beyond conventional high-bandwidth memory (HBM). The company displayed its flagship products in the front section of its exhibition space, titled the memory section, while the larger rear section, called the system demo section, featured memory solutions designed to support next-generation server ecosystems.
Senior Vice President Kim Ho-sik introduced MARS (Memory-Centric AI Rack-Scale System), a disaggregated rack-scale architecture that aims to coordinate computing and memory resources seamlessly. Additionally, Kim highlighted progress in High Bandwidth Flash (HBF), a technology aimed at addressing industry challenges.
Brief written by urgent.news from The Korea Times's own syndicated text. Machine-written — may contain errors; check the original before relying on it.
This story
This is one outlet's version. Read the fullest account.