Building a Governed Customer 360 Data Product on Microsoft Fabric
Learn how to build an AI-ready Customer 360 data product with Microsoft Fabric, governed data layers, semantic models, and MCP tools.
AI is transforming enterprise data architecture, but the importance of high-quality architecture remains unchanged. Tools like Copilots and agents now consume enterprise data just like human users. However, AI systems require more than just access to data; they need context such as ownership, calculation logic, freshness, lineage, and business rules.
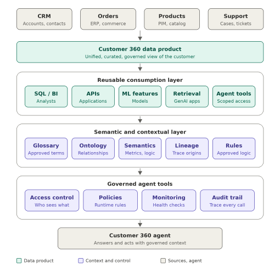
This context is stored in metadata, catalogs, and semantic layers, making the data discoverable and usable by AI. The key to building a governed data product for AI is to create it once and expose it through multiple interfaces, adding explicit business context on top. The architecture consists of several layers: Ingest, Curate, Publish, Consume, and Govern.
Each layer answers specific questions about the trusted product, its consumers, its meaning, and what an agent can touch. Meaning should be established before agent access to ensure accurate results. The architecture built on Microsoft Fabric includes an ingestion pipeline, a catalog and glossary in the context layer, and MCP servers as agent interfaces.
The process involves ingesting data from CRM, order, product, and support systems into OneLake, curating it by deduplicating, standardizing, and validating, publishing it as a governed view with a declared grain, owner, freshness target, and contract, exposing it through various consumption layers, adding context through catalogs, business glossaries, ontologies, and semantic layers, and finally governing and observing the data product for AI governance.
Rewritten by urgent.news; may contain errors — check the original.
Source: hackernoon.com