Urgent.News

What's breaking now, across thousands of outlets.

More in AI

LLM Evaluation Explained: How a Benchmark Produces Comparable Numbers

TL;DR LLM evaluation only becomes useful when every model faces the same prompts, the same fixed judge, and the same per-axis rubrics, with a public verbatim trail so anyone can re-read what a model…

  • LLM evaluation uses identical prompts and scoring to ensure consistency
  • Reverse Engineering benchmark assesses source code reconstruction
  • Nemotron 3 Ultra scores 43.49, GLM 5.2 scores 78.0 in benchmark

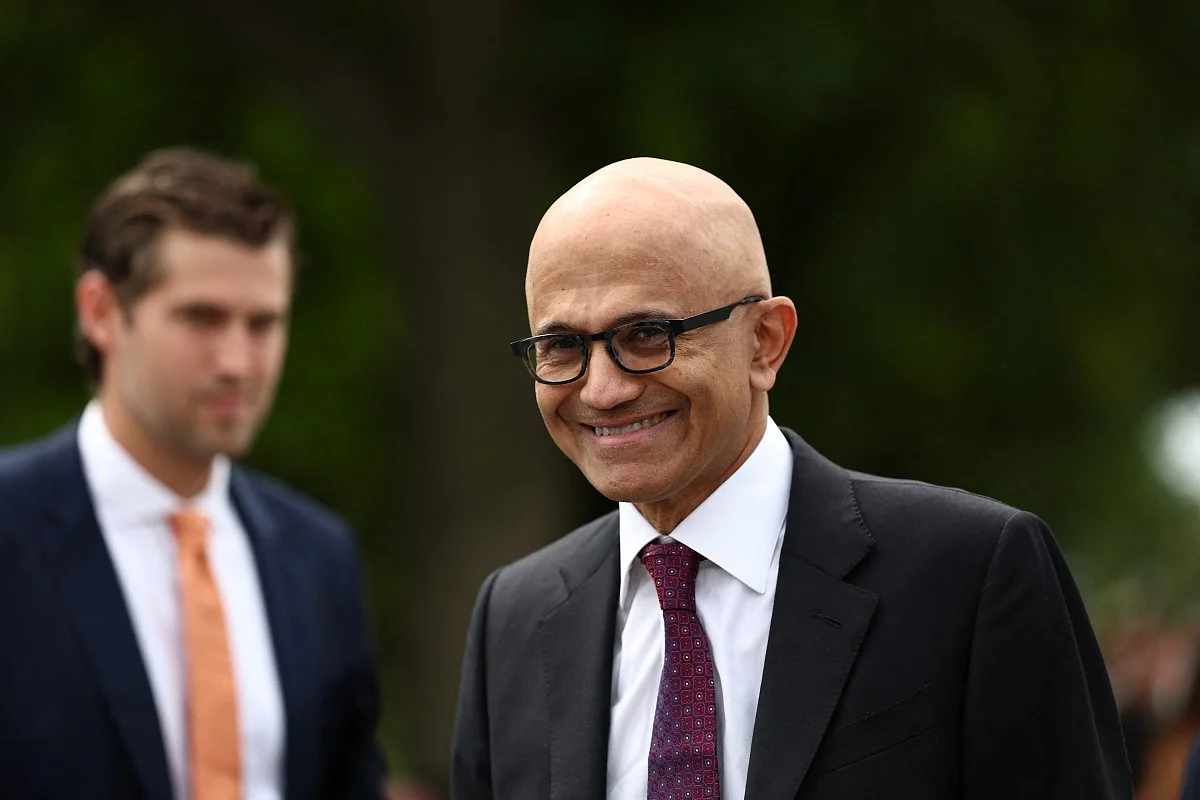
Why does Satya Nadella want humans in charge of an AI emergency brake?

Dubai: Microsoft chief executive Satya Nadella wants every advanced AI system built with an emergency brake that humans control. Nadella outlined the proposal in a post on X on Saturday, October 10, where he said an authorised person must always be able to pause or shut down a model mid-task. The post sets a hard line on trust.

More from Monday 12 October →