Why did my Claude Haiku calls start 400ing? Three AI API changes that break code quietly
I keep a weekly log of where the AI tooling landscape gives way: the release notes that quietly invalidate code people already shipped. Three from the last two weeks, each written as the question a developer is already typing into a search box. 1. "Why did my Claude Haiku calls start 400ing?" Because Haiku 5.5 landed Oct 7 and replaced Haiku 4.5, and code written for 4.5 breaks on it. Anthropic…
Three recent changes in the AI tooling landscape have quietly broken code written for previous versions. The first issue involves Claude Haiku calls returning 400 errors after the release of Haiku 5.5 on October 7. The code written for the previous 4.5 version no longer works due to changes in parameters such as "thinking", budget tokens, and the removal of default temperature, top_p, and top_k.
Developers need to update their code to use the new "adaptive" parameter, set depth with output_config.effort, and adjust their budget tokens accordingly.
Secondly, web_fetch calls from agents have started returning url_not_allowed errors due to changes in what constitutes limited networking. The allowed_hosts parameter now gates web_search and web_fetch, instead of just the sandbox. Fetching from a host not included in allowed_hosts will result in a url_not_allowed error, while web_search will now silently omit results from such hosts.
To resolve this issue, developers must list every host their agent fetches, add them to allowed_hosts (using * to denote subdomains), and recreate the session to ensure the config validates.
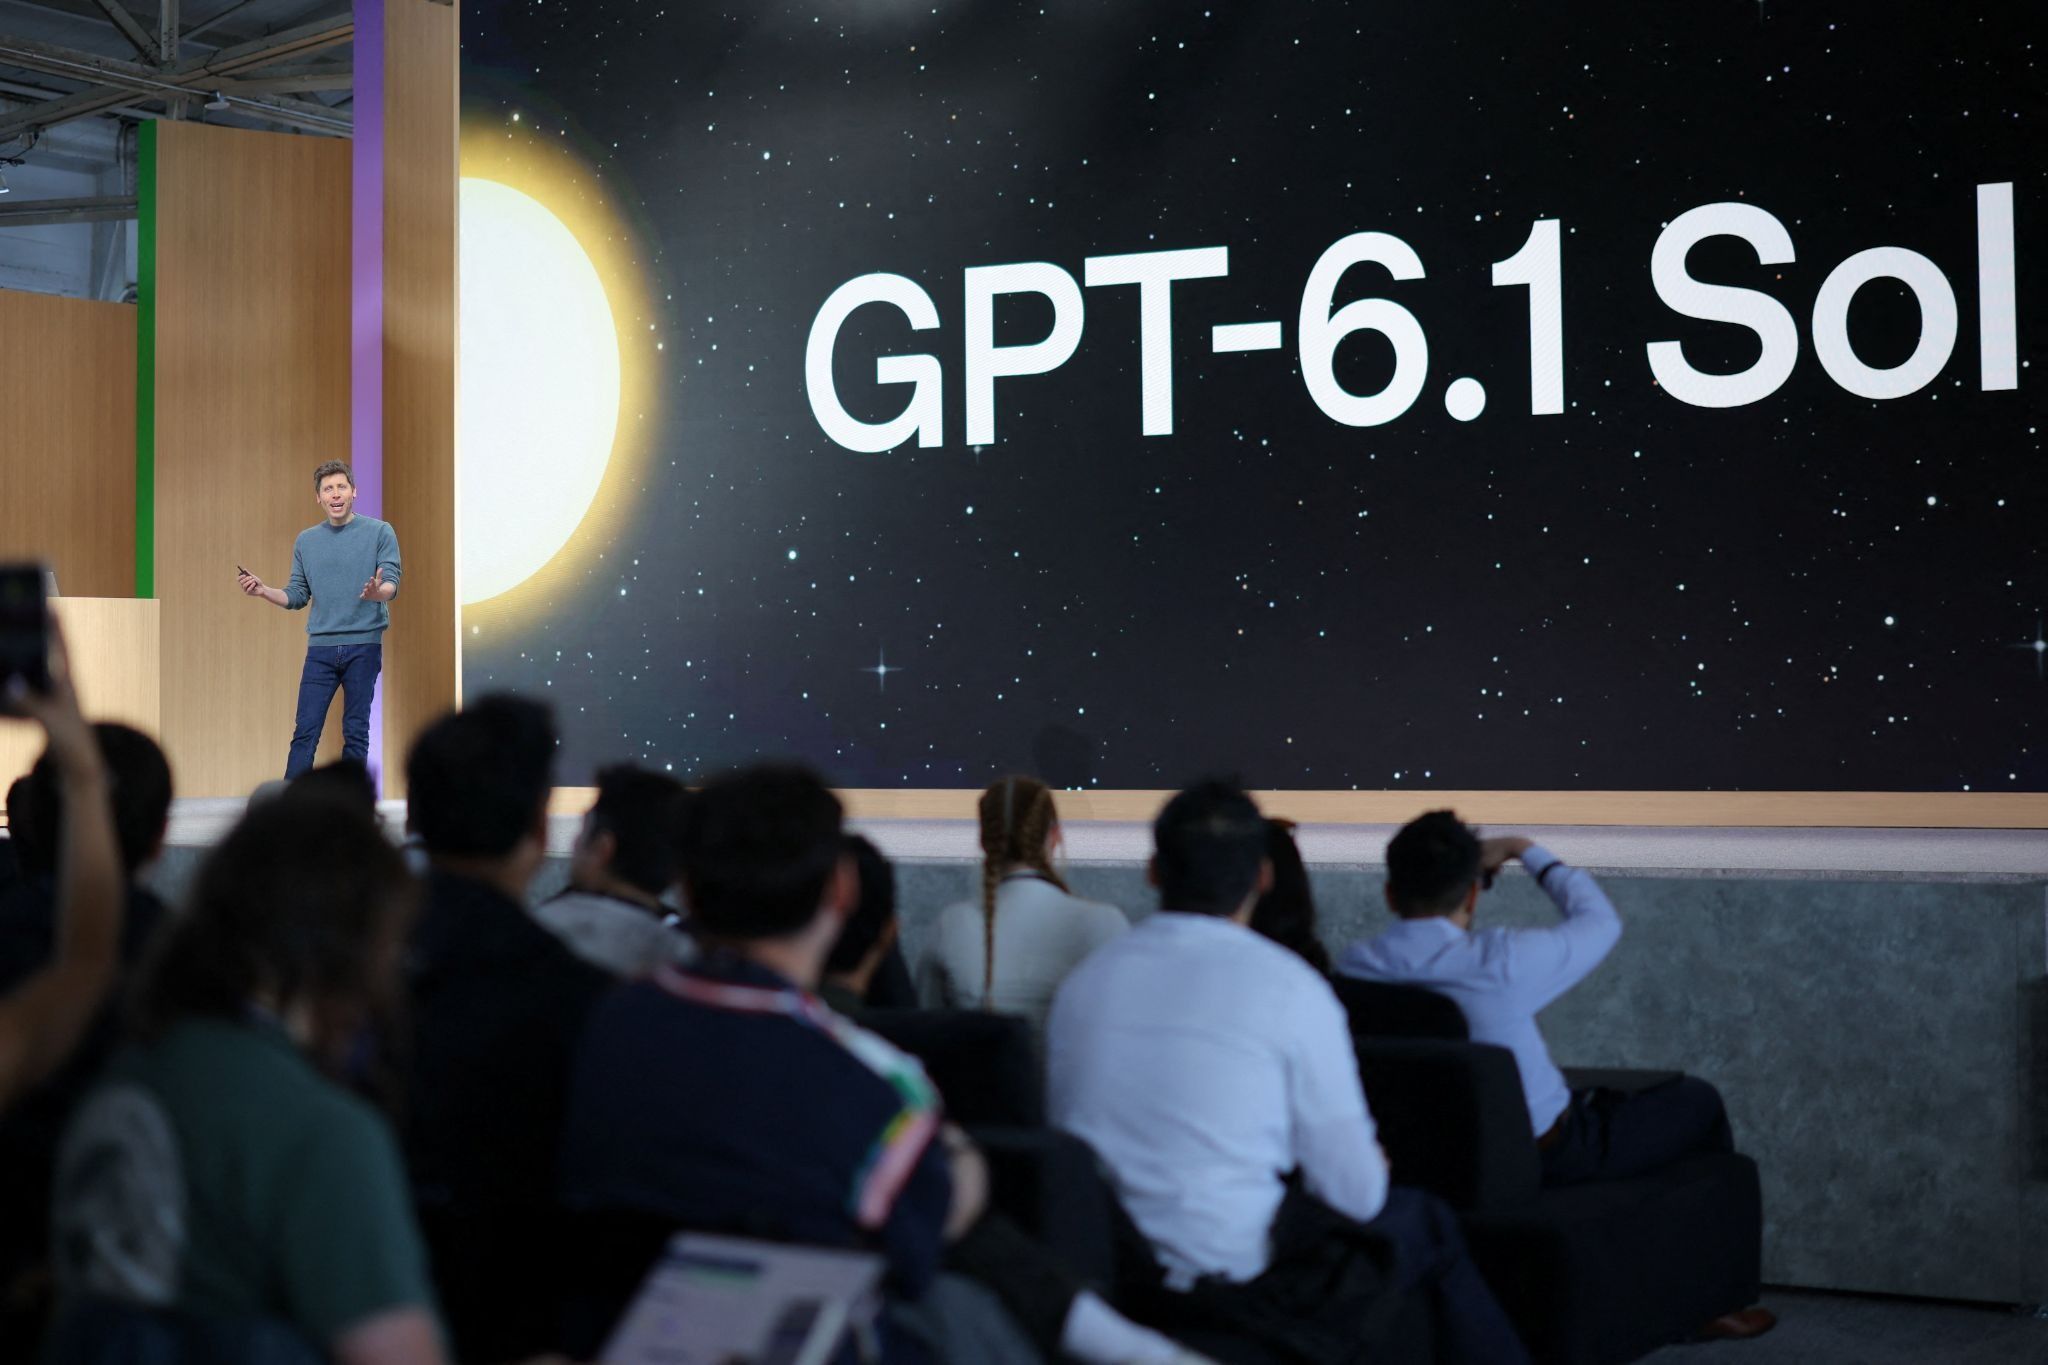
Lastly, GPT-6 model availability has changed. Depending on the user's plan, they may be getting either GPT-6 Luna ($0.10 per million tokens), GPT-6 Sol ($2 per million tokens), or GPT-6 Astra ($10 per million tokens). Work and Codex users will continue to use their existing models. This change brings a 100x price spread between Luna and Sol models. Developers should stop measuring GPT-6 as a single model and pin the exact model per surface, checking which tier each plan routes to before comparing results.
Written by urgent.news from Dev.to's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.
This story
This is one outlet's version. Read the fullest account.