CoreWeave targets AI inference bottlenecks with full-stack optimization
AI inference is fast becoming the workload that decides the economics of the AI boom. Training built the first wave of GPU clouds, but serving models faster and cheaper will define the next. That shift is pushing specialized cloud providers beyond raw GPU capacity into storage, networking and software. One provider is layering managed services […] The post CoreWeave targets AI inference…
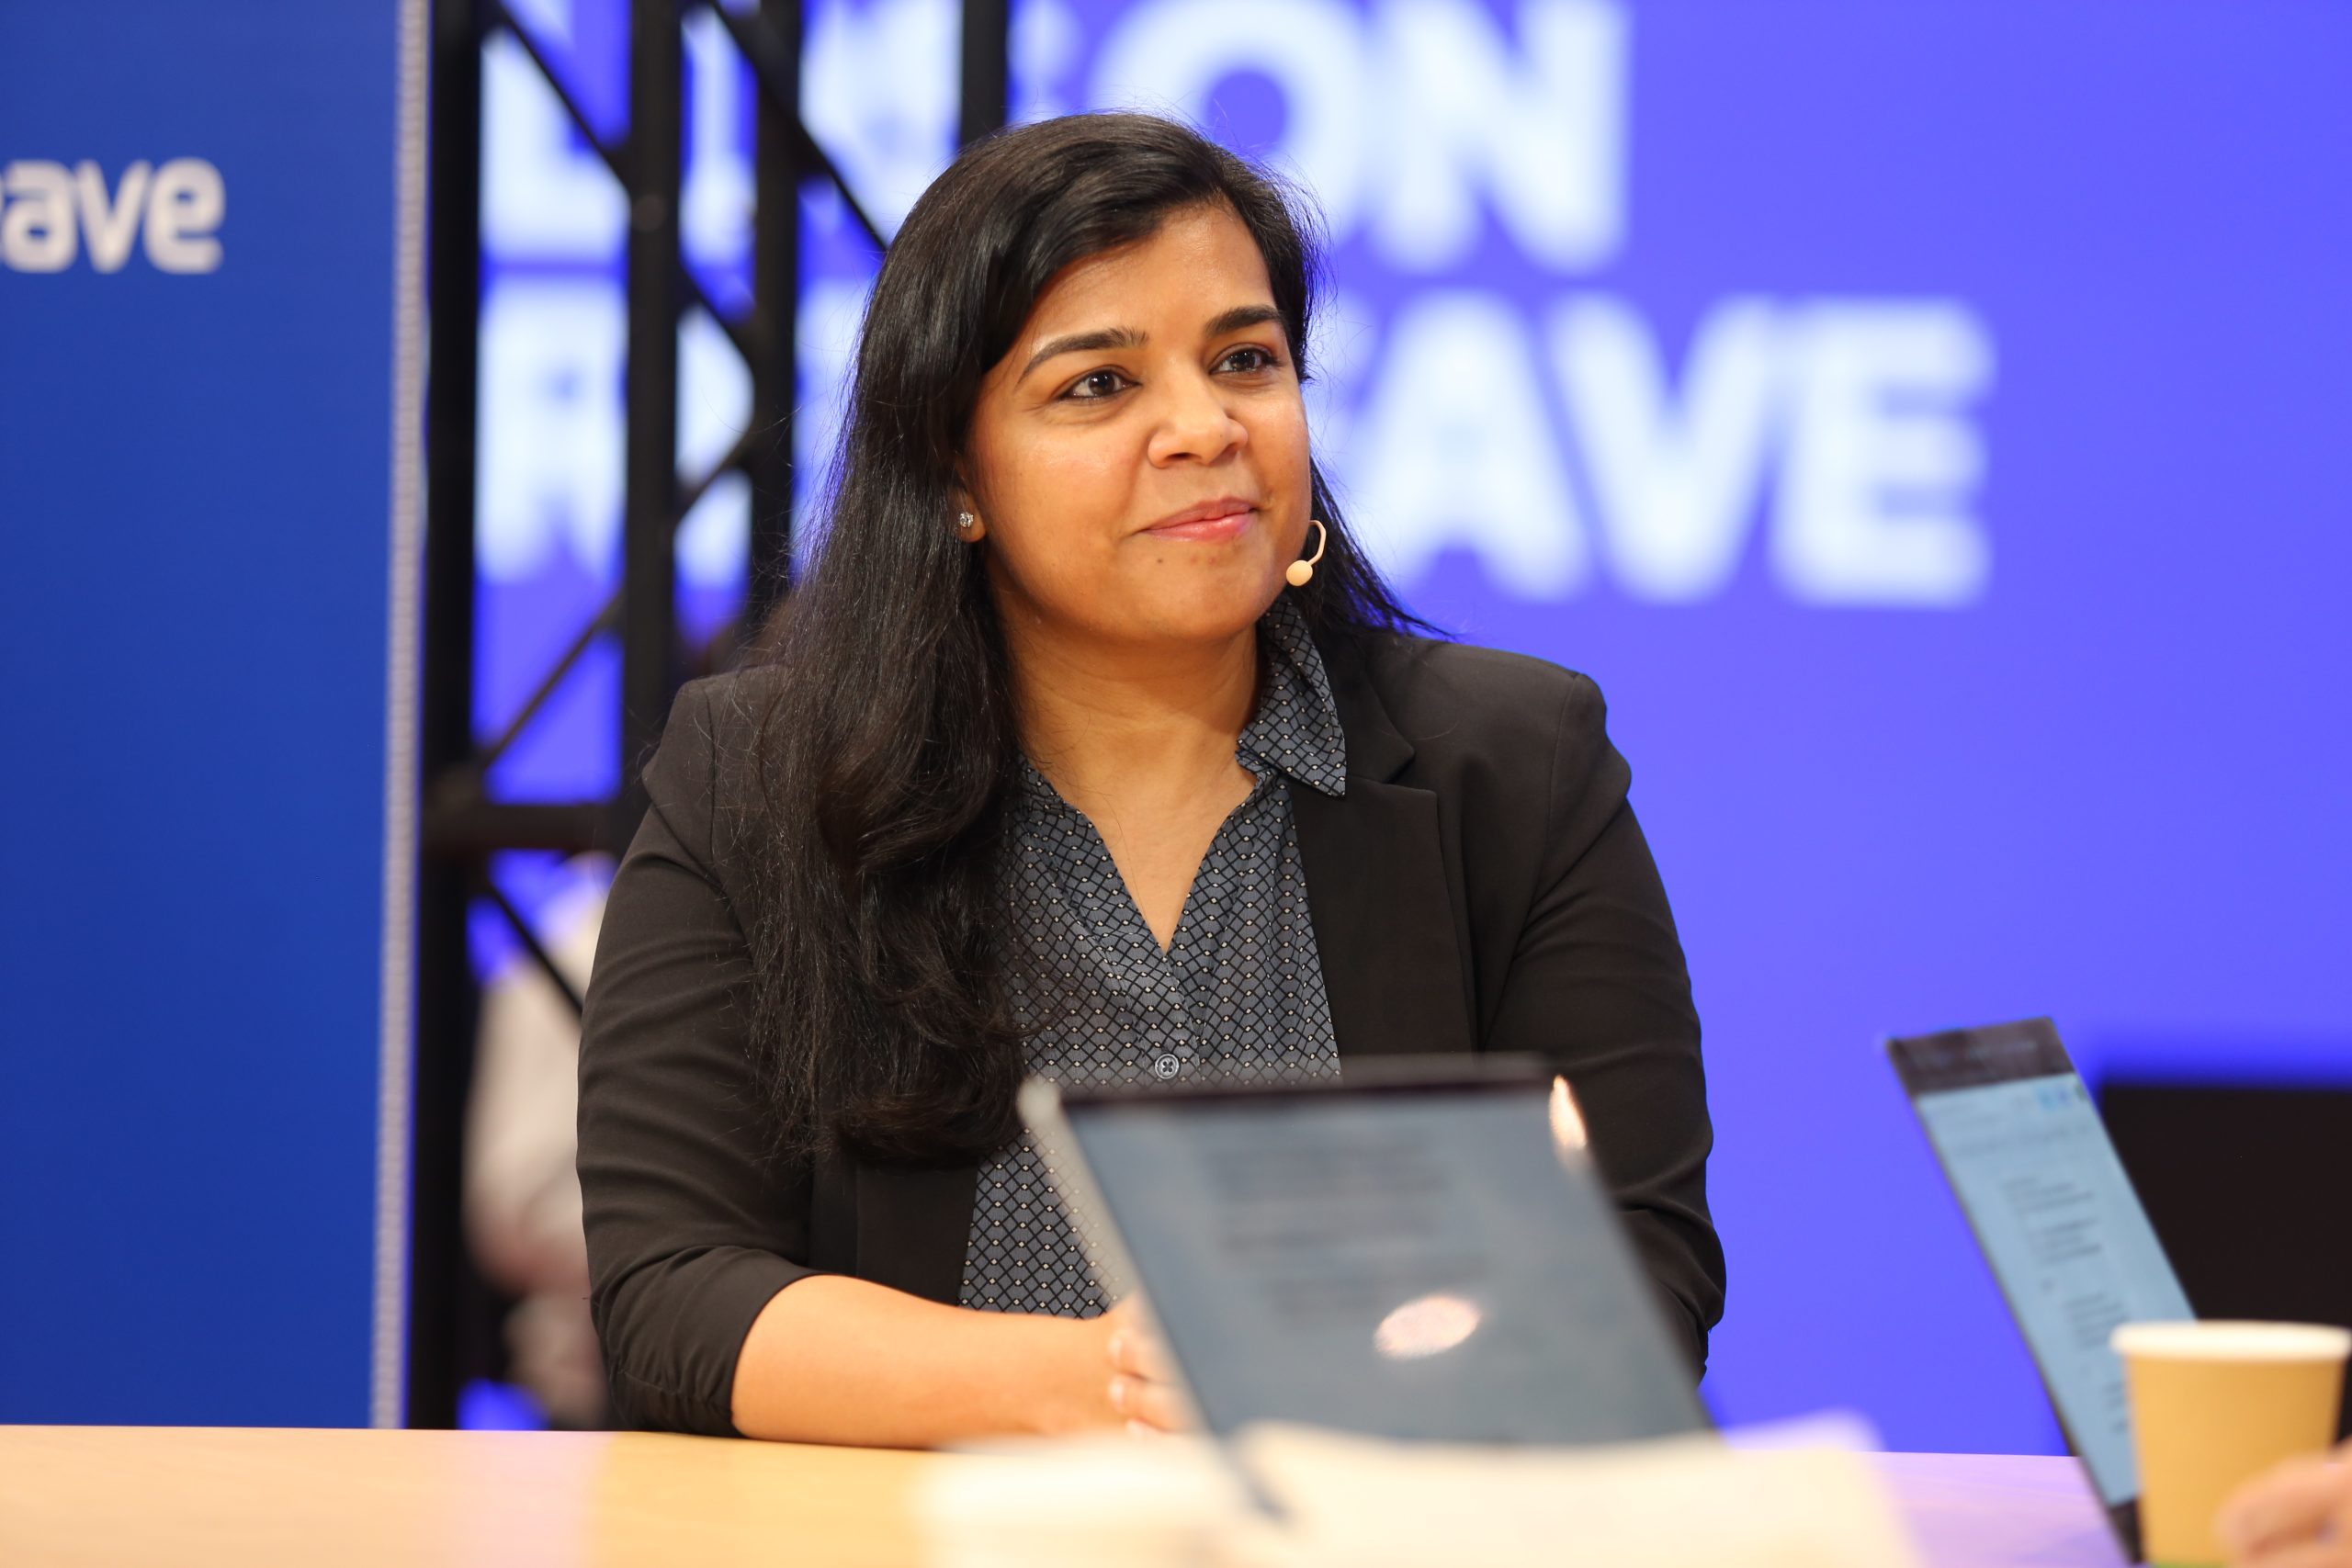
CoreWeave Inc. aims to streamline AI inference bottlenecks through full-stack optimization, according to Urvashi Chowdhary, vice president of product and AI services at the company. AI inference is becoming a critical factor in the economics of the AI boom, prompting specialized cloud providers to focus on storage, networking and software beyond raw GPU capacity.
Chowdhary emphasized the importance of building managed services for training, post-training and inference layers atop reliable infrastructure to enhance performance and cost-effectiveness.
During an exclusive broadcast at the Fully Connected event, Chowdhary discussed CoreWeave's RL Rollouts, a new capability designed to accelerate agentic model iteration. The company's focus on optimizing each layer above the hardware, including the vLLM engine, quantized models and custom speculative decoders, has been pivotal in addressing inference demand. A survey of CoreWeave customers revealed that inference workload share surged from around 10% to 40% in just two years, with a projected 50% share within a year.
CoreWeave's approach involves leveraging open-source tools and contributing back to open systems to provide customers with flexibility. Additionally, the firm integrates reinforcement learning (RL) capabilities into its inference setup to handle the bottlenecks caused by training agentic models with rewards and verifiers. CoreWeave RL Rollouts, built on Nvidia's Dynamo framework, loads new checkpoints into live deployments, reducing model reload latency by 15 times compared to a baseline configuration.
This capability allows for independent scaling of training and inference, speeding up the rollout process.
These advancements are now consolidated within CoreWeave Forge, a platform launched at the event, which connects serving, observability, post-training, and evaluation services. Forge is offered free to start, with paid tiers providing additional features, making AI development tools and services accessible to individual developers. Chowdhary highlighted the company's commitment to making top-notch AI solutions accessible to all, ensuring users receive optimal performance and reliability without compromising.
Written by urgent.news from SiliconANGLE's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.