Can Jev be Your Q or Policy in Reinforcement Learning?
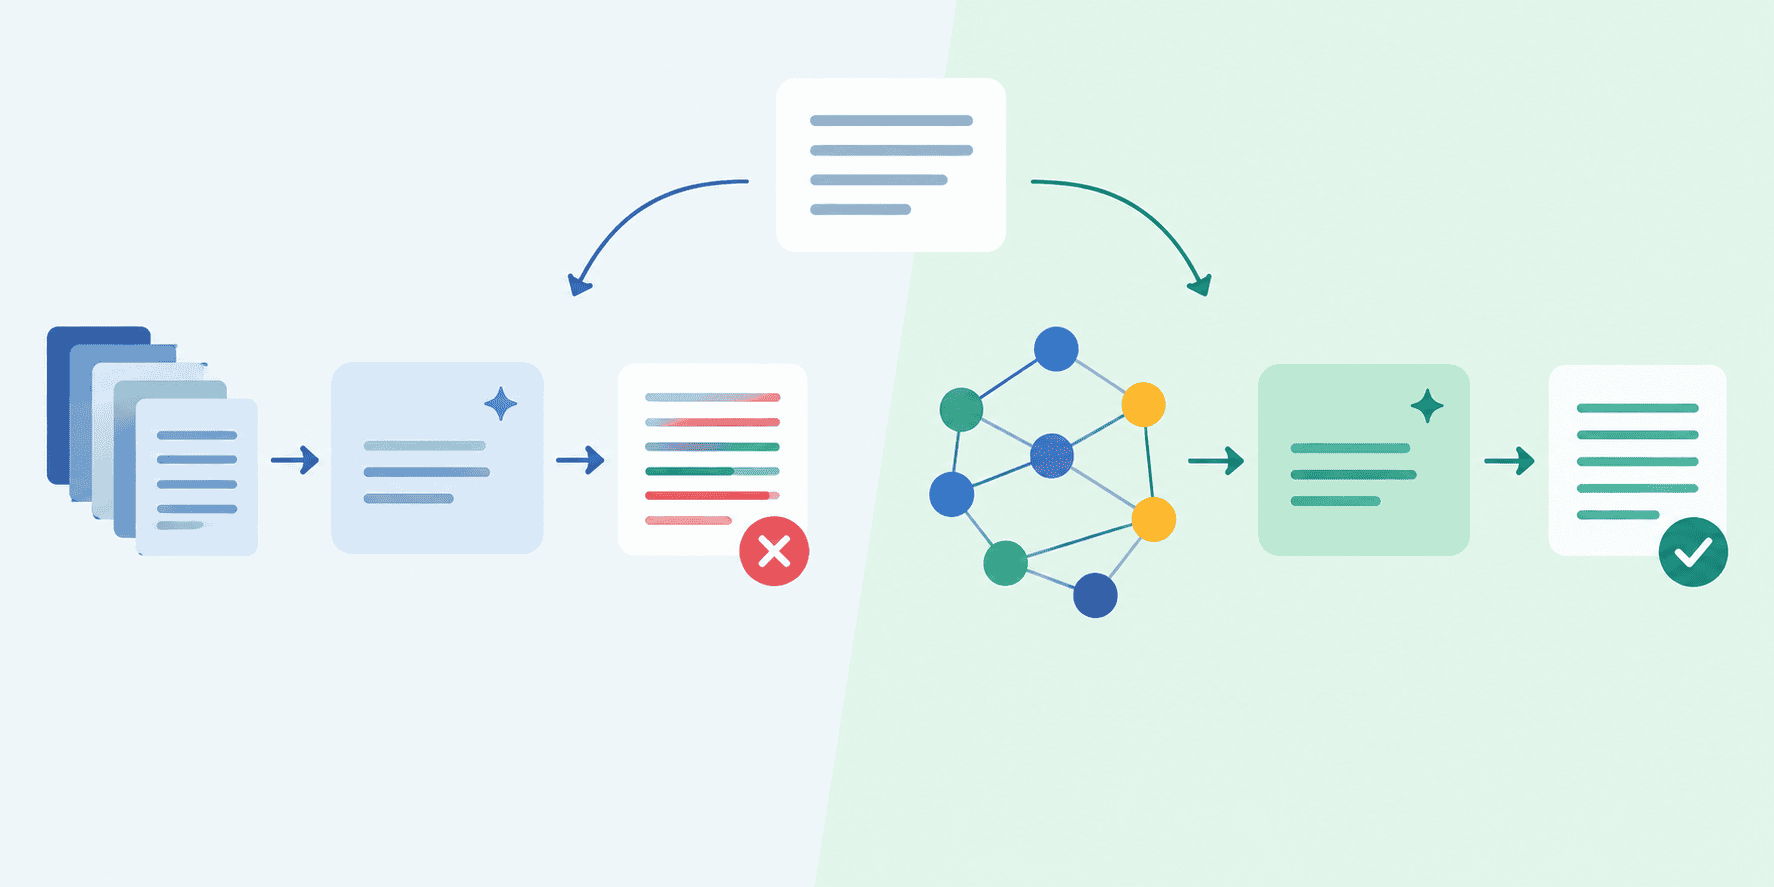
Foundation models supply reinforcement learning (RL) with priors that mitigate its longstanding weaknesses in sample efficiency and transfer, but their token-by-token generation makes queries sequential and costly. Jev, a recently released decision model, generates nothing and returns calibrated, typed answers in a single forward pass. Existing work studies foundation models in RL either as…
We haven't written up this one. arXiv cs.AI has the full story — the link below goes straight to it.
Source: arxiv.org