Nvidia ties AI factory economics to tokens and power efficiency
AI factory economics increasingly depend on more than access to high-performance graphics processing units. As agentic systems draw on multiple models, databases and tools, the entire data center must work as one computing system. That transition is shifting attention from individual chips to the infrastructure that turns computing capacity into useful intelligence. Networking, storage,…
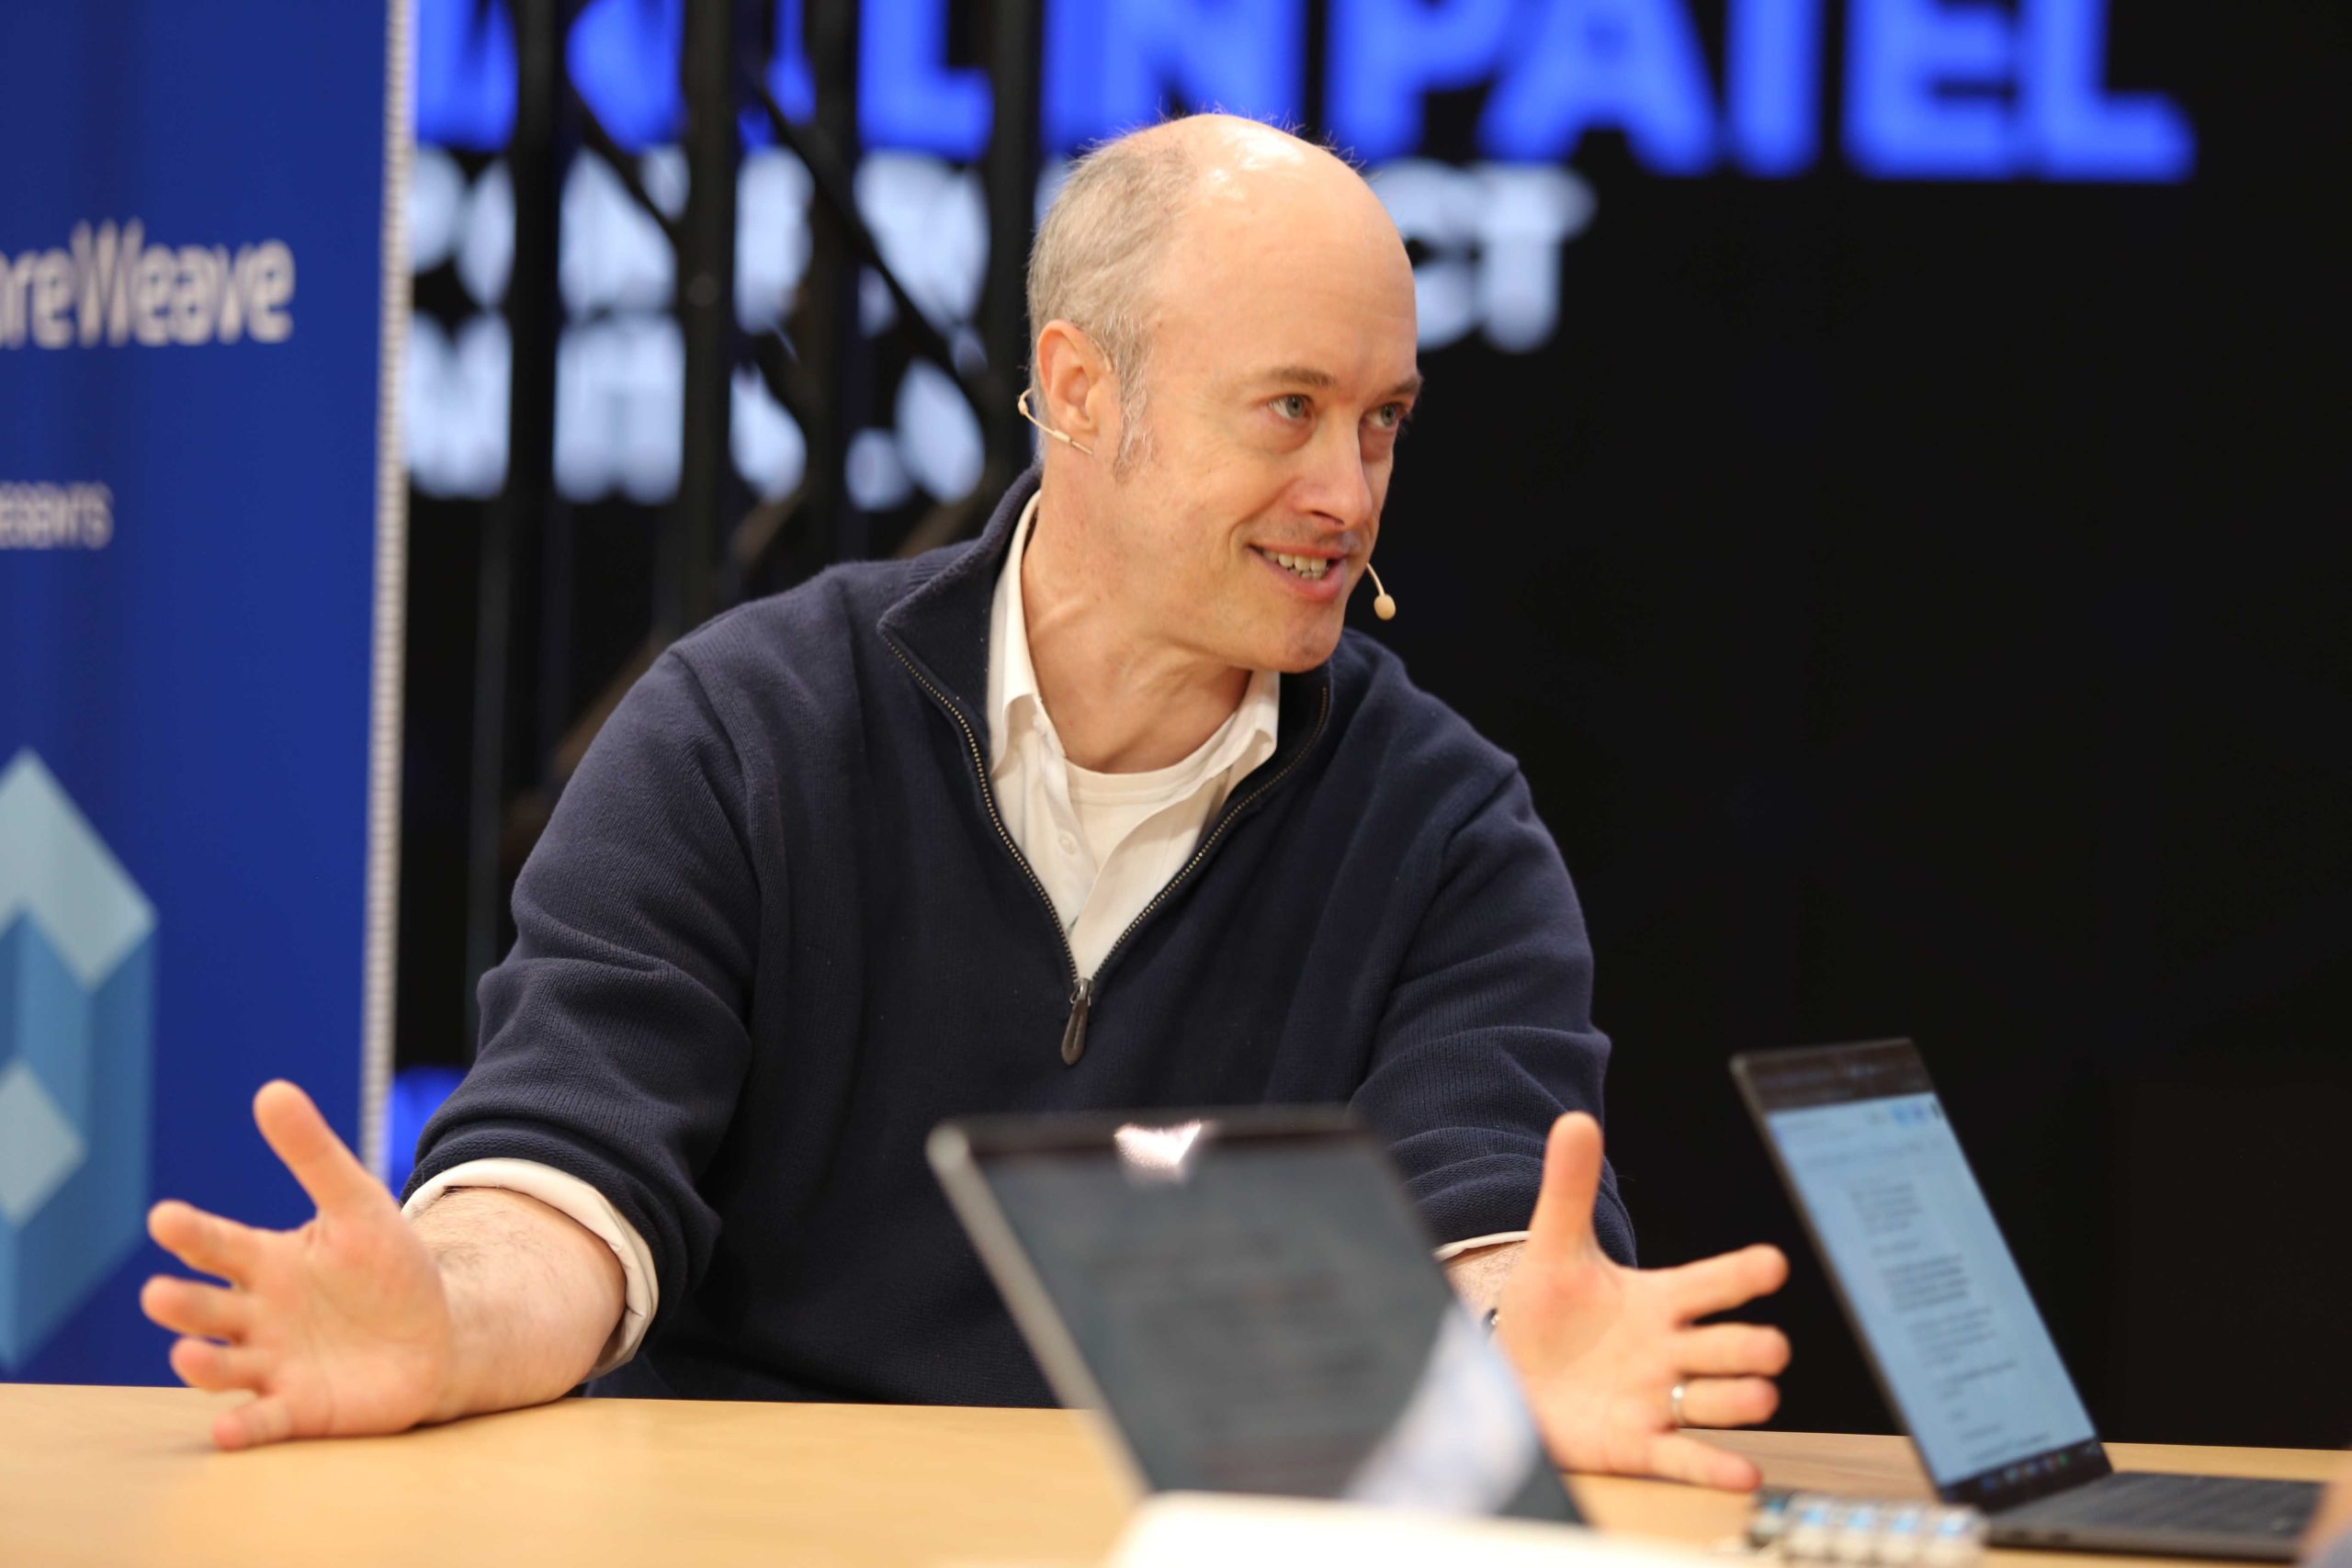
Nvidia has shifted focus from individual graphics processing units (GPUs) to data center infrastructure that maximizes computing capacity while minimizing power consumption, according to Ian Buck, vice president and general manager of hyperscale and high-performance computing (HPC) at Nvidia. Buck explained that as agentic systems leverage multiple models, databases, and tools, the entire data center must function as a single computing unit.
Instead of traditional metrics like cars or devices, the key performance indicators are tokens, which are revenue-generating, durable, and productive assets. An AI factory's commercial output stems from inference, where deployed models process requests and generate tokens. However, inference does not replace training, as organizations continuously update deployed models based on evolving data and market conditions.
This continuous refinement constitutes a form of training, with reinforcement learning and online alignment being areas of active work. Low-latency workloads, which require faster reasoning, represent another economic tier, with Nvidia's Groq 3 LPX inference accelerator enhancing token generation rates for time-sensitive tasks when paired with its Vera Rubin platform.
Power constraints at the data center level dictate the scale of computing infrastructure, making tokens per watt a crucial metric for AI factory economics. Nvidia has consistently improved performance with each GPU generation, achieving significant efficiency gains, such as a 30x improvement in tokens per watt with the Blackwell architecture.
This shift in focus also alters how systems are designed and operated, with solutions like CoreWeave offering customers pre-configured or higher-level inference services to navigate the myriad options available.
Written by urgent.news from SiliconANGLE's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.