Nikkitha Shanker: From 3 years of UPSC prep to building a $2 million business
Nikkitha Shanker spent three years preparing for the UPSC Civil Services Examination before a startup experience redirected her career towards entrepreneurship. She founded Shoppre, which grew into a profitable e-commerce technology business generating about $2 million annually. Shanker later stepped away from the company to pursue AI, spending nearly a year experimenting before co-founding…
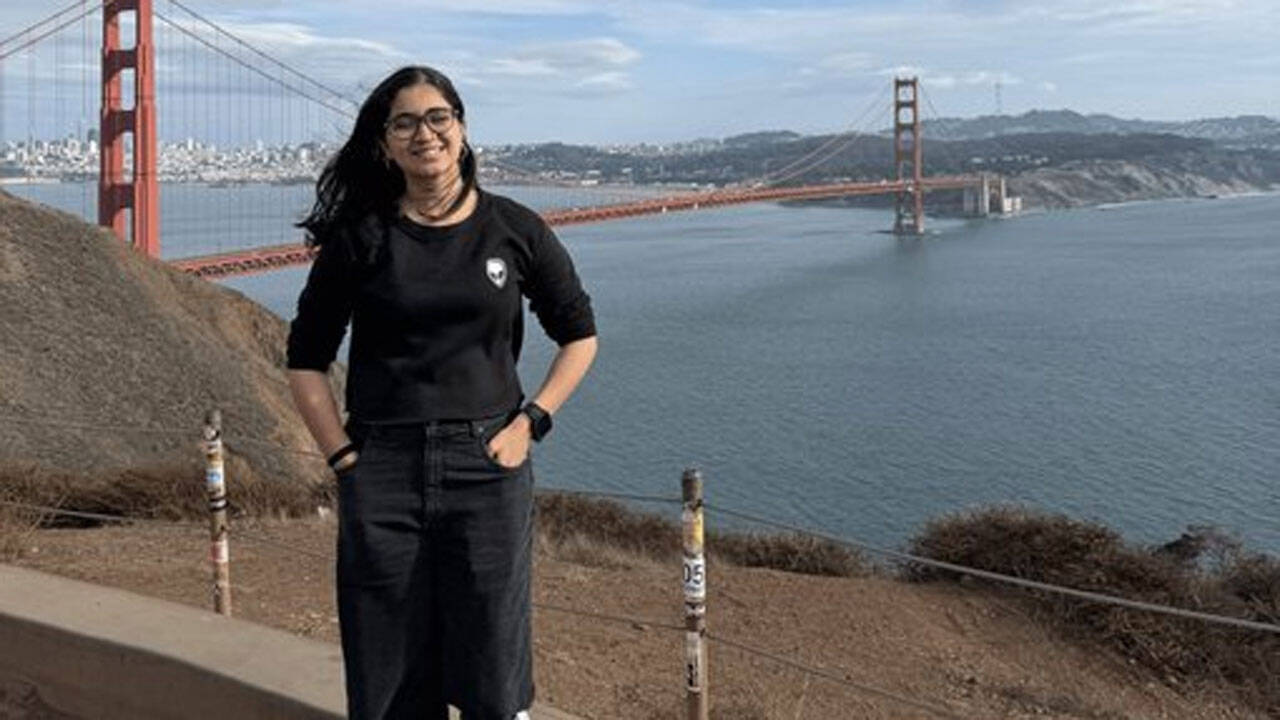
Nikkitha Shanker, born in Kerala and raised in the Middle East, initially planned to enter the civil services. She spent three years preparing for the UPSC Civil Services Examination. However, after failing to clear the examination, Shanker found herself drawn to the world of startups and technology. This shift in career direction led her to co-found SuperBryn, an AI startup focused on enhancing the reliability of voice agents.
SuperBryn has secured $1.2 million in funding from Kalaari Capital and angel investors, according to Shanker's account. Before embarking on this new venture, Shanker had built an e-commerce technology company that grew to an annual revenue of around $2 million and achieved profitability. After deciding to pursue artificial intelligence, Shanker stepped away from the day-to-day operations of her previous business, allowing her team to run it independently.
Today, Shanker balances her responsibilities between Bengaluru and San Francisco while leading SuperBryn.
Written by urgent.news from Times of India's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.