How to Validate Financial Machine Learning Beyond Accuracy and Backtests
Why accuracy and strong backtests can mislead in financial ML—and why reproducibility, leakage-safe validation, and economic evidence matter.
When evaluating financial machine learning models, accuracy and backtests are insufficient. These metrics may indicate a model's statistical performance but do not guarantee economic value or robustness. A model may appear highly accurate in backtests while failing to generate economically meaningful decisions or produce distinguishable results even with similar out-of-sample prediction errors.
The first validation problem is to determine whether a model's predictions have economic value. It is not enough for a model to simply predict outcomes accurately; the model must also produce decisions that have economic significance. For instance, a model might predict market direction correctly more often than another model. However, if the correct predictions happen before tiny price movements and incorrect predictions before large ones, the economic value of the model could be poor.
Similarly, a model with modest predictive accuracy may still have economic value if it is particularly useful when the magnitude or asymmetry of opportunities matters.
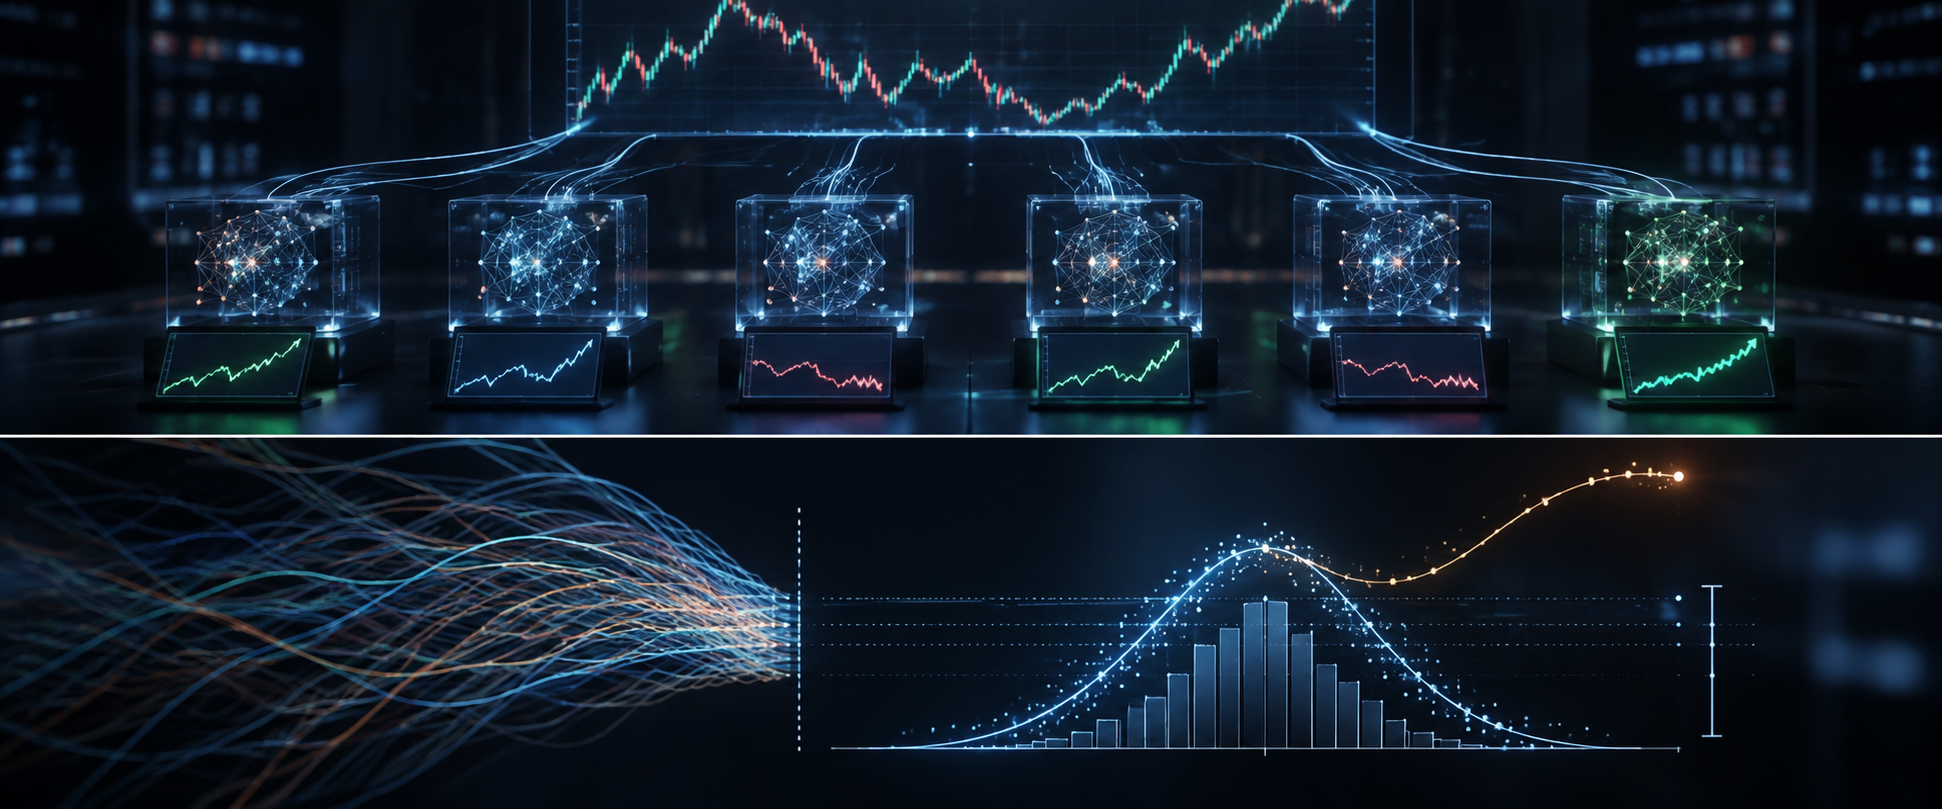
The second validation problem is to assess the robustness and reproducibility of the model's evidence for economic value. A strong backtest does not automatically prove the validity of the model. Financial data can be easily overused through changes in features, models, hyperparameters, objectives, training windows, or decision rules. This leads to the risk of spurious predictability, where statistically significant-looking backtests emerge even in synthetic environments without genuine predictability.
Furthermore, stochastic components in modern ML systems can lead to substantial variation in Sharpe ratios between training runs. The same model configuration can yield different results when trained multiple times with different random seeds. Selecting the best-performing seed or reporting only the mean Sharpe ratio can inflate the reported performance, creating multiplicity bias. This is a major difference that can arise without discovering a better model architecture or market signal.
In summary, validating financial machine learning models requires more than just considering prediction accuracy and backtest results. It necessitates a comprehensive evaluation process that accounts for the economic value of predictions, the robustness and reproducibility of the model's evidence, and the potential multiplicity bias in the training process.
Written by urgent.news from HackerNoon's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.