Building a Production CI/CD Pipline for Machine Learning Models Across Distributed Industrial Plants
Industrial ML deployment is different from cloud CI/CD. Learn how site-aware validation, versioned models, staged rollouts, and rollback protect live processes.
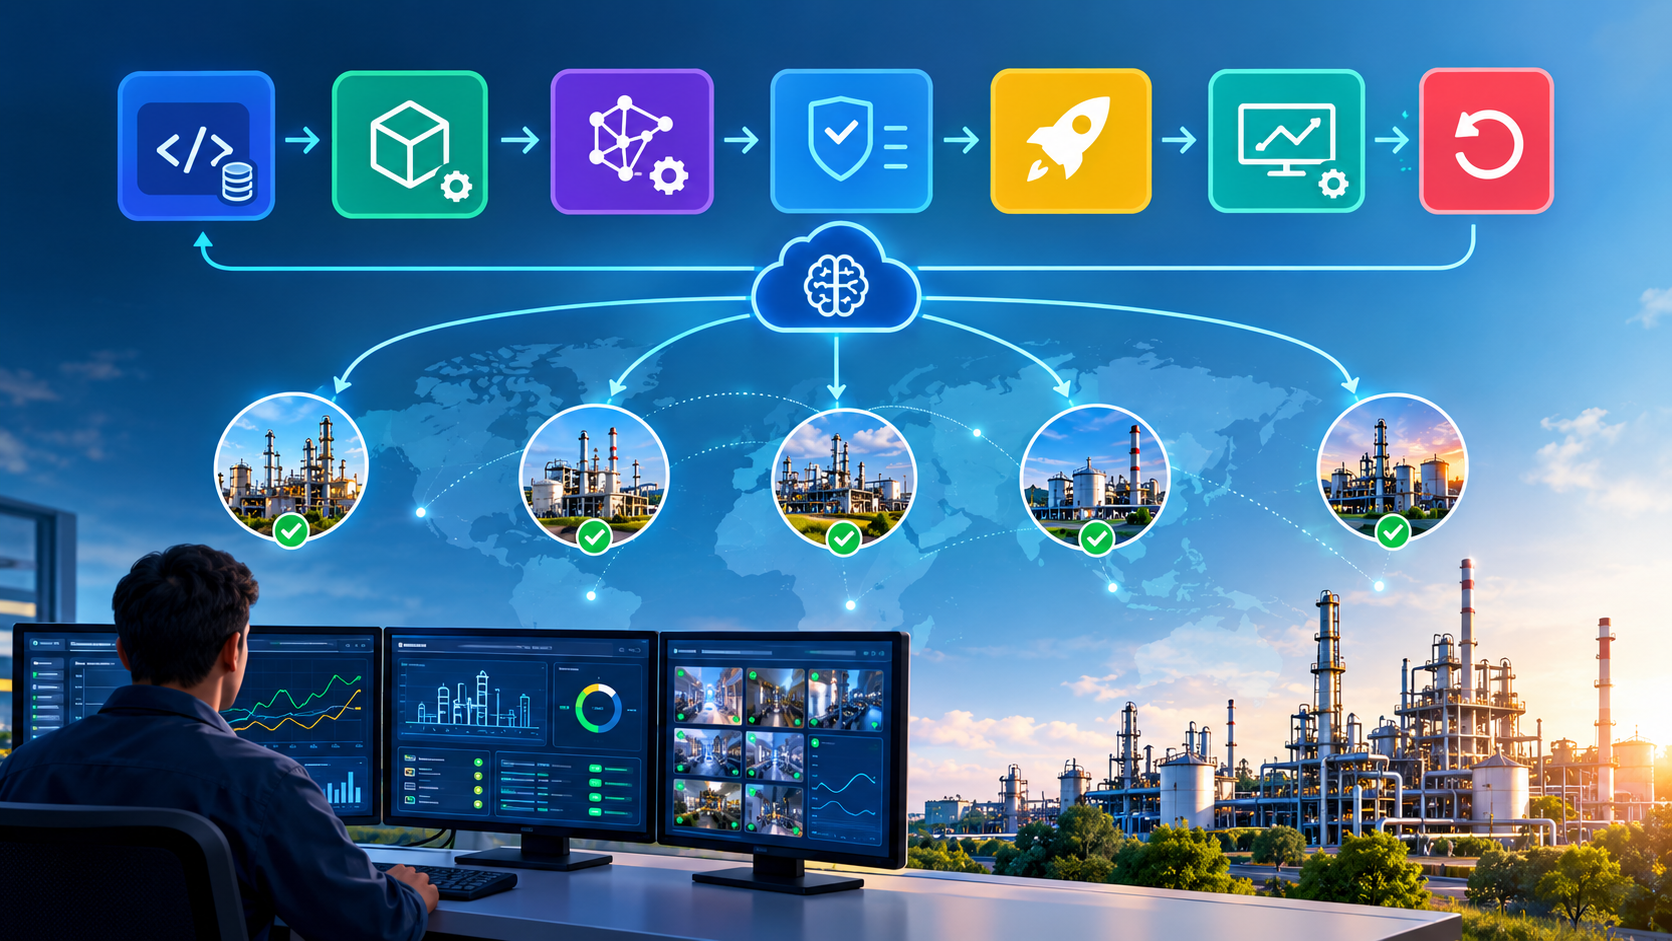
Building an automated, version-controlled, phased CI/CD pipeline for deploying machine learning models across multiple industrial plants proved challenging due to their distinct sensor calibrations, historical process data, and unique change control expectations. Unlike deploying models to cloud regions, the model and its site-specific configuration must be versioned together, not the model alone.
A validation gate must be site-aware to ensure the model's accuracy for a specific site's sensor calibration or operating range.
The pipeline's stages include model versioning, where the model and its site-specific configuration are versioned together; automated validation, which ensures the model's performance before deployment; staged canary-style rollout, starting with a pilot site and gradually expanding to the entire fleet; and a rollback mechanism for when a model underperforms in production.
With the new pipeline, deploy time decreased significantly, and model reuse across sites became a reality. However, the improvement was reported as a directional result, and the results should not be considered independently verified.
Written by urgent.news from HackerNoon's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.