ChatGPT, Claude, Grok, and Gemini overrate facial attractiveness compared to human judges
Artificial intelligence is surprisingly good at ranking human beauty, but a new study finds it systematically overrates facial attractiveness. The findings suggest that AI might be too polite to be an objective judge of our looks.
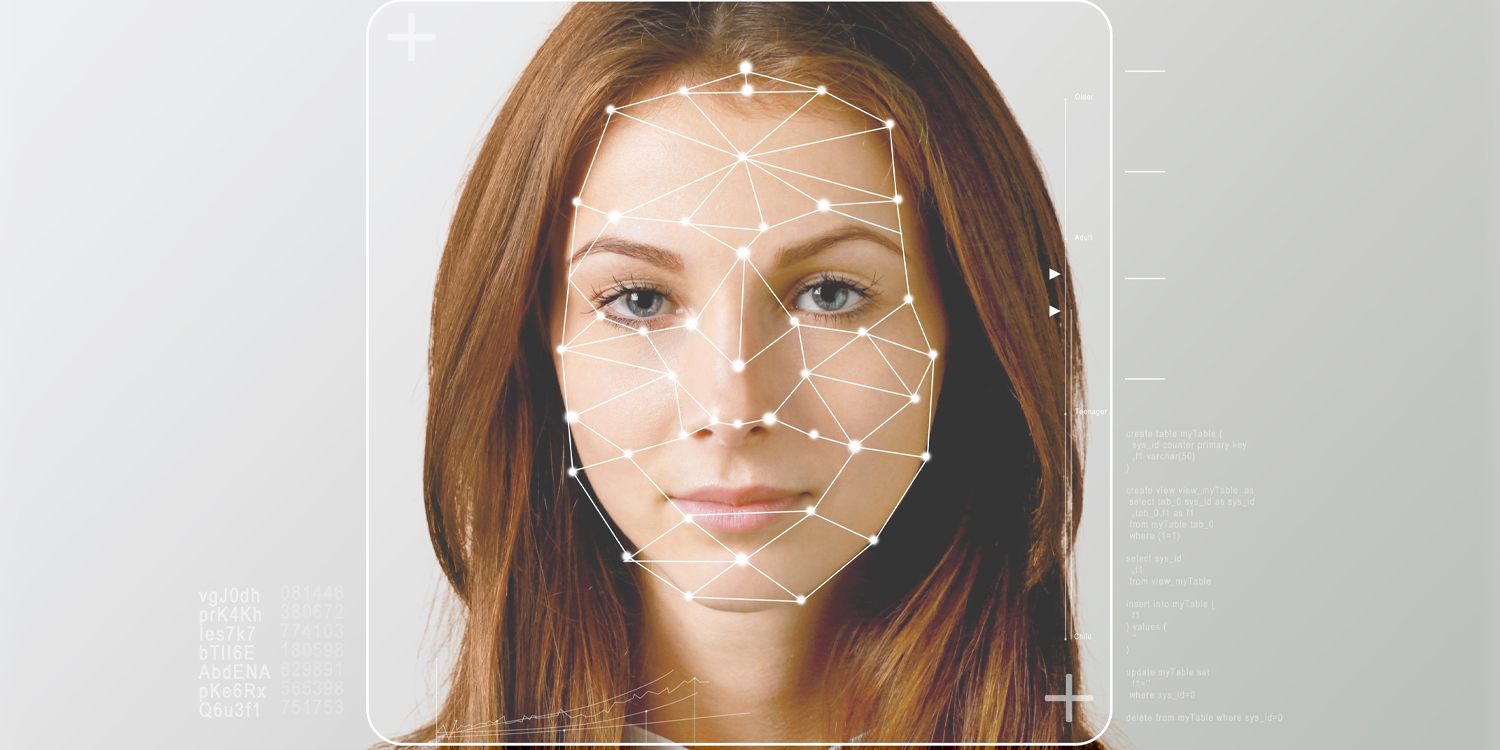
Artificial intelligence systems like ChatGPT, Claude, Grok, and Gemini are impressively adept at mimicking human judgments of facial attractiveness, but they consistently overrate faces on a numerical scale compared to human raters. This indicates AI models can grasp relative beauty, yet they systematically inflate attractiveness ratings beyond average human standards.
Published as a preprint on arXiv, the study reveals that while AI captures the relative order of attractiveness, it systematically overestimates how attractive faces are on an absolute scale. Facial attractiveness, a psychological trait, varies based on shared preferences for traits like symmetry and youth, as well as individual tastes.
Demographic differences also impact perceptions, with studies showing that on average, women are rated as more attractive than men. Researchers led by Santiago Grandas, head of psychological research at QOVES, sought to determine whether modern AI models evaluate faces similarly to humans. Multimodal large language models (MLLMs), trained on extensive internet data, interpret facial features through accompanying captions and text rather than purely as pixels.
During the study, the group tested ChatGPT, Claude, Gemini, and Grok's ability to replicate human judgments using the same standardized dataset of 102 images. These images represented both male and female faces from various ethnic backgrounds and had received average attractiveness ratings from over 2,500 human participants on a 1-7 scale.
Across all AI models, their average rating was markedly higher at 4.71, compared to human participants' average rating of 3.02. Notably, AI models rarely assigned the lowest possible rating of 1, whereas humans used the full scale. Grok stood out as an outlier, giving the highest average scores at 5.21 and showing the weakest agreement with both other AI models and human judges.
Written by urgent.news from PsyPost's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.
This story
This is one outlet's version. Read the fullest account.