AI Agents Don't Need More Memory. They Need Better State Management.
AI agents don’t need more memory. They need better state management to handle current truth, concurrency, workflows, recovery, and real-world actions.
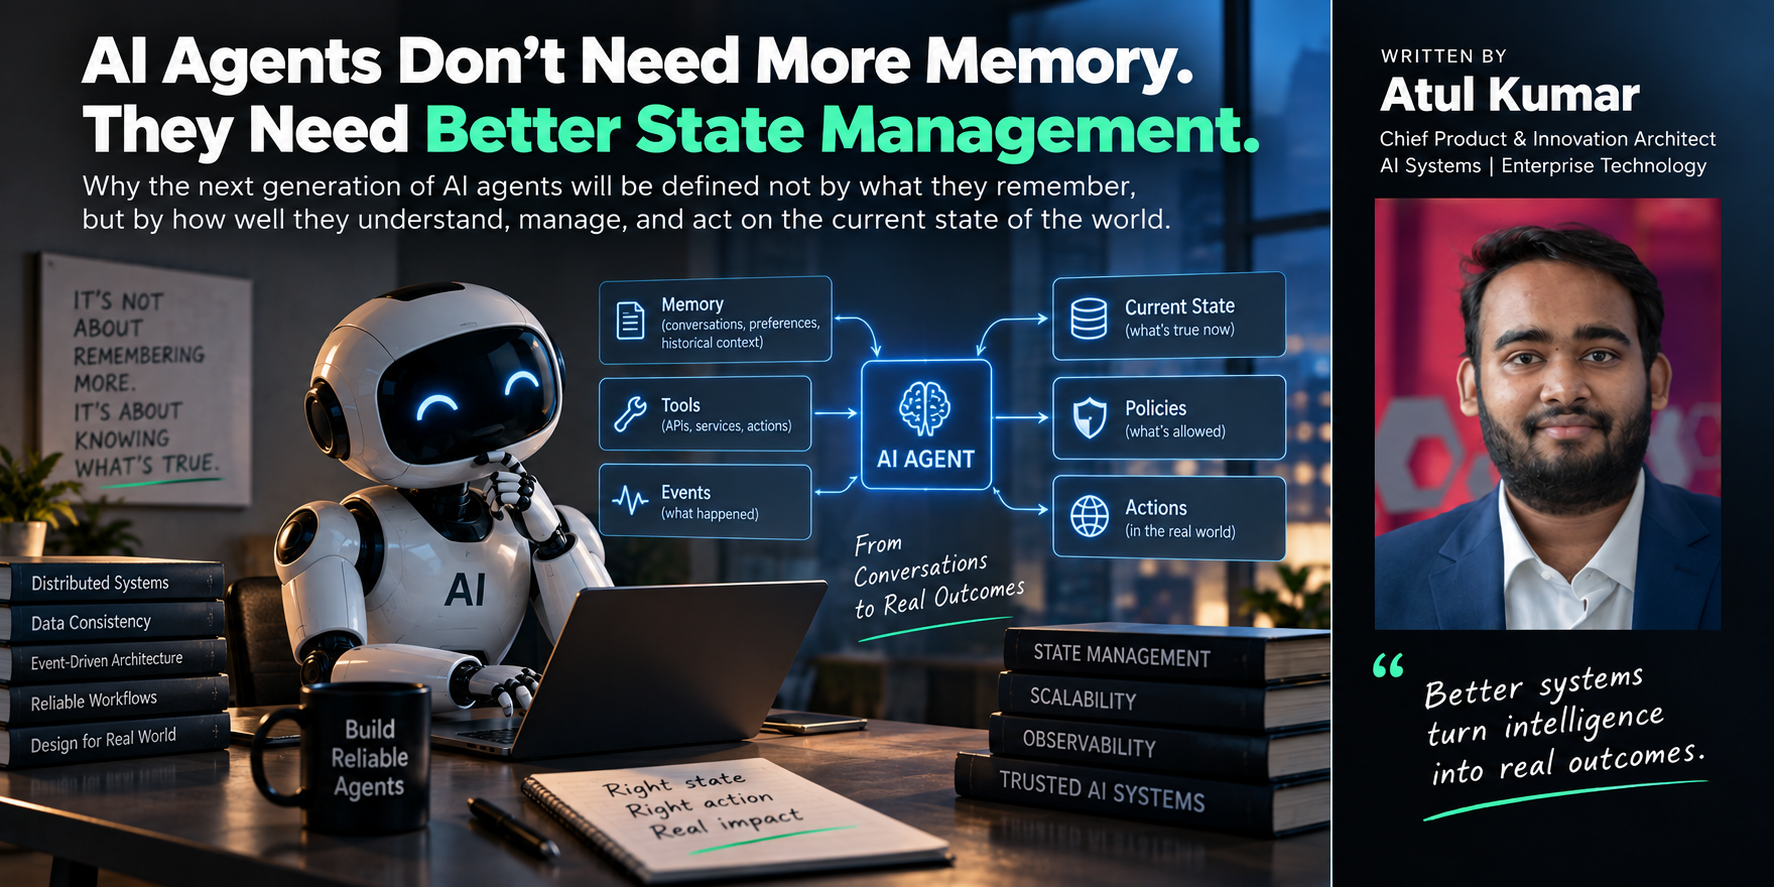
When AI agents encounter situations where they forget information, the first instinct is often to increase their memory capacity. This might involve storing lengthy conversations, expanding context windows, or implementing vector databases. However, adding more memory does not necessarily solve the underlying issue. As AI agents transition from conversational interfaces to performing real-world tasks, the focus shifts towards better state management.
Consider an agent handling a customer refund scenario. The customer requests a refund, the agent checks the order, communicates with the payment service, and eventually receives a timeout. After retrying, the agent gets a response indicating that the refund was accepted. Later, when the customer asks if the refund has been completed, the agent may remember the entire conversation, as well as the fact that it is called the refund API, and even retrieve the response stating that the request was accepted.
Nonetheless, this information does not necessarily confirm that the money has been refunded. The payment system holds the authoritative record of the refund status. This distinction becomes crucial as AI agents operate in production environments.
The core issue lies not in the agent's inability to remember sufficient information, but rather in its lack of understanding of which information represents the current truth. To address this, researchers are exploring various approaches, such as separating stateless models from stateful runtimes or implementing state-aware runtimes with transactional state activation and recovery mechanisms. However, the fundamental distinction remains - memory should not be the sole solution for all AI agent challenges.
Part of the confusion stems from the term "memory," which encompasses a wide range of information types. User preferences can persist for months, while payment authorizations may only remain valid for seconds. Workflow checkpoints need to survive process restarts, while retrieved documents may be relevant for only one decision. Tool responses could become obsolete after a single transaction alters the underlying system.
Labeling all these elements as memory obscures their distinct properties and the most crucial question: what does each piece of information truly signify?
Conversations provide insight into what someone said, but they do not necessarily convey the system's beliefs about what is useful in the past. Workflow states indicate the current status of an execution, while authoritative business systems reflect the actual truth about business entities. These concepts are not interchangeable, and conflating them can lead to significant problems, especially as language models excel at generating coherent interpretations from the information provided.
The model's ability to produce coherent responses from diverse data sources can create a false sense of confidence, even when relying on stale information. For example, when determining if a customer's subscription is active, a semantic search system might retrieve various records, such as past conversations, invoices, or support tickets, all of which are highly relevant to the question.
However, they do not necessarily reflect the subscription's current status. In such cases, the subscription service holds the authoritative status, not the model.
This situation highlights an important distinction: relevance does not equate to truth. Retrieval systems, like vector databases, can be incredibly valuable for gathering relevant context and historical information. They excel at answering questions like "What information looks relevant to this query?" However, they do not inherently answer the crucial question of "Which system currently owns the truth about this entity?" This distinction is vital for autonomous AI agents to make informed decisions and coordinate actions.
To summarize, AI agents should not rely solely on increased memory capacity to address forgetting issues. Instead, the focus should shift towards better state management. Understanding the difference between various information types, such as conversation transcripts, semantic memories, workflow states, authoritative business systems, and retrieval systems, is essential.
By recognizing that the model is not the database and that the truth lies within specific systems, AI agents can make more accurate and reliable decisions in real-world scenarios.
Written by urgent.news from HackerNoon's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.