Why i'm still bearish on LLMs after Navier-Stokes
In this analysis, I present several reasons why the author remains skeptical about the capabilities of large language models (LLMs) after the Navier-Stokes incident. The author begins by sharing a few theses for readers to consider. Taken together, these theses suggest that for most domains, LLMs will continue to function like a "cracked intern": they may be quick and effective when in the hands of an adult, but they should not be given free rein.
Most firms will not be able to adopt fully autonomous AI due to structural issues arising from current architectures, skill limitations, or slow technology diffusion.
The author identifies three classes of firms that can handle fully autonomous LLMs: price-sensitive companies, which may not require the significant improvement in reasoning quality seen when transitioning from cheaper to frontier models; and two other classes. In the first of these latter classes, the type of fuzzy combinatorial search that has produced headline results in mathematics and security research appears to be more sensitive to agentic swarm width than to reasoning capacity.
The author cites small open models that have reproduced headline CVEs as evidence. For this class, the author argues that using cheap open models that enable wider swarms would be more advantageous.
The third class of firms may still utilize frontier models, but it is unclear whether their work could not be accomplished with cheaper models like DeepSeek V4.1 Flash. The author suggests that the swarm width advantage observed in this class further supports the use of cheaper models. The author also notes that firms in this class often keep their intellectual property (IP) very secretive and may be reluctant to share it with companies like Anthropic and OpenAI, even with agreements not to train on user data.
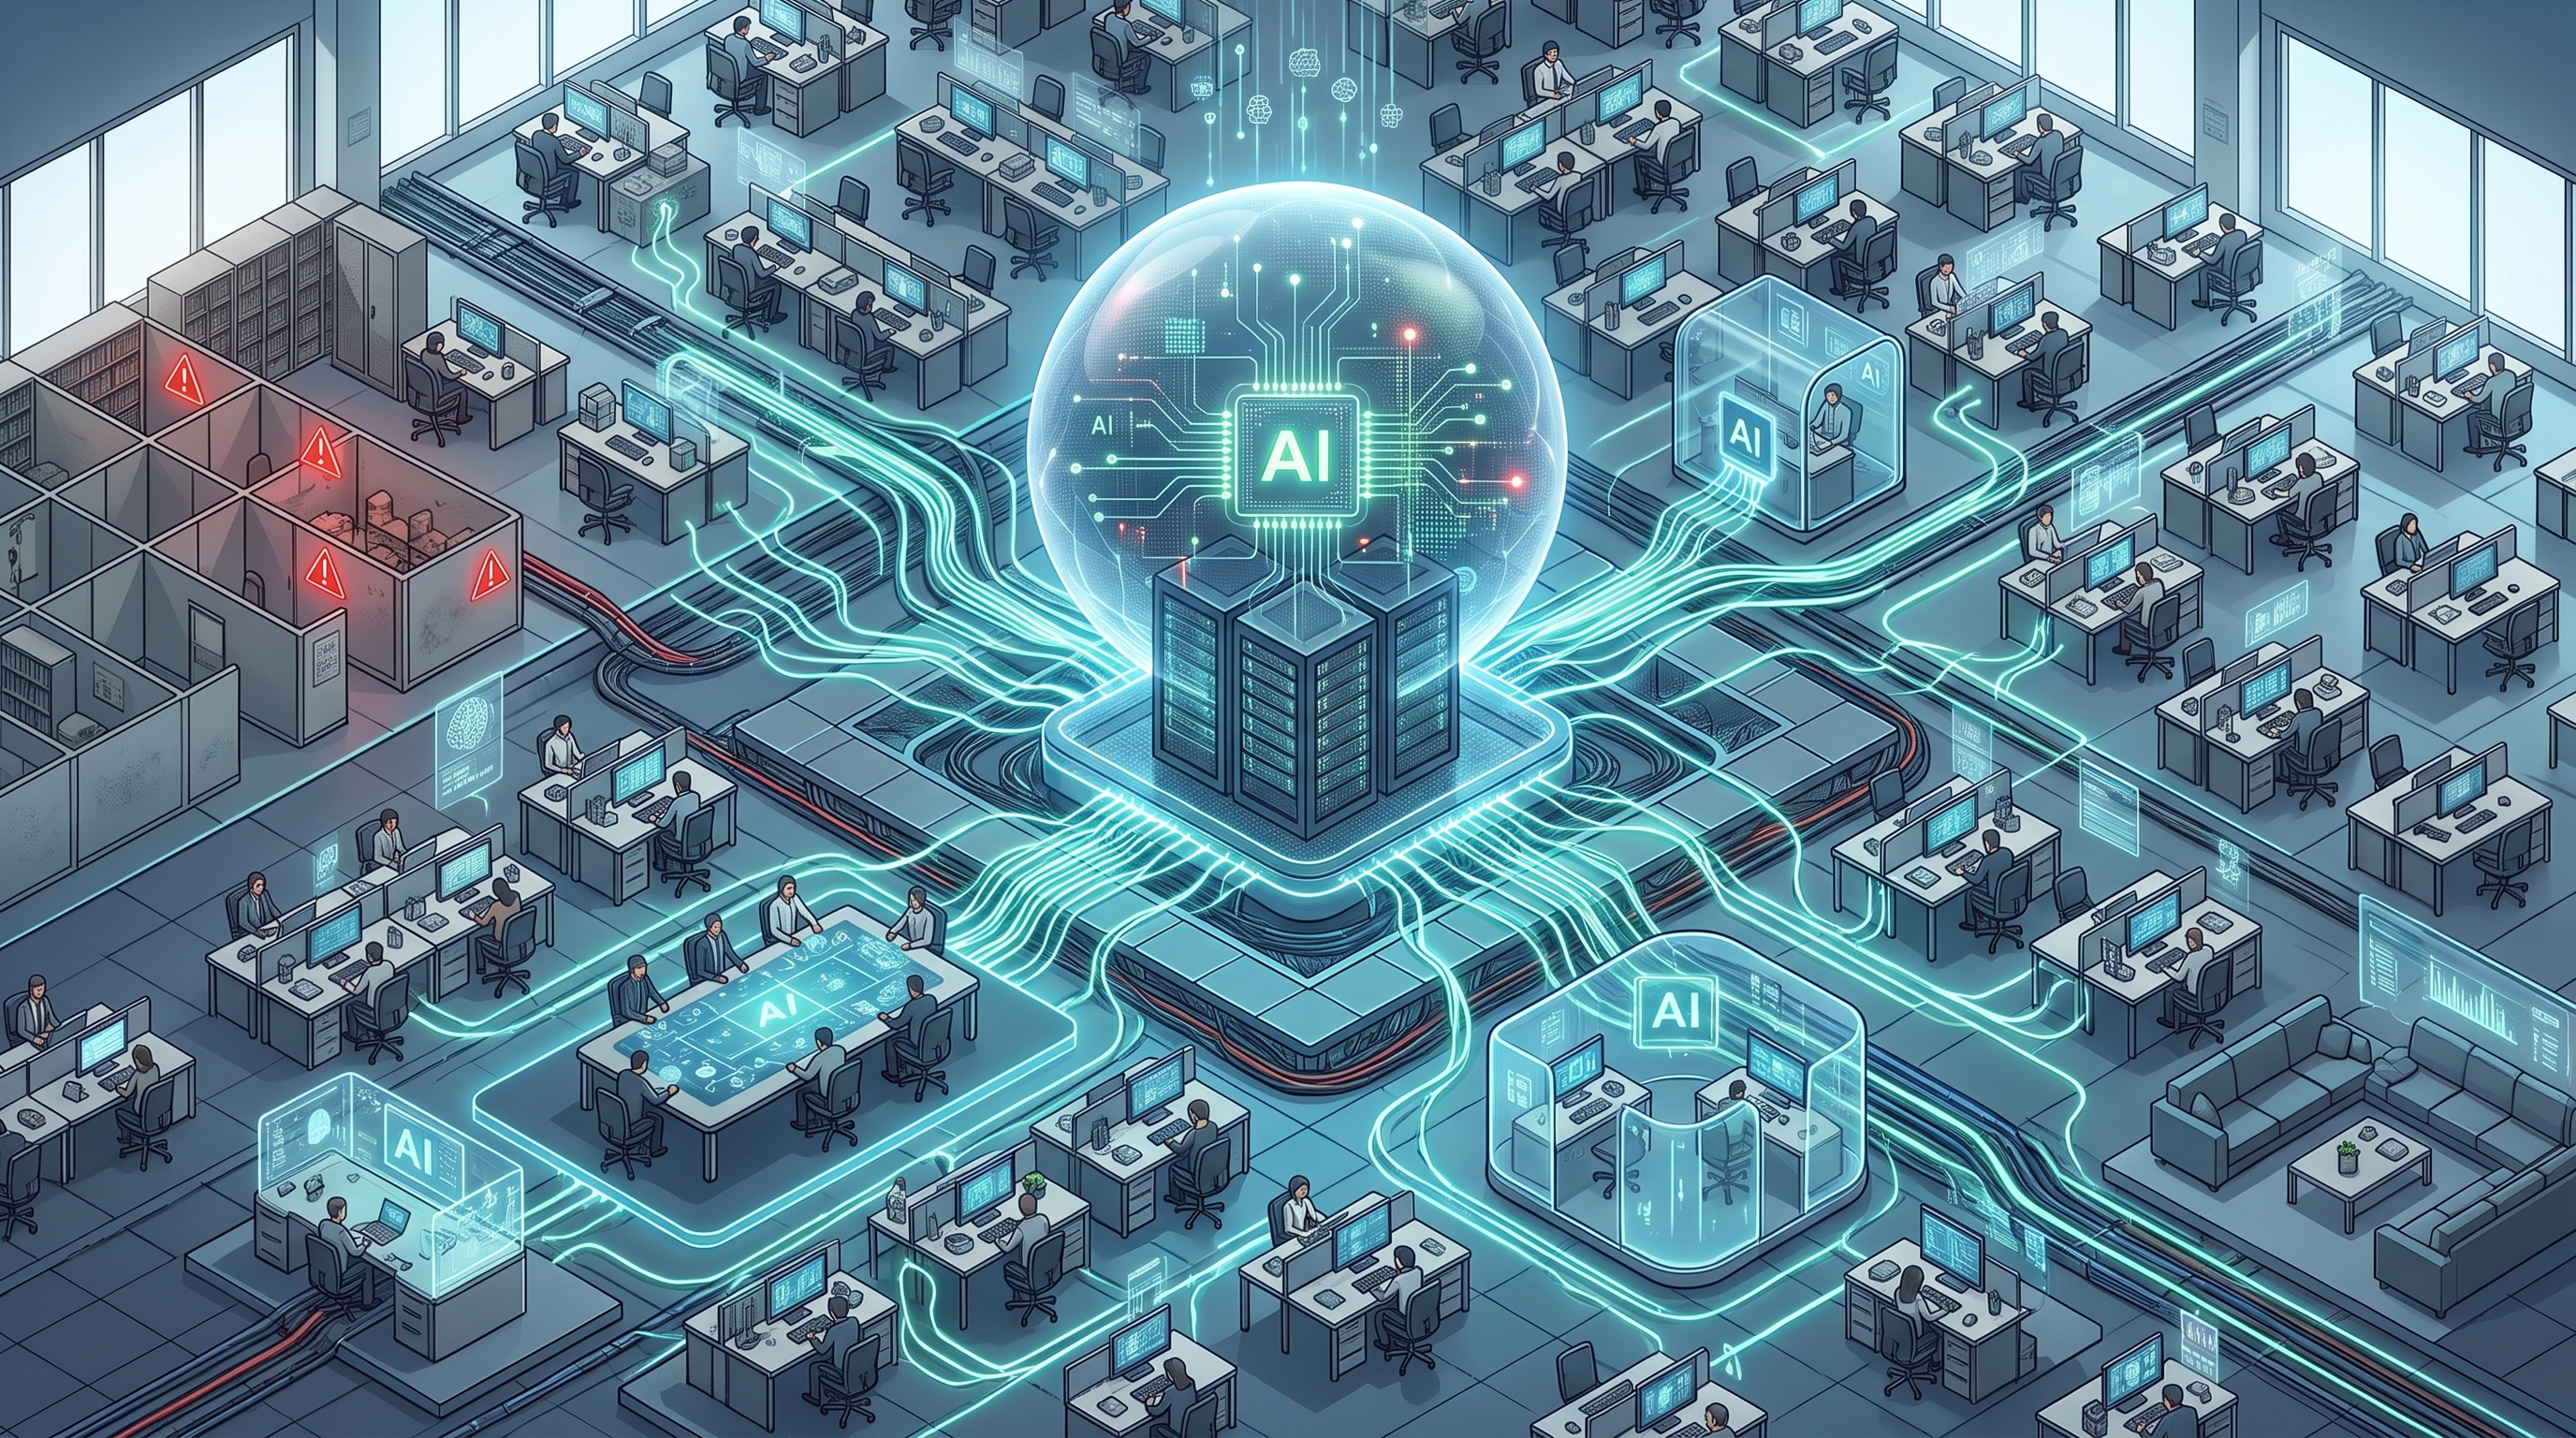
A comparison between the data center full of geniuses scenario and the one filled with "brainlets" is presented. The former would be self-driving and only limited by the compute available, while the latter would be heavily bottlenecked by human orchestrators. The author believes the blast radius of this scenario will extend far beyond the frontier labs.
Written by urgent.news from Lobsters's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.