The AI Inference Revolution Is Here
Since about 2020, AI has largely focused on training bigger and better models. Large language models (LLMs) ballooned from millions of parameters to trillions. This proved effective: The largest version of OpenAI’s GPT-3, released in 2020, correctly answered just 43.9 percent of questions on a popular knowledge-and-reasoning benchmark. Just four years later, GPT-4o reached a score of 88.7 percent…
Since approximately 2020, the primary focus of AI has shifted from training larger and more sophisticated models to utilizing them for tasks such as code generation, essay writing, and creating images of ourselves as elves. This shift is evident in the significant improvement in large language models (LLMs), such as OpenAI's GPT-3 and its successor, GPT-4o, which have demonstrated proficiency comparable to human experts on knowledge-and-reasoning benchmarks.
While researchers continue to train ever larger models, the spotlight has now turned to inference—the application of trained models to produce outputs. Analyst Matt Kimball asserts that "all that any chief information officer wants to talk about is inference." The inflection point of inference was highlighted by Nvidia CEO Jensen Huang during his address at the GTC 2026 conference.
Several factors have contributed to this shift, including the growing utility of LLMs and the emergence of reasoning models that employ multiple inference runs to refine their responses. Additionally, the increasing prominence of agentic AI has resulted in continuous inference, running in the background to achieve user-defined objectives.
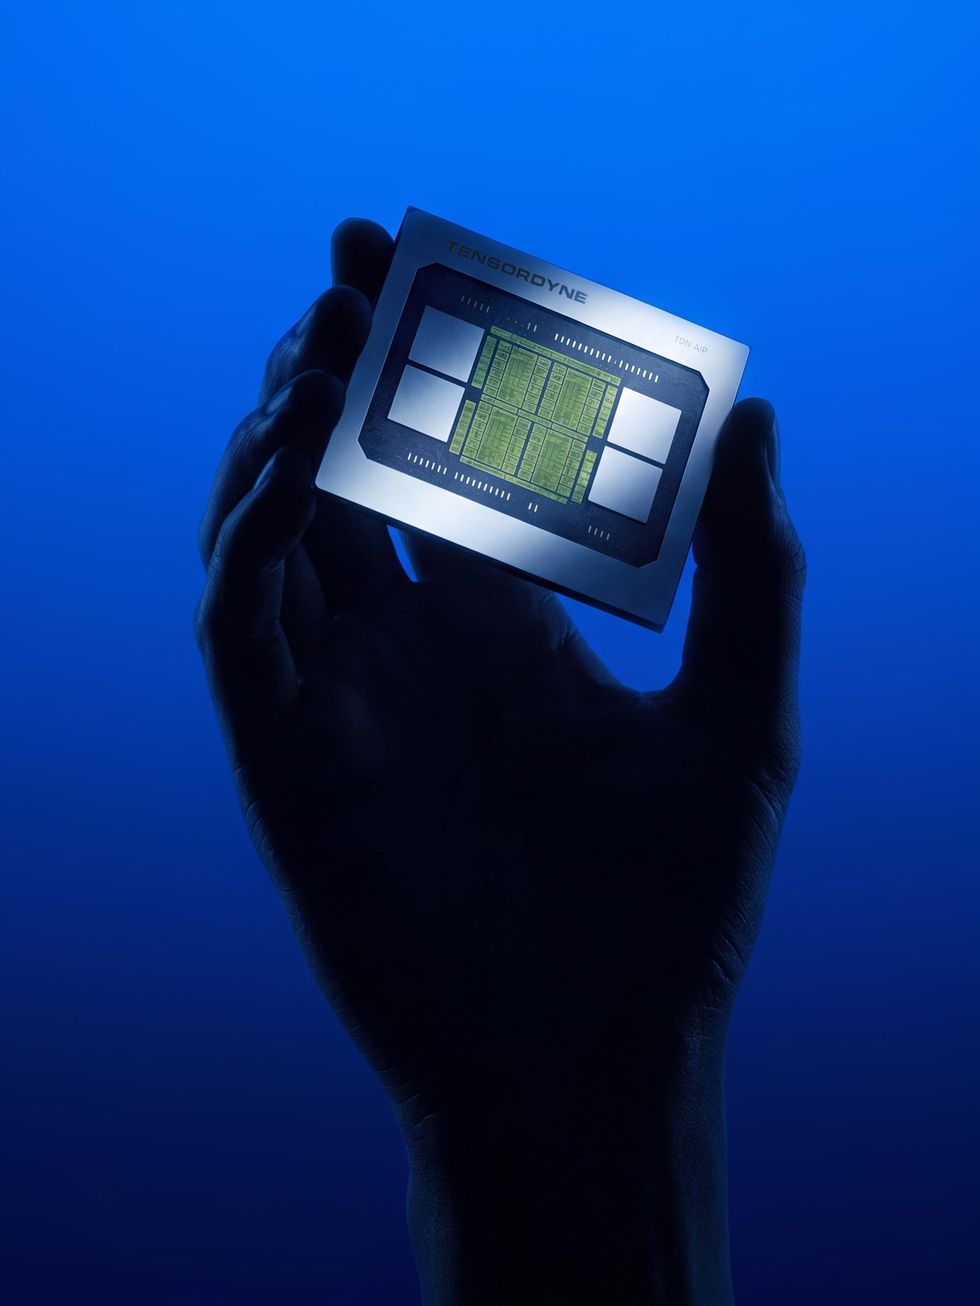
Chip manufacturers have responded to this surge in inference demand by crafting specialized hardware. Amazon's Trainium chip, originally intended for AI training, has been repurposed, with computational-intensive tasks handled by Trainium and memory-intensive tasks managed by Cerebras's wafer-scale engine. This division has led to strategic alliances among major tech companies.
For instance, OpenAI and Amazon have collaborated on deploying Cerebras chips, despite Amazon's own Trainium lineup. Nvidia has acquired the expertise and technology from AI-inference startup Groq in a $20 billion deal, while Anthropic has entered into a multi-billion-dollar monthly agreement with SpaceXAI to lease additional computational resources.
Despite these seemingly similar domains, AI training and AI inference involve distinct computational processes. While training organizes the model's "scrabble tiles"—the tokens—through a large-scale guessing game with billions of passages, inference uses these pre-trained models to generate sensible sequences of tokens. However, inference's computational demands are substantial due to its autoregressive nature, requiring the processing of all previous context, prompts, and LLM outputs.
This intricate interplay of computational tasks underscores the evolving landscape of AI hardware and the necessity for new architectures to meet the growing inference demands.
Written by urgent.news from IEEE Spectrum's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.