Why defensibility is the hook for VC data center investments
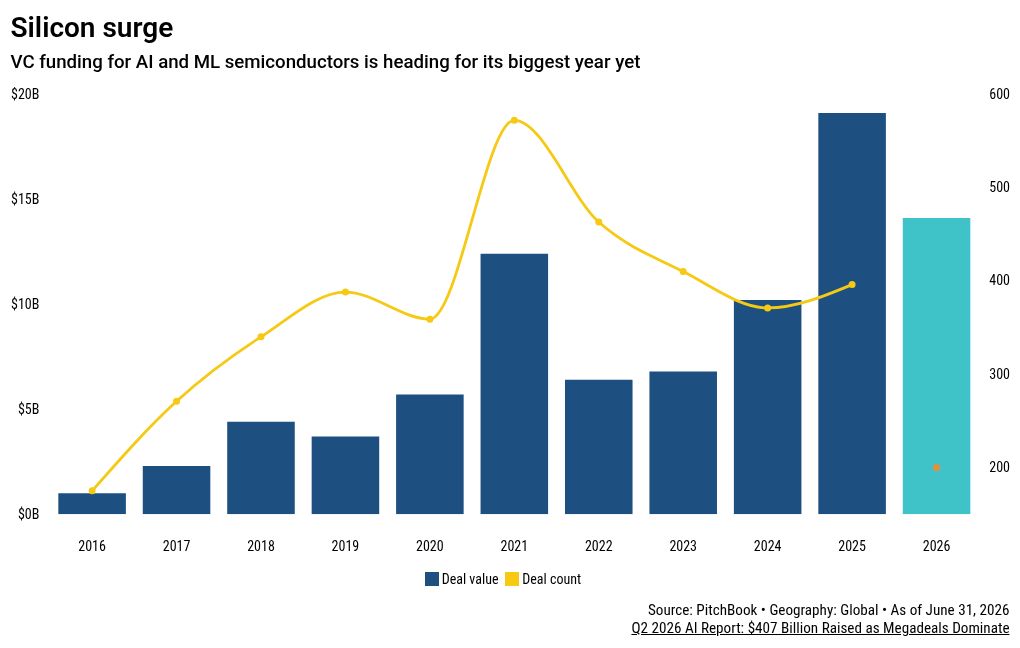
Defensibility is the key factor driving venture capital investments in data center infrastructure for artificial intelligence. Nvidia recently secured agreements with six major asset managers and investment banks, aiming to raise capital for AI factories. This demonstrates the growing demand for AI infrastructure, with global funding for AI and machine learning semiconductors reaching $14.1 billion in the first half of the year.
VCs are backing this expansion by investing in the semiconductors that power AI. The sector's growth trajectory is facing bottlenecks that cannot be resolved through software improvements alone. Hardware, specifically semiconductors, offers real defensibility in this rapidly evolving market. The base-case estimate from McKinsey suggests the industry could reach $1.6 trillion in revenue by the end of the decade.
VCs are capitalizing on the increasing number of constraints facing AI, such as limited supply and demand outpacing capacity. In Q1 and Q2 of this year, deal count and investment in AI semiconductors surpassed 2023's figures. Specialization is becoming a key advantage, with startups focusing on specific stages of the computing process, like decode and prefill chips.
This specialization strategy is gaining traction, as companies like Etched, Olix, and Taalas develop chips tailored to specific AI tasks, offering lower energy consumption, faster processing times, and enhanced computing power.
Written by urgent.news from Yahoo Finance's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.