Reducing MTTR: A Practical Guide to Correlating Incidents with AIOps
AI-driven incident correlation helps SRE and DevOps teams reduce alert noise, identify root causes faster and improve MTTR by connecting related metrics, logs and traces.
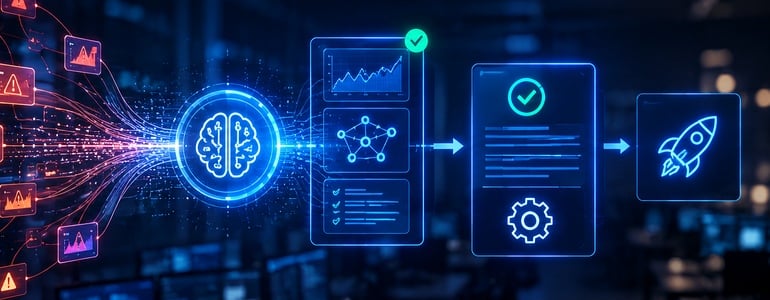
When a payment service begins throwing errors at 2 a.m., the observability stack generates 40 alerts within minutes. These alerts include elevated latency on three services, a spike in 5xx errors, a memory warning on a downstream cache, and dependency timeouts. Identifying the underlying cause manually from the overwhelming alert noise can turn a 5-minute fix into a 45-minute outage.
AIOps was designed to address this challenge, not to introduce additional dashboards or alerts. Correlation is the key to transforming an alert storm into a single, prioritized incident with a probable root cause. This guide will explain how correlation functions, how to set it up with your existing observability stack, and how to measure its impact on mean time to resolution (MTTR).
To embark on this process, ensure you have an observability stack that produces metrics, logs, and traces (such as StackGen’s ObserveNow or a Prometheus/Grafana/Loki/Jaeger setup), existing alerting in place, admin access for integration and rule configuration, and a recent incident with alert history for testing. The setup process takes about 30–45 minutes initially, followed by 1–2 weeks of tuning based on real incidents.
Connection of your observability stack is crucial for AI-driven correlation. Make sure your metrics, logs, and traces share common context like service names, environments, and trace IDs. In ObserveNow, this integration is straightforward, as it works directly with your existing Prometheus, Loki, and Jaeger instances. Once unified telemetry is established, configure AI-driven correlation rules.
Two main approaches are employed: topology-aware correlation, utilizing service dependency maps to group related alerts, and pattern-based correlation, learning from historical incident data to identify co-occurring alerts. Set a time window of 5 minutes as a starting point for most microservice architectures, adjusting as needed based on your service coupling and failure propagation speed.
The result should be alerts grouped into incidents rather than appearing as separate tickets. Before finalizing your setup, test it against a real incident. Evaluate whether the correlation engine accurately groups relevant alerts, identifies probable root causes, and excludes unrelated data points. Additionally, validate that the automated root cause analysis accurately pinpoints the earliest anomaly and ranks potential causes within the correlated group.
Written by urgent.news from DevOps.com's reporting — not their text. Machine-written — may contain errors; check the original before relying on it.